AI Engineering Coach
From c6ea6a88dab55eab7224777b22c326bb22f132c0 Mon Sep 17 00:00:00 2001
From: Marco Olivo <8478776+olivomarco@users.noreply.github.com>
Date: Wed, 24 Jun 2026 13:29:35 +0200
Subject: [PATCH 02/13] Refine documentation on context management and model
selection to clarify cache stability and cost implications during long
sessions
---
docs/04-context-management.md | 6 ------
docs/11-models-and-pricing.md | 5 -----
2 files changed, 11 deletions(-)
diff --git a/docs/04-context-management.md b/docs/04-context-management.md
index aabac02..6709d64 100644
--- a/docs/04-context-management.md
+++ b/docs/04-context-management.md
@@ -168,15 +168,9 @@ Most teams have it inverted — everything in always-on. Flipping the ratio cuts
The cheapest token is the one the platform doesn't have to re-process. Modern Copilot interactions cache stable portions of context (system prompt, instruction files, recently-loaded files) so they don't pay the full input-token cost on every turn.
-<<<<<<< HEAD
In long sessions, this is often the biggest single cost lever. When most of your input is cache-hit input, effective input cost can drop dramatically (commonly cited as up to ~90% discount on cached input, depending on provider/model/surface billing rules).
You can lean into this. Two practical patterns:
-||||||| parent of 68607d7 (Enhance documentation on `/chronicle` commands for token optimization and add VS Code settings for improved UI customization)
-You can lean into this. Two practical patterns:
-=======
-You can lean into this. Three practical patterns:
->>>>>>> 68607d7 (Enhance documentation on `/chronicle` commands for token optimization and add VS Code settings for improved UI customization)
**1. Stable instructions at the top, volatile work at the bottom.** Cached context only works if the prefix of your conversation is stable. Don't reshuffle your `copilot-instructions.md` or rotate which files are open between every prompt — keep the stable layer stable, and let only the most recent message change.
diff --git a/docs/11-models-and-pricing.md b/docs/11-models-and-pricing.md
index 03b2863..58b1f13 100644
--- a/docs/11-models-and-pricing.md
+++ b/docs/11-models-and-pricing.md
@@ -123,13 +123,8 @@ This is especially relevant when comparing a cheap reasoning-capable model at `m
- Leaving an expensive premium model pinned for the whole session
- Changing models mid-chat in a long session without thinking about accumulated context. Prior messages, tool results, and cacheable prefixes can still be part of the next request; switching into a higher-cost lane can make that carried context more expensive than starting fresh
-<<<<<<< HEAD
- Enabling/disabling MCP servers mid-thread in long sessions. Tool-surface changes often invalidate stable cached prefixes
- Switching default/custom agent profiles mid-thread during expensive runs. Agent/profile changes can break cache continuity for the same conversation
-||||||| parent of 68607d7 (Enhance documentation on `/chronicle` commands for token optimization and add VS Code settings for improved UI customization)
-=======
-- Switching the **custom agent** or toggling **MCP servers / tools** mid-session. Like a model switch, this rewrites the cacheable prefix (system prompt, tool definitions, instructions), so cache savings are forfeited and prior context becomes pollution under the new setup. See [Caching §2.3.5](04-context-management.md#235-caching-store-and-reuse-context-within-prompts)
->>>>>>> 68607d7 (Enhance documentation on `/chronicle` commands for token optimization and add VS Code settings for improved UI customization)
- Assuming Auto will escalate to Opus when a task gets hard
- Using vendor API prices and Copilot pricing signals as if they were the same metric
- Recommending a model without checking whether the plan includes it
From 3f3126f793af933ba57a505e085f241ff187daa9 Mon Sep 17 00:00:00 2001
From: Marco Olivo <8478776+olivomarco@users.noreply.github.com>
Date: Sun, 12 Jul 2026 12:45:31 +0200
Subject: [PATCH 03/13] Add excalidraw skill
---
.github/skills/excalidraw-diagram/SKILL.md | 552 +++++++++++++++++++++
1 file changed, 552 insertions(+)
create mode 100644 .github/skills/excalidraw-diagram/SKILL.md
diff --git a/.github/skills/excalidraw-diagram/SKILL.md b/.github/skills/excalidraw-diagram/SKILL.md
new file mode 100644
index 0000000..9df9894
--- /dev/null
+++ b/.github/skills/excalidraw-diagram/SKILL.md
@@ -0,0 +1,552 @@
+---
+name: excalidraw-diagram
+description: Create Excalidraw diagram JSON files that make visual arguments. Use when the user wants to visualize workflows, architectures, or concepts.
+---
+
+# Excalidraw Diagram Creator
+
+Generate `.excalidraw` JSON files that **argue visually**, not just display information.
+
+**Setup:** If the user asks you to set up this skill (renderer, dependencies, etc.), see `README.md` for instructions.
+
+## Customization
+
+**All colors and brand-specific styles live in one file:** `references/color-palette.md`. Read it before generating any diagram and use it as the single source of truth for all color choices — shape fills, strokes, text colors, evidence artifact backgrounds, everything.
+
+To make this skill produce diagrams in your own brand style, edit `color-palette.md`. Everything else in this file is universal design methodology and Excalidraw best practices.
+
+---
+
+## Core Philosophy
+
+**Diagrams should ARGUE, not DISPLAY.**
+
+A diagram isn't formatted text. It's a visual argument that shows relationships, causality, and flow that words alone can't express. The shape should BE the meaning.
+
+**The Isomorphism Test**: If you removed all text, would the structure alone communicate the concept? If not, redesign.
+
+**The Education Test**: Could someone learn something concrete from this diagram, or does it just label boxes? A good diagram teaches—it shows actual formats, real event names, concrete examples.
+
+---
+
+## Depth Assessment (Do This First)
+
+Before designing, determine what level of detail this diagram needs:
+
+### Simple/Conceptual Diagrams
+Use abstract shapes when:
+- Explaining a mental model or philosophy
+- The audience doesn't need technical specifics
+- The concept IS the abstraction (e.g., "separation of concerns")
+
+### Comprehensive/Technical Diagrams
+Use concrete examples when:
+- Diagramming a real system, protocol, or architecture
+- The diagram will be used to teach or explain (e.g., YouTube video)
+- The audience needs to understand what things actually look like
+- You're showing how multiple technologies integrate
+
+**For technical diagrams, you MUST include evidence artifacts** (see below).
+
+---
+
+## Research Mandate (For Technical Diagrams)
+
+**Before drawing anything technical, research the actual specifications.**
+
+If you're diagramming a protocol, API, or framework:
+1. Look up the actual JSON/data formats
+2. Find the real event names, method names, or API endpoints
+3. Understand how the pieces actually connect
+4. Use real terminology, not generic placeholders
+
+Bad: "Protocol" → "Frontend"
+Good: "AG-UI streams events (RUN_STARTED, STATE_DELTA, A2UI_UPDATE)" → "CopilotKit renders via createA2UIMessageRenderer()"
+
+**Research makes diagrams accurate AND educational.**
+
+---
+
+## Evidence Artifacts
+
+Evidence artifacts are concrete examples that prove your diagram is accurate and help viewers learn. Include them in technical diagrams.
+
+**Types of evidence artifacts** (choose what's relevant to your diagram):
+
+| Artifact Type | When to Use | How to Render |
+|---------------|-------------|---------------|
+| **Code snippets** | APIs, integrations, implementation details | Dark rectangle + syntax-colored text (see color palette for evidence artifact colors) |
+| **Data/JSON examples** | Data formats, schemas, payloads | Dark rectangle + colored text (see color palette) |
+| **Event/step sequences** | Protocols, workflows, lifecycles | Timeline pattern (line + dots + labels) |
+| **UI mockups** | Showing actual output/results | Nested rectangles mimicking real UI |
+| **Real input content** | Showing what goes IN to a system | Rectangle with sample content visible |
+| **API/method names** | Real function calls, endpoints | Use actual names from docs, not placeholders |
+
+**Example**: For a diagram about a streaming protocol, you might show:
+- The actual event names from the spec (not just "Event 1", "Event 2")
+- A code snippet showing how to connect
+- What the streamed data actually looks like
+
+**Example**: For a diagram about a data transformation pipeline:
+- Show sample input data (actual format, not "Input")
+- Show sample output data (actual format, not "Output")
+- Show intermediate states if relevant
+
+The key principle: **show what things actually look like**, not just what they're called.
+
+---
+
+## Multi-Zoom Architecture
+
+Comprehensive diagrams operate at multiple zoom levels simultaneously. Think of it like a map that shows both the country borders AND the street names.
+
+### Level 1: Summary Flow
+A simplified overview showing the full pipeline or process at a glance. Often placed at the top or bottom of the diagram.
+
+*Example*: `Input → Processing → Output` or `Client → Server → Database`
+
+### Level 2: Section Boundaries
+Labeled regions that group related components. These create visual "rooms" that help viewers understand what belongs together.
+
+*Example*: Grouping by responsibility (Backend / Frontend), by phase (Setup / Execution / Cleanup), or by team (User / System / External)
+
+### Level 3: Detail Inside Sections
+Evidence artifacts, code snippets, and concrete examples within each section. This is where the educational value lives.
+
+*Example*: Inside a "Backend" section, you might show the actual API response format, not just a box labeled "API Response"
+
+**For comprehensive diagrams, aim to include all three levels.** The summary gives context, the sections organize, and the details teach.
+
+### Bad vs Good
+
+| Bad (Displaying) | Good (Arguing) |
+|------------------|----------------|
+| 5 equal boxes with labels | Each concept has a shape that mirrors its behavior |
+| Card grid layout | Visual structure matches conceptual structure |
+| Icons decorating text | Shapes that ARE the meaning |
+| Same container for everything | Distinct visual vocabulary per concept |
+| Everything in a box | Free-floating text with selective containers |
+
+### Simple vs Comprehensive (Know Which You Need)
+
+| Simple Diagram | Comprehensive Diagram |
+|----------------|----------------------|
+| Generic labels: "Input" → "Process" → "Output" | Specific: shows what the input/output actually looks like |
+| Named boxes: "API", "Database", "Client" | Named boxes + examples of actual requests/responses |
+| "Events" or "Messages" label | Timeline with real event/message names from the spec |
+| "UI" or "Dashboard" rectangle | Mockup showing actual UI elements and content |
+| ~30 seconds to explain | ~2-3 minutes of teaching content |
+| Viewer learns the structure | Viewer learns the structure AND the details |
+
+**Simple diagrams** are fine for abstract concepts, quick overviews, or when the audience already knows the details. **Comprehensive diagrams** are needed for technical architectures, tutorials, educational content, or when you want the diagram itself to teach.
+
+---
+
+## Container vs. Free-Floating Text
+
+**Not every piece of text needs a shape around it.** Default to free-floating text. Add containers only when they serve a purpose.
+
+| Use a Container When... | Use Free-Floating Text When... |
+|------------------------|-------------------------------|
+| It's the focal point of a section | It's a label or description |
+| It needs visual grouping with other elements | It's supporting detail or metadata |
+| Arrows need to connect to it | It describes something nearby |
+| The shape itself carries meaning (decision diamond, etc.) | Typography alone creates sufficient hierarchy |
+| It represents a distinct "thing" in the system | It's a section title, subtitle, or annotation |
+
+**Typography as hierarchy**: Use font size, weight, and color to create visual hierarchy without boxes. A 28px title doesn't need a rectangle around it.
+
+**The container test**: For each boxed element, ask "Would this work as free-floating text?" If yes, remove the container.
+
+---
+
+## Design Process (Do This BEFORE Generating JSON)
+
+### Step 0: Assess Depth Required
+Before anything else, determine if this needs to be:
+- **Simple/Conceptual**: Abstract shapes, labels, relationships (mental models, philosophies)
+- **Comprehensive/Technical**: Concrete examples, code snippets, real data (systems, architectures, tutorials)
+
+**If comprehensive**: Do research first. Look up actual specs, formats, event names, APIs.
+
+### Step 1: Understand Deeply
+Read the content. For each concept, ask:
+- What does this concept **DO**? (not what IS it)
+- What relationships exist between concepts?
+- What's the core transformation or flow?
+- **What would someone need to SEE to understand this?** (not just read about)
+
+### Step 2: Map Concepts to Patterns
+For each concept, find the visual pattern that mirrors its behavior:
+
+| If the concept... | Use this pattern |
+|-------------------|------------------|
+| Spawns multiple outputs | **Fan-out** (radial arrows from center) |
+| Combines inputs into one | **Convergence** (funnel, arrows merging) |
+| Has hierarchy/nesting | **Tree** (lines + free-floating text) |
+| Is a sequence of steps | **Timeline** (line + dots + free-floating labels) |
+| Loops or improves continuously | **Spiral/Cycle** (arrow returning to start) |
+| Is an abstract state or context | **Cloud** (overlapping ellipses) |
+| Transforms input to output | **Assembly line** (before → process → after) |
+| Compares two things | **Side-by-side** (parallel with contrast) |
+| Separates into phases | **Gap/Break** (visual separation between sections) |
+
+### Step 3: Ensure Variety
+For multi-concept diagrams: **each major concept must use a different visual pattern**. No uniform cards or grids.
+
+### Step 4: Sketch the Flow
+Before JSON, mentally trace how the eye moves through the diagram. There should be a clear visual story.
+
+### Step 5: Generate JSON
+Only now create the Excalidraw elements. **See below for how to handle large diagrams.**
+
+### Step 6: Render & Validate (MANDATORY)
+After generating the JSON, you MUST run the render-view-fix loop until the diagram looks right. This is not optional — see the **Render & Validate** section below for the full process.
+
+---
+
+## Large / Comprehensive Diagram Strategy
+
+**For comprehensive or technical diagrams, you MUST build the JSON one section at a time.** Do NOT attempt to generate the entire file in a single pass. This is a hard constraint — Claude Code has a ~32,000 token output limit per response, and a comprehensive diagram easily exceeds that in one shot. Even if it didn't, generating everything at once leads to worse quality. Section-by-section is better in every way.
+
+### The Section-by-Section Workflow
+
+**Phase 1: Build each section**
+
+1. **Create the base file** with the JSON wrapper (`type`, `version`, `appState`, `files`) and the first section of elements.
+2. **Add one section per edit.** Each section gets its own dedicated pass — take your time with it. Think carefully about the layout, spacing, and how this section connects to what's already there.
+3. **Use descriptive string IDs** (e.g., `"trigger_rect"`, `"arrow_fan_left"`) so cross-section references are readable.
+4. **Namespace seeds by section** (e.g., section 1 uses 100xxx, section 2 uses 200xxx) to avoid collisions.
+5. **Update cross-section bindings** as you go. When a new section's element needs to bind to an element from a previous section (e.g., an arrow connecting sections), edit the earlier element's `boundElements` array at the same time.
+
+**Phase 2: Review the whole**
+
+After all sections are in place, read through the complete JSON and check:
+- Are cross-section arrows bound correctly on both ends?
+- Is the overall spacing balanced, or are some sections cramped while others have too much whitespace?
+- Do IDs and bindings all reference elements that actually exist?
+
+Fix any alignment or binding issues before rendering.
+
+**Phase 3: Render & validate**
+
+Now run the render-view-fix loop from the Render & Validate section. This is where you'll catch visual issues that aren't obvious from JSON — overlaps, clipping, imbalanced composition.
+
+### Section Boundaries
+
+Plan your sections around natural visual groupings from the diagram plan. A typical large diagram might split into:
+
+- **Section 1**: Entry point / trigger
+- **Section 2**: First decision or routing
+- **Section 3**: Main content (hero section — may be the largest single section)
+- **Section 4-N**: Remaining phases, outputs, etc.
+
+Each section should be independently understandable: its elements, internal arrows, and any cross-references to adjacent sections.
+
+### What NOT to Do
+
+- **Don't generate the entire diagram in one response.** You will hit the output token limit and produce truncated, broken JSON. Even if the diagram is small enough to fit, splitting into sections produces better results.
+- **Don't use a coding agent** to generate the JSON. The agent won't have sufficient context about the skill's rules, and the coordination overhead negates any benefit.
+- **Don't write a Python generator script.** The templating and coordinate math seem helpful but introduce a layer of indirection that makes debugging harder. Hand-crafted JSON with descriptive IDs is more maintainable.
+
+---
+
+## Visual Pattern Library
+
+### Fan-Out (One-to-Many)
+Central element with arrows radiating to multiple targets. Use for: sources, PRDs, root causes, central hubs.
+```
+ ○
+ ↗
+ □ → ○
+ ↘
+ ○
+```
+
+### Convergence (Many-to-One)
+Multiple inputs merging through arrows to single output. Use for: aggregation, funnels, synthesis.
+```
+ ○ ↘
+ ○ → □
+ ○ ↗
+```
+
+### Tree (Hierarchy)
+Parent-child branching with connecting lines and free-floating text (no boxes needed). Use for: file systems, org charts, taxonomies.
+```
+ label
+ ├── label
+ │ ├── label
+ │ └── label
+ └── label
+```
+Use `line` elements for the trunk and branches, free-floating text for labels.
+
+### Spiral/Cycle (Continuous Loop)
+Elements in sequence with arrow returning to start. Use for: feedback loops, iterative processes, evolution.
+```
+ □ → □
+ ↑ ↓
+ □ ← □
+```
+
+### Cloud (Abstract State)
+Overlapping ellipses with varied sizes. Use for: context, memory, conversations, mental states.
+
+### Assembly Line (Transformation)
+Input → Process Box → Output with clear before/after. Use for: transformations, processing, conversion.
+```
+ ○○○ → [PROCESS] → □□□
+ chaos order
+```
+
+### Side-by-Side (Comparison)
+Two parallel structures with visual contrast. Use for: before/after, options, trade-offs.
+
+### Gap/Break (Separation)
+Visual whitespace or barrier between sections. Use for: phase changes, context resets, boundaries.
+
+### Lines as Structure
+Use lines (type: `line`, not arrows) as primary structural elements instead of boxes:
+- **Timelines**: Vertical or horizontal line with small dots (10-20px ellipses) at intervals, free-floating labels beside each dot
+- **Tree structures**: Vertical trunk line + horizontal branch lines, with free-floating text labels (no boxes needed)
+- **Dividers**: Thin dashed lines to separate sections
+- **Flow spines**: A central line that elements relate to, rather than connecting boxes
+
+```
+Timeline: Tree:
+ ●─── Label 1 │
+ │ ├── item
+ ●─── Label 2 │ ├── sub
+ │ │ └── sub
+ ●─── Label 3 └── item
+```
+
+Lines + free-floating text often creates a cleaner result than boxes + contained text.
+
+---
+
+## Shape Meaning
+
+Choose shape based on what it represents—or use no shape at all:
+
+| Concept Type | Shape | Why |
+|--------------|-------|-----|
+| Labels, descriptions, details | **none** (free-floating text) | Typography creates hierarchy |
+| Section titles, annotations | **none** (free-floating text) | Font size/weight is enough |
+| Markers on a timeline | small `ellipse` (10-20px) | Visual anchor, not container |
+| Start, trigger, input | `ellipse` | Soft, origin-like |
+| End, output, result | `ellipse` | Completion, destination |
+| Decision, condition | `diamond` | Classic decision symbol |
+| Process, action, step | `rectangle` | Contained action |
+| Abstract state, context | overlapping `ellipse` | Fuzzy, cloud-like |
+| Hierarchy node | lines + text (no boxes) | Structure through lines |
+
+**Rule**: Default to no container. Add shapes only when they carry meaning. Aim for <30% of text elements to be inside containers.
+
+---
+
+## Color as Meaning
+
+Colors encode information, not decoration. Every color choice should come from `references/color-palette.md` — the semantic shape colors, text hierarchy colors, and evidence artifact colors are all defined there.
+
+**Key principles:**
+- Each semantic purpose (start, end, decision, AI, error, etc.) has a specific fill/stroke pair
+- Free-floating text uses color for hierarchy (titles, subtitles, details — each at a different level)
+- Evidence artifacts (code snippets, JSON examples) use their own dark background + colored text scheme
+- Always pair a darker stroke with a lighter fill for contrast
+
+**Do not invent new colors.** If a concept doesn't fit an existing semantic category, use Primary/Neutral or Secondary.
+
+---
+
+## Modern Aesthetics
+
+For clean, professional diagrams:
+
+### Roughness
+- `roughness: 0` — Clean, crisp edges. Use for modern/technical diagrams.
+- `roughness: 1` — Hand-drawn, organic feel. Use for brainstorming/informal diagrams.
+
+**Default to 0** for most professional use cases.
+
+### Stroke Width
+- `strokeWidth: 1` — Thin, elegant. Good for lines, dividers, subtle connections.
+- `strokeWidth: 2` — Standard. Good for shapes and primary arrows.
+- `strokeWidth: 3` — Bold. Use sparingly for emphasis (main flow line, key connections).
+
+### Opacity
+**Always use `opacity: 100` for all elements.** Use color, size, and stroke width to create hierarchy instead of transparency.
+
+### Small Markers Instead of Shapes
+Instead of full shapes, use small dots (10-20px ellipses) as:
+- Timeline markers
+- Bullet points
+- Connection nodes
+- Visual anchors for free-floating text
+
+---
+
+## Layout Principles
+
+### Hierarchy Through Scale
+- **Hero**: 300×150 - visual anchor, most important
+- **Primary**: 180×90
+- **Secondary**: 120×60
+- **Small**: 60×40
+
+### Whitespace = Importance
+The most important element has the most empty space around it (200px+).
+
+### Flow Direction
+Guide the eye: typically left→right or top→bottom for sequences, radial for hub-and-spoke.
+
+### Connections Required
+Position alone doesn't show relationships. If A relates to B, there must be an arrow.
+
+---
+
+## Text Rules
+
+**CRITICAL**: The JSON `text` property contains ONLY readable words.
+
+```json
+{
+ "id": "myElement1",
+ "text": "Start",
+ "originalText": "Start"
+}
+```
+
+Settings: `fontSize: 16`, `fontFamily: 3`, `textAlign: "center"`, `verticalAlign: "middle"`
+
+---
+
+## JSON Structure
+
+```json
+{
+ "type": "excalidraw",
+ "version": 2,
+ "source": "https://excalidraw.com",
+ "elements": [...],
+ "appState": {
+ "viewBackgroundColor": "#ffffff",
+ "gridSize": 20
+ },
+ "files": {}
+}
+```
+
+## Element Templates
+
+See `references/element-templates.md` for copy-paste JSON templates for each element type (text, line, dot, rectangle, arrow). Pull colors from `references/color-palette.md` based on each element's semantic purpose.
+
+---
+
+## Render & Validate (MANDATORY)
+
+You cannot judge a diagram from JSON alone. After generating or editing the Excalidraw JSON, you MUST render it to PNG, view the image, and fix what you see — in a loop until it's right. This is a core part of the workflow, not a final check.
+
+### How to Render
+
+```bash
+cd .claude/skills/excalidraw-diagram/references && uv run python render_excalidraw.py
+```
+
+This outputs a PNG next to the `.excalidraw` file. Then use the **Read tool** on the PNG to actually view it.
+
+### The Loop
+
+After generating the initial JSON, run this cycle:
+
+**1. Render & View** — Run the render script, then Read the PNG.
+
+**2. Audit against your original vision** — Before looking for bugs, compare the rendered result to what you designed in Steps 1-4. Ask:
+- Does the visual structure match the conceptual structure you planned?
+- Does each section use the pattern you intended (fan-out, convergence, timeline, etc.)?
+- Does the eye flow through the diagram in the order you designed?
+- Is the visual hierarchy correct — hero elements dominant, supporting elements smaller?
+- For technical diagrams: are the evidence artifacts (code snippets, data examples) readable and properly placed?
+
+**3. Check for visual defects:**
+- Text clipped by or overflowing its container
+- Text or shapes overlapping other elements
+- Arrows crossing through elements instead of routing around them
+- Arrows landing on the wrong element or pointing into empty space
+- Labels floating ambiguously (not clearly anchored to what they describe)
+- Uneven spacing between elements that should be evenly spaced
+- Sections with too much whitespace next to sections that are too cramped
+- Text too small to read at the rendered size
+- Overall composition feels lopsided or unbalanced
+
+**4. Fix** — Edit the JSON to address everything you found. Common fixes:
+- Widen containers when text is clipped
+- Adjust `x`/`y` coordinates to fix spacing and alignment
+- Add intermediate waypoints to arrow `points` arrays to route around elements
+- Reposition labels closer to the element they describe
+- Resize elements to rebalance visual weight across sections
+
+**5. Re-render & re-view** — Run the render script again and Read the new PNG.
+
+**6. Repeat** — Keep cycling until the diagram passes both the vision check (Step 2) and the defect check (Step 3). Typically takes 2-4 iterations. Don't stop after one pass just because there are no critical bugs — if the composition could be better, improve it.
+
+### When to Stop
+
+The loop is done when:
+- The rendered diagram matches the conceptual design from your planning steps
+- No text is clipped, overlapping, or unreadable
+- Arrows route cleanly and connect to the right elements
+- Spacing is consistent and the composition is balanced
+- You'd be comfortable showing it to someone without caveats
+
+### First-Time Setup
+If the render script hasn't been set up yet:
+```bash
+cd .claude/skills/excalidraw-diagram/references
+uv sync
+uv run playwright install chromium
+```
+
+---
+
+## Quality Checklist
+
+### Depth & Evidence (Check First for Technical Diagrams)
+1. **Research done**: Did you look up actual specs, formats, event names?
+2. **Evidence artifacts**: Are there code snippets, JSON examples, or real data?
+3. **Multi-zoom**: Does it have summary flow + section boundaries + detail?
+4. **Concrete over abstract**: Real content shown, not just labeled boxes?
+5. **Educational value**: Could someone learn something concrete from this?
+
+### Conceptual
+6. **Isomorphism**: Does each visual structure mirror its concept's behavior?
+7. **Argument**: Does the diagram SHOW something text alone couldn't?
+8. **Variety**: Does each major concept use a different visual pattern?
+9. **No uniform containers**: Avoided card grids and equal boxes?
+
+### Container Discipline
+10. **Minimal containers**: Could any boxed element work as free-floating text instead?
+11. **Lines as structure**: Are tree/timeline patterns using lines + text rather than boxes?
+12. **Typography hierarchy**: Are font size and color creating visual hierarchy (reducing need for boxes)?
+
+### Structural
+13. **Connections**: Every relationship has an arrow or line
+14. **Flow**: Clear visual path for the eye to follow
+15. **Hierarchy**: Important elements are larger/more isolated
+
+### Technical
+16. **Text clean**: `text` contains only readable words
+17. **Font**: `fontFamily: 3`
+18. **Roughness**: `roughness: 0` for clean/modern (unless hand-drawn style requested)
+19. **Opacity**: `opacity: 100` for all elements (no transparency)
+20. **Container ratio**: <30% of text elements should be inside containers
+
+### Visual Validation (Render Required)
+21. **Rendered to PNG**: Diagram has been rendered and visually inspected
+22. **No text overflow**: All text fits within its container
+23. **No overlapping elements**: Shapes and text don't overlap unintentionally
+24. **Even spacing**: Similar elements have consistent spacing
+25. **Arrows land correctly**: Arrows connect to intended elements without crossing others
+26. **Readable at export size**: Text is legible in the rendered PNG
+27. **Balanced composition**: No large empty voids or overcrowded regions
From 72d0edddd3e815e851793bf1b2a2161448c447f1 Mon Sep 17 00:00:00 2001
From: Marco Olivo <8478776+olivomarco@users.noreply.github.com>
Date: Sun, 12 Jul 2026 13:13:07 +0200
Subject: [PATCH 04/13] Add outcome per token
---
.vscode/settings.json | 15 --
README.md | 20 +-
docs/04-context-management.md | 43 +++
docs/06-workflow-optimization.md | 2 +
docs/09-comparisons-data.md | 6 +-
docs/10-practical-setup.md | 38 +++
docs/12-enterprise-governance.md | 4 +
docs/13-outcome-per-token.md | 444 +++++++++++++++++++++++++++++++
docs/index.md | 3 +
mkdocs.yml | 1 +
10 files changed, 555 insertions(+), 21 deletions(-)
delete mode 100644 .vscode/settings.json
create mode 100644 docs/13-outcome-per-token.md
diff --git a/.vscode/settings.json b/.vscode/settings.json
deleted file mode 100644
index 0be68ef..0000000
--- a/.vscode/settings.json
+++ /dev/null
@@ -1,15 +0,0 @@
-{
- "workbench.colorCustomizations": {
- "activityBar.background": "#580D3B",
- "titleBar.activeBackground": "#7B1252",
- "titleBar.activeForeground": "#FFFCFD",
- "titleBar.inactiveBackground": "#580D3B",
- "titleBar.inactiveForeground": "#FFFCFD",
- "statusBar.background": "#580D3B",
- "statusBar.foreground": "#FFFCFD",
- "statusBar.debuggingBackground": "#580D3B",
- "statusBar.debuggingForeground": "#FFFCFD",
- "statusBar.noFolderBackground": "#580D3B",
- "statusBar.noFolderForeground": "#FFFCFD"
- }
-}
\ No newline at end of file
diff --git a/README.md b/README.md
index 53d2839..904aca2 100644
--- a/README.md
+++ b/README.md
@@ -8,7 +8,7 @@
---
-## Quick Start — 12 Things to Do Right Now
+## Quick Start — 14 Things to Do Right Now
> **June 1, 2026 — Usage-Based Billing (UBB) is live.** GitHub Copilot now bills real tokens (input + output + cached) drawn from pooled AI credits ($30/seat Business, $70/seat Enterprise) instead of request counters. Every technique in this guide translates directly into credit savings — and cache-friendly habits matter more than ever. See [Enterprise Governance](docs/12-enterprise-governance.md) for customer guardrails and [Model Selection & Pricing](docs/11-models-and-pricing.md) for model-cost guidance.
@@ -30,13 +30,14 @@ Don't have time to read the full guide? Do these today and cut your token usage:
| 10 | **Convert rich files to Markdown before AI work** — `.docx`, `.pdf`, `.pptx`, `.xlsx`, HTML, images, audio, video, and ZIPs carry format tax. [Marc Bara's writeup](https://medium.com/@marc.bara.iniesta/your-docx-is-wasting-33-of-your-ai-budget-86a3d229d042) shows the cost; use [Microsoft MarkItDown](https://github.com/microsoft/markitdown) before chat, agent, or RAG ingestion | Reduces noisy input context | 5 minutes |
| 11 | **Run `/chronicle cost tips` and `/chronicle improve` weekly** (**Copilot CLI only**, experimental) — these slash commands work in interactive Copilot CLI sessions (not VS Code), not as a general Copilot Chat feature. `cost tips` analyzes your token spend and suggests reductions; `improve` finds recurring confusion in your CLI session history and generates custom-instruction fixes so the same misread intent stops costing tokens forever | Cuts recurring rework and direct token spend | 2 minutes per run |
| 12 | **Try CodeAct for long tool chains** (**Copilot CLI only**, optional external plugin) — [`copilot-codeact-plugin`](https://github.com/jsturtevant/copilot-codeact-plugin) collapses multi-step tool chains into one sandboxed execution, which can reduce repeated replay of system prompt, prior messages, and tool definitions | Reduces tool-loop replay | 10-15 minutes |
-| 13 | **Plan first, then execute in a fresh session** — use plan mode (CLI) or Ask mode (VS Code) to agree the approach with a strong model, save the plan to `plan.md` or an issue, then run the execution from that plan in a clean session — often with a cheaper model. Reaching the right outcome the first time avoids the expensive rework of an agent coding in the wrong direction. See [Plan First, Then Execute §2.5.9](docs/06-workflow-optimization.md#259-plan-first-then-execute-and-route-the-phases) | Avoids wrong-direction rework; cheaper execution lane | 0 minutes (just sequence the work) |
+| 13 | **Plan first, then execute in a fresh session** — use plan mode (CLI) or Ask mode (VS Code) to agree the approach with a strong model, save the plan to `plan.md` or an issue, then run the execution from that plan in a clean session — often with a cheaper model. Reaching the right outcome the first time avoids the expensive rework of an agent coding in the wrong direction. See [Plan First, Then Execute §2.5.9](docs/06-workflow-optimization.md#259-plan-first-then-execute-and-route-the-phases) and [Outcome per Token](docs/13-outcome-per-token.md) | Avoids wrong-direction rework; cheaper execution lane | 0 minutes (just sequence the work) |
+| 14 | **Build a persistent codebase graph with Graphify** (optional, VS Code + Copilot CLI) — [`graphify`](https://github.com/Graphify-Labs/graphify) maps the repo once with tree-sitter AST and writes `graphify-out/graph.json`; agents query the graph instead of re-reading project files each session. Best for large repos where orientation reads dominate agent input. Install: `uv tool install graphifyy` | Reduces repeated file-read input | 5-10 minutes |
**Looking at this from an enterprise or customer-governance angle instead of an individual setup angle?** Start with [Enterprise Governance](docs/12-enterprise-governance.md). That chapter covers AI-credit budgets, per-user tightening, model-access policy, org instructions, and separate-organization tradeoffs.
*Figures above are scoped to the mechanism named in each row, are not additive, and do not equal total bill reduction.*
-Output control (#1, #2) pays off immediately and compounds — set it once, save on every call. Structural input control (#3, #6) compounds across every interaction. Model routing (#4, #5) reduces cost at the billing tier. Model-specific prompt tuning (#8) cuts waste by improving first-pass quality. MCP audit (#9) eliminates thousands of hidden tokens per agent task. Markdown conversion (#10) removes DOCX/PDF/HTML layout noise before the model ever sees it.
+Output control (#1, #2) pays off immediately and compounds — set it once, save on every call. Structural input control (#3, #6) compounds across every interaction. Model routing (#4, #5) reduces cost at the billing tier. Model-specific prompt tuning (#8) cuts waste by improving first-pass quality. MCP audit (#9) eliminates thousands of hidden tokens per agent task. Markdown conversion (#10) removes DOCX/PDF/HTML layout noise before the model ever sees it. Graph-based navigation (#14) front-loads codebase orientation once, then reuses it across agent sessions.
---
@@ -114,6 +115,14 @@ Dedicated chapter for customer-facing admin guidance: usage-based billing guardr
---
+### Part 4.4: Outcome per Token
+
+Dedicated chapter for the shift from token minimization to value per token: plan-first execution, prompt-skill progression, model routing, benchmark caveats, and day-to-day model choices under usage-based billing.
+
+→ **[Read Part 4.4](docs/13-outcome-per-token.md)**
+
+---
+
Need the glossary, quick terms, tools, or core external links? Go to [Guide Home](docs/index.md).
---
@@ -128,8 +137,9 @@ Ranked by cost impact. Output first — it costs 5× more per token than input.
4. **Audit MCP servers and injected tools** — disable unused servers/extensions, or use a clean coding profile/custom agent, to save 5K-190K tokens per agent task
5. **Auto model selection** — lower-cost default routing plus paid-plan discount on eligible usage, zero effort
6. **Convert rich files to Markdown first** — avoid paying for Word/PDF/HTML layout noise in chat, agent, and RAG workflows
-7. **Retune prompts to the target model** — better first-pass output reduces repeated clarification turns
-8. **Precise prompts** — 20-40% of user-prompt input tokens; more important for quality than raw savings
+7. **Build a persistent codebase graph** — use Graphify on large repos so agents query `graph.json` instead of re-reading structural files every session
+8. **Retune prompts to the target model** — better first-pass output reduces repeated clarification turns
+9. **Precise prompts** — 20-40% of user-prompt input tokens; more important for quality than raw savings
---
diff --git a/docs/04-context-management.md b/docs/04-context-management.md
index 6709d64..82207c9 100644
--- a/docs/04-context-management.md
+++ b/docs/04-context-management.md
@@ -251,6 +251,49 @@ Conversation history accumulates. After 20+ messages, you might have 50K+ tokens
**How to preserve continuity:** Summarize key decisions in your new prompt. "Continuing from auth refactor — we chose JWT over sessions. Now implement refresh tokens."
+## 2.3.7 Persistent Graphs — Replace Per-Session File Reads
+
+The per-session codebase-read pattern is a hidden input cost: every new agent session starts from scratch, re-reading the same structural files to understand imports, call paths, and component layout. On large repos, orientation reads can burn thousands of tokens before the agent makes one useful edit.
+
+[Graphify](https://github.com/Graphify-Labs/graphify) attacks that cost differently from prompt compression. It parses the repo once with tree-sitter AST, writes a persistent `graphify-out/graph.json`, and lets agents query that graph instead of repeatedly reading source files for structure.
+
+```bash
+uv tool install graphifyy
+
+# Build or update the graph in the repo
+graphify .
+
+# Query targeted structure instead of reading broad files
+graphify query "where is auth middleware?"
+graphify explain "UserService"
+graphify path "Router" "Database"
+```
+
+Core outputs:
+
+```text
+graphify-out/
+├── graph.json queryable graph for agents
+├── graph.html interactive visual explorer
+└── GRAPH_REPORT.md human-readable communities, god nodes, and suggested questions
+```
+
+**When this helps most:**
+
+- large codebases where agents routinely start by reading 5-10 files for orientation
+- repeated agent sessions over the same repo
+- cross-file questions where a path/query answer is cheaper than broad file reads
+- teams that can share the same graph build across developers or agents
+
+**When to skip:** tiny repos where the agent reads two files and finishes. The one-time graph build is overhead if there is no repeated navigation cost to amortize.
+
+**Caveats:**
+
+- Code extraction is local and deterministic for the AST pass; optional semantic/deep extraction over docs, PDFs, images, or media may use a configured AI backend.
+- The graph can go stale after large refactors. Rebuild it or use Graphify's update/watch/hook flows where appropriate.
+- `GRAPH_REPORT.md` is generated output. Treat it as a map, not the source of truth.
+- Graphify complements RTK. Graphify reduces repeated codebase-navigation input; RTK compresses verbose shell/tool output.
+
---
**Next:** [Output Control →](05-output-control.md)
diff --git a/docs/06-workflow-optimization.md b/docs/06-workflow-optimization.md
index 080e047..7c58120 100644
--- a/docs/06-workflow-optimization.md
+++ b/docs/06-workflow-optimization.md
@@ -302,6 +302,8 @@ The most expensive tokens are the ones spent reaching a *wrong* outcome: an agen
**Rule of thumb:** plan with the strong model, execute with the cheap one, and put the plan on disk in between. The outcome is reached in fewer total tokens *and* is usually higher quality, because the plan was reviewed before a single line was written.
+For the fuller outcome-per-token frame, skill taxonomy, benchmark caveats, and current model routing matrix, see [Outcome per Token](13-outcome-per-token.md).
+
---
**Next:** [The AGENTS.md Problem →](07-agents-md-problem.md)
diff --git a/docs/09-comparisons-data.md b/docs/09-comparisons-data.md
index d4cb876..149f322 100644
--- a/docs/09-comparisons-data.md
+++ b/docs/09-comparisons-data.md
@@ -75,6 +75,7 @@ The complete comparison of every technique covered in this guide:
| C3 | Progressive on-demand guidance | 60-90% of optional guidance | — | Positive | High | Teams with reusable prompt files |
| C4 | Start new conversations | 80%+ | — | Lose context | Low | Long sessions |
| C5 | Convert non-text files to Markdown first | ~33% on cited PDF example; higher for noisy HTML | — | Improves structure | Low | DOCX, PDF, PPTX, XLSX, images, audio, RAG ingestion |
+| C6 | Precompute codebase graph with [Graphify](https://github.com/Graphify-Labs/graphify) | 6.8×-71.5× claimed for structural navigation tasks | — | Improves targeting | Medium | Large codebases; repeated cross-file agent navigation |
| **Output Control** |
| D1 | Code-only responses | — | 40-70% | Good | Low | Code generation |
| D2 | Structured output (JSON/tables) | — | 30-60% | Depends | Low | Data tasks |
@@ -116,6 +117,8 @@ The complete comparison of every technique covered in this guide:
> C5 source: Marc Bara's [Your .docx Is Wasting 33% of Your AI Budget](https://medium.com/@marc.bara.iniesta/your-docx-is-wasting-33-of-your-ai-budget-86a3d229d042). Use [Microsoft MarkItDown](https://github.com/microsoft/markitdown) when non-text files need to enter an AI workflow.
+> C6 source: [Graphify benchmarks](https://github.com/Graphify-Labs/graphify/blob/main/BENCHMARKS.md) and project documentation. Treat the high-end 71.5× number as structural-navigation best case on large codebases, not a universal savings guarantee.
+
### The Big Winners
If you do nothing else, do these eight. Ranked by impact-to-effort ratio:
@@ -127,7 +130,8 @@ If you do nothing else, do these eight. Ranked by impact-to-effort ratio:
5. **Ask Mode for simple questions** — 60-90% savings by avoiding Agent overhead
6. **Audit MCP servers** — disable unused servers, save 5K-190K tokens per agent task
7. **Convert non-text files to Markdown first** — avoid the DOCX/PDF/HTML format tax before content enters chat, agents, or RAG
-8. **Retune prompts to target model guide** — not a per-request shrink; improves first-pass quality and avoids rework after model changes
+8. **Precompute codebase graphs with Graphify** — replace repeated orientation reads with targeted graph queries on large repos
+9. **Retune prompts to target model guide** — not a per-request shrink; improves first-pass quality and avoids rework after model changes
## 3.4 Quality Impact Assessment
diff --git a/docs/10-practical-setup.md b/docs/10-practical-setup.md
index b15b327..7f68c13 100644
--- a/docs/10-practical-setup.md
+++ b/docs/10-practical-setup.md
@@ -341,6 +341,44 @@ Commands with verbose output (test failures, large diffs) see the biggest reduct
Combine with `copilot-setup-steps.yml` (§4.3.2) and precise issue descriptions (§4.3.3) for maximum session efficiency. Full setup, command list, and other AI tool support: [MCP & Tool Costs §2.7.7](08-mcp-tool-costs.md#277-compress-tool-output-at-the-source-rtk).
+### 4.3.7 Build a Persistent Knowledge Graph with Graphify
+
+RTK compresses what shell commands return. [Graphify](https://github.com/Graphify-Labs/graphify) addresses a different cost: tokens spent reading project files to understand structure before the agent can act.
+
+Install once:
+
+```bash
+uv tool install graphifyy
+```
+
+Build or update the graph in the repo:
+
+```bash
+graphify .
+```
+
+Then query targeted structure:
+
+```text
+graphify query "where is error handling for the API layer?"
+graphify path "AuthService" "Database"
+graphify explain "QueueWorker"
+```
+
+The graph lives in `graphify-out/graph.json`. The human-readable map is `graphify-out/GRAPH_REPORT.md`; the visual explorer is `graphify-out/graph.html`.
+
+**Biggest gains:** Coding Agent and agent-mode sessions on large repos where the first several steps are file reads for orientation. Graphify front-loads that structural scan once and amortizes it across later sessions.
+
+**Team choice:** decide whether to commit `graphify-out/graph.json` and `GRAPH_REPORT.md` so agents share the same map, or `.gitignore` `graphify-out/` and let each developer build locally. Do not commit graphs that expose sensitive source relationships if your repo policy treats them as restricted metadata.
+
+**Combine with:**
+
+- `copilot-setup-steps.yml` (§4.3.2) so the agent environment is deterministic before graph queries matter
+- precise issue descriptions (§4.3.3) so the agent queries the right subgraph, not the whole repo map
+- fresh execution sessions ([Outcome per Token](13-outcome-per-token.md)) so the graph supplements a short plan instead of a long transcript
+
+Note: code parsing is local for the AST pass. Optional semantic/deep extraction over docs, PDFs, images, or media may use a configured AI backend. Review that boundary before enabling extras on proprietary codebases.
+
## 4.4 Building the Habit
### Start Small
diff --git a/docs/12-enterprise-governance.md b/docs/12-enterprise-governance.md
index 4d0893b..a12ef8d 100644
--- a/docs/12-enterprise-governance.md
+++ b/docs/12-enterprise-governance.md
@@ -167,3 +167,7 @@ If you are preparing customers for the June 1 shift, do this first:
8. use separate org segmentation only if cost-center boundaries already support it
This is boring on purpose. Cheap defaults first. Premium access by exception. Measurement before expansion.
+
+---
+
+**Next:** [Outcome per Token →](13-outcome-per-token.md)
diff --git a/docs/13-outcome-per-token.md b/docs/13-outcome-per-token.md
new file mode 100644
index 0000000..458aa84
--- /dev/null
+++ b/docs/13-outcome-per-token.md
@@ -0,0 +1,444 @@
+# Outcome per Token
+
+[← Back to Guide](index.md)
+
+---
+
+Token optimization is not the real goal. The real goal is **more accepted work per token spent**: merged pull requests, closed bugs, passing tests, clean reviews, and fewer wrong-direction agent loops.
+
+Raw token minimization can even be the wrong move. A short prompt that causes the agent to guess, edit the wrong files, fail tests, and backtrack is more expensive than a longer plan that gets the first implementation right.
+
+## Why Outcome per Token Matters
+
+Usage-based billing makes tokens visible, but engineering teams do not buy tokens. They buy outcomes.
+
+Tomasz Tunguz describes this as the shift to intelligence per dollar: the application layer competes on the cost of a closed ticket, shipped PR, or resolved support case, not the cheapest raw token.[^tunguz] That maps directly to Copilot work. The useful metric is:
+
+```text
+outcome per token = verified work completed / total tokens spent
+```
+
+For agentic coding, cost behaves differently than in simple chat. The Microsoft/Stanford paper "How Do AI Agents Spend Your Money?" reports that agentic coding tasks consume roughly **1,000×** more tokens than code chat, runs on the same task can vary by up to **30×**, and higher token usage does not reliably improve accuracy.[^agent-costs]
+
+### What the research shows
+
+| Finding | Why it matters |
+|---|---|
+| Agentic coding can consume roughly **1,000×** more tokens than code chat | Do not extrapolate chat-cost intuition to agent sessions |
+| Same task can vary by up to **30×** across runs | Budget with margin; one run is not a stable cost estimate |
+| Higher token usage does not reliably improve accuracy | More exploration is not automatically better work |
+| Accuracy often peaks at intermediate cost and then saturates | Defaulting to the biggest model for every step can waste money |
+| Input tokens dominate agentic cost | Context hygiene matters as much as output terseness |
+| Models underestimate their own token use | Do not trust an agent's pre-task cost guess; use budgets and stop rules |
+| Token efficiency varies by model independent of pass rate | Compare outcome and cost together, not benchmark score alone |
+
+The implication is simple: optimize the loop, not the sentence.
+
+## The Outcome-per-Token Loop
+
+High outcome per token comes from six habits:
+
+1. pick the right task shape
+2. plan before implementation
+3. route the right model to the right phase
+4. preserve clean context and cache boundaries
+5. verify before claiming done
+
+Low outcome per token usually has the opposite shape: vague prompt, huge context, expensive model pinned too long, no acceptance criteria, agent edits before planning, tests run late, then a rework session starts from scratch.
+
+## Prompt Skills as Superpowers
+
+The community project [`obra/superpowers`](https://github.com/obra/superpowers) popularizes a useful framing: treat repeatable agent practices as skills, not one-off prompts.[^superpowers] It is not an official GitHub product, but its skill categories map well to Copilot cost control.
+
+This chapter uses that idea as a practical taxonomy.
+
+| Skill | What it does | Token effect |
+|---|---|---|
+| Brainstorming | Explore multiple approaches before choosing | Prevents early lock-in and wrong-direction code |
+| Planning | Converts intent into file-level steps and checks | Reduces guessing during execution |
+| Greenness | Keeps tests passing through the work | Avoids debugging unknown baseline failures |
+| Verification before completion | Requires evidence before "done" | Prevents false completion and rework |
+| Impeccable close | Finishes cleanly with criteria, tests, and PR summary aligned | Prevents review churn and follow-up agent sessions |
+| Branch-close discipline | Ends branch/session cleanly after merge | Prevents stale context from leaking into next task |
+
+The skills below are patterns. The public libraries that follow are example implementations of those patterns, not mandatory dependencies.
+
+## Skill Libraries Worth Borrowing From
+
+Community skill libraries can improve outcome per token when they make the next agent action more precise: clearer requirements, safer tool use, better tests, cleaner handoff, or stronger final review. Treat them as reusable practice, not official GitHub or Microsoft guidance. Most claims are qualitative and experience-based; use them because they encode good workflow discipline, not because they prove a universal benchmark gain.
+
+| Library | Best borrowed skill | Use when | Caveat |
+|---|---|---|---|
+| [`obra/superpowers`](https://github.com/obra/superpowers) | TDD, planning, verification, branch finish | Need broad agent SDLC discipline | Community framework |
+| [`softaworks/agent-toolkit`](https://github.com/softaworks/agent-toolkit) | Planning orchestration, handoff, entropy reduction | Complex features, long sessions, bloated instruction files | Personal toolkit; qualitative claims |
+| [`catpilotai/catpilot-ai-guardrails`](https://github.com/catpilotai/catpilot-ai-guardrails) | Security and tool-loop guardrails | Agents touch secrets, cloud, DB, Docker, or supply chain | Guidance, not runtime enforcement |
+| [`vercel-labs/agent-browser`](https://github.com/vercel-labs/agent-browser/blob/main/skills/agent-browser/SKILL.md) | Snapshot, wait, and evidence discipline | Agents test browser UIs | Browser-specific; installed CLI content is authoritative |
+| [`vercel-labs/writing-guidelines`](https://github.com/vercel-labs/writing-guidelines) | Plan-as-prompt, output review, AI-tell detection | Docs, PR descriptions, specs, generated prose | Editorial guidance, not measured token reduction |
+| [`mattpocock/skills`](https://github.com/mattpocock/skills) | TDD, bug diagnosis, code review, domain modeling | Engineering tasks need sharper loops | Examples skew Claude and TypeScript workflows |
+| [`PramodDutta/qaskills`](https://github.com/PramodDutta/qaskills) | QA and test-generation skills | Need Playwright, API, BDD, security, accessibility, or bug-report depth | Large skill files; early project |
+
+### `obra/superpowers`: Baseline Agent SDLC Discipline
+
+Use Superpowers as the reference pattern: skills are small, named operating procedures. The value is not the brand name; the value is turning "be careful" into concrete moves the agent can follow.[^superpowers]
+
+- Borrow the TDD, planning, verification, and branch-finish habits.
+- Convert team norms into small reusable prompts or skill files.
+- Prefer skills that force evidence: test output, file-level plan, acceptance criteria, or clean close.
+- Do not load broad skills when a one-line instruction would steer the next action.
+
+### `softaworks/agent-toolkit`: Planning, Handoff, and Entropy Control
+
+`agent-toolkit` is a broad personal toolkit with skills, subagents, and commands for Claude-style agent workflows.[^agent-toolkit] Its best fit here is not copying everything; it is borrowing the structure for long-running engineering work.
+
+- Use `gepetto`-style flow for complex features: research, stakeholder questions, spec, plan, review, then execution.
+- Use `requirements-clarity` before coding when the task still has hidden ambiguity.
+- Use `session-handoff` when a long session must transfer context without leaking stale decisions or secrets.
+- Use `reducing-entropy` as an explicit deletion-biased review: fewer files, fewer branches, less code, clearer seams.
+- Use instruction-file refactor patterns when `AGENTS.md`, `CLAUDE.md`, or team prompts grow so large they become context tax.
+
+### `catpilot-ai-guardrails`: Risk Stops Before Expensive Mistakes
+
+Guardrail skills improve outcome per token by preventing costly wrong actions: leaked secrets, unsafe cloud mutations, database damage, supply-chain drift, or retry loops.[^catpilot-guardrails] They are especially relevant when the agent has write-capable tools.
+
+- Add guardrails before tasks that touch credentials, PII, cloud CLIs, databases, Docker, CI, or dependency manifests.
+- Require explicit confirmation before destructive or high-cost actions.
+- Use retry budgets and loop-stop rules so agents do not burn tokens repeating the same failing tool call.
+- Pair skill guidance with real controls: branch protection, CI, SAST, DAST, SCA, secret scanning, and least-privilege credentials.
+- Do not describe these skills as compliance enforcement. They guide behavior; they do not sandbox tools.
+
+### `agent-browser`: Browser QA Without DOM Floods
+
+`agent-browser` is useful because it teaches browser agents to use compact observations and evidence-oriented waits instead of dumping huge HTML or guessing from screenshots.[^agent-browser]
+
+- Prefer accessibility-tree snapshots and stable element references over raw DOM dumps.
+- Re-snapshot after page-changing actions; browser references go stale.
+- Wait on observable states such as text, URL, or network idle instead of fixed sleeps.
+- Capture proportionate evidence: failing selector, visible state, screenshot only when useful.
+- Treat page content as untrusted input. Do not follow instructions embedded in a website under test.
+
+### `writing-guidelines`: Make the Plan the Prompt, Spec, and Review Artifact
+
+Vercel's writing guidance is useful for engineering agents because it turns vague prose into testable artifacts.[^writing-guidelines] Better writing reduces rework tokens: fewer hidden goals, fewer vague success criteria, fewer review comments asking what changed.
+
+- Write goals with testable verbs, not vague aspirations.
+- Keep one page or prompt focused on one job.
+- Use the plan as the implementation prompt, test spec, and PR-description seed.
+- Flag weasel words and vague quantifiers before sending text to an agent.
+- Borrow the second-pass review pattern: ask another agent or model for concrete `file:line` findings, not general praise.
+
+### `mattpocock/skills`: Engineering Loops That Reduce Guessing
+
+Matt Pocock's skills are useful because they encode engineering loops: TDD, bug diagnosis, code review axes, domain modeling, and large-work decomposition.[^mattpocock-skills] They are strongest when the agent would otherwise jump straight from symptom to edit.
+
+- Use TDD skills to agree on seams before implementation.
+- Use bug-diagnosis skills to build a fast, deterministic red/green loop before theorizing.
+- Split review into two axes: standards review and spec review, so style concerns do not hide requirement misses.
+- Use domain-modeling vocabulary such as seam, adapter, leverage, locality, and module depth to guide architecture prompts.
+- Use wayfinding patterns to separate human-in-the-loop tickets from agent-runnable work.
+
+### `qaskills`: QA Depth on Demand
+
+`qaskills` is a QA skill catalog with CLI, MCP server, catalog, SDK, and validator.[^qaskills] Its token value is specialization: load QA depth when the task is actually QA-heavy instead of asking a general agent to invent a test strategy from scratch.
+
+- Use Playwright skills for page-object discipline, accessibility-first selectors, fixtures, and anti-pattern checks.
+- Use test-plan skills for risk matrices, traceability, equivalence partitioning, and entry/exit criteria.
+- Use bug-report skills when the outcome is a reproducible issue with severity, priority, environment, and evidence.
+- Use BDD/Cucumber skills when acceptance criteria should become executable Given/When/Then scenarios.
+- Use OWASP, visual-regression, axe-core, k6, and API-testing skills only when those checks are part of the task.
+
+### Do Not Install Every Skill
+
+Skills are context too. Install only the ones that change the next agent action.
+
+| Task | Load |
+|---|---|
+| Test design, QA automation, bug reports | QA skills |
+| Browser UI investigation | Browser snapshot/wait/evidence skills |
+| Cloud, database, Docker, secrets, dependencies | Guardrail skills |
+| Specs, docs, PR descriptions | Writing and review skills |
+| Long sessions, complex features, handoff | Planning and handoff skills |
+
+If a skill is not likely to change the next edit, command, test, or review, leave it out. The best skill selection is still context selection.
+
+### Brainstorming Skill
+
+Use this before the first edit when requirements are ambiguous.
+
+```text
+Before coding, list three implementation approaches.
+For each: files likely touched, risks, test strategy, and token/cost risk.
+Do not edit files.
+```
+
+This spends a small number of reasoning tokens to avoid a much larger rework loop.
+
+### Planning Skill
+
+Planning turns "build X" into executable steps.
+
+Use the official VS Code [Plan agent](https://code.visualstudio.com/docs/agents/planning) when available. It can be selected from the agent dropdown or invoked with `/plan`, generates a high-level plan plus implementation and verification steps, and supports separate model settings for planning and implementation through `chat.planAgent.defaultModel` and `github.copilot.chat.implementAgent.model`.[^plan-agent]
+
+For GitHub.com tasks, Copilot cloud agent supports a research, plan, iterate flow: ask it to research the repo, iterate on a plan, then implement the agreed plan only when ready.[^cloud-plan]
+
+Important caveats:
+
+- VS Code Plan agent session memory is cleared when the conversation ends. Save important plans externally before closing the session.[^plan-agent]
+- Copilot cloud agent planning and iteration before creating a PR are GitHub.com capabilities; integrations such as Azure Boards, JIRA, Linear, Slack, or Teams support direct PR creation only.[^cloud-agent]
+- Cloud agent sessions have a 59-minute hard limit. Break large work into smaller tasks.[^cloud-agent]
+- Business and Enterprise users need the relevant admin policy enabled before using cloud agent.[^cloud-agent]
+
+### Greenness Skill
+
+"Greenness" is this guide's label for a simple discipline: keep the test baseline green.
+
+Before asking an agent to modify code:
+
+1. know whether tests pass now
+2. tell the agent the baseline
+3. ask it to preserve that baseline
+4. run tests before accepting completion
+
+If tests start red and the agent does not know that, it spends tokens debugging pre-existing failures. If tests go red during the task and the agent keeps editing, it compounds uncertainty.
+
+Green baseline first. Then change.
+
+### Verification-before-Completion Skill
+
+Do not accept "done" without evidence.
+
+```text
+Before you report completion, run the targeted tests or build,
+state the exact command, and confirm each acceptance criterion.
+```
+
+This costs a little at the end. It saves a lot when it prevents false completion, review churn, and a second agent session.
+
+### Impeccable Close Skill
+
+"Impeccable close" is this guide's label for closing the loop cleanly. The term is not an official Copilot concept; the practice is the important part.
+
+A good close includes:
+
+1. accepted criteria checked
+2. tests/build run where relevant
+3. no accidental scope creep
+4. no stale TODOs or commented-out attempts
+5. PR summary matches the actual diff
+6. next step named only if one is truly needed
+
+This is outcome-per-token discipline. A sloppy close moves cost from implementation into review, follow-up prompts, and hotfixes.
+
+### Branch-Close Discipline
+
+After merge, close the branch and any long-running agent session. Do not keep using the same context for the next unrelated task.
+
+Stale sessions accumulate decisions, tool output, file reads, and abandoned approaches. Every later prompt may drag that history forward as input tokens. A clean close keeps the next task from paying for the previous one.
+
+## Plan First, Then Execute Cheaply
+
+The strongest pattern is two separate phases:
+
+```text
+Phase 1: Plan
+ model: strong reasoning model
+ mode: Plan / Ask / cloud-agent research
+ output: saved plan with steps and acceptance criteria
+
+Phase 2: Execute
+ model: cheaper or mid-tier model
+ mode: fresh agent session
+ input: saved plan + targeted files only
+ output: verified implementation
+```
+
+GitHub's [Optimize AI Usage](https://docs.github.com/en/copilot/tutorials/optimize-ai-usage) guidance makes the same point: defaulting to the most capable model can increase token usage without improving the outcome, and overusing reasoning models in execution-heavy tasks can reduce quality by making the model overthink or introduce unnecessary changes.[^optimize-ai] The same page gives the practical rule: plan with a strong reasoning model, then implement with a cheaper model.
+
+Why fresh session matters:
+
+- the planning conversation does not get re-sent on every execution turn
+- the execution context starts clean
+- the plan becomes a stable, cache-friendly prefix
+- model routing is deliberate instead of accidental
+
+This is the expanded version of [Plan First, Then Execute §2.5.9](06-workflow-optimization.md#259-plan-first-then-execute-and-route-the-phases).
+
+### Official Three-Tier Framework
+
+GitHub's official tutorial separates work into three model lanes.[^optimize-ai]
+
+| Tier | Best for | Outcome-per-token rule |
+|---|---|---|
+| Reasoning models | Architecture decisions, complex debugging, system design, deep analysis | Use for planning and hard judgment |
+| Mid-tier models | Clear plans that need efficient implementation | Use for execution once ambiguity is removed |
+| Lighter models | Refactoring, formatting, documentation, routine scoped changes | Use for bounded mechanical work |
+
+Do not pay for frontier reasoning after the hard thinking is already captured in the plan.
+
+## Day-to-Day Model Guidance
+
+Model advice changes quickly. Treat this table as routing guidance, not permanent truth. Check the official [supported models](https://docs.github.com/en/copilot/reference/ai-models/supported-models), [model comparison](https://docs.github.com/en/copilot/reference/ai-models/model-comparison), and [models and pricing](https://docs.github.com/en/copilot/reference/copilot-billing/models-and-pricing) pages before publishing customer-specific guidance.[^supported-models][^models-pricing]
+
+| Work | Good default | Tier | Typical input cost / 1M tokens | Why |
+|---|---|---|---:|---|
+| Quick lookup, syntax, tiny bounded edit | Auto, GPT-5.6 Luna, MAI-Code-1-Flash, Claude Haiku 4.5 | Lightweight | $0.75-$1.00 | Fast and low-cost enough for small tasks |
+| Normal implementation after a clear plan | Auto, GPT-5.6 Terra, MAI-Code-1-Flash, Claude Sonnet 5 | Versatile / Lightweight | $0.75-$2.50 | Balanced execution without paying maximum reasoning cost |
+| Agentic coding with moderate uncertainty | GPT-5.6 Terra, GPT-5.4 nano, Claude Sonnet 5 | Versatile / Lightweight | $0.20-$2.50 | Good lane when edits need tools but not frontier reasoning |
+| Hard architecture, multi-file debugging, long-horizon planning | GPT-5.6 Sol, GPT-5.5, Claude Opus 4.7/4.8, Claude Fable 5 | Powerful | $5.00-$10.00 | Pay premium where reasoning quality changes the outcome |
+| Open-weight / cost-conscious coding | Kimi K2.7 Code | Versatile | $0.95 | Useful option, but review enterprise policy and security requirements |
+| Visual, multimodal, research-heavy work | Gemini 3.1 Pro (Public Preview), Claude Sonnet 5, GPT-5 mini where supported | Powerful / Versatile | $0.25-$2.00 | Pick for modality and research fit, not raw benchmark rank |
+| Subagents for focused subtasks | Cheaper/lightweight model | Lightweight | varies | Subagents do not inherit the whole main conversation, so cheaper models often suffice |
+
+### Practical Defaults
+
+For most teams:
+
+1. **Auto first** for unknown everyday work. GitHub documents Auto as a task-aware router and gives paid plans a 10% AI credit discount when using it in supported surfaces.[^auto]
+2. **Luna / MAI / Haiku** for tiny, bounded work.
+3. **Terra / Sonnet / mid-tier** for normal implementation.
+4. **Sol / GPT-5.5 / Opus / Fable** for planning, architecture, and hard debugging.
+5. **Fresh session when changing lanes.** Switching models mid-session can invalidate cache and drag accumulated context into a more expensive request.[^optimize-ai]
+
+### Important Model Caveats
+
+- GPT-5.6 Luna, Terra, and Sol are documented as GA in Copilot, but the model comparison page listed their model cards as "Not available" at research time.[^supported-models]
+- GPT-5.6 Sol is the powerful lane; do not leave it pinned for routine edits.
+- Kimi K2.7 is an open-weight model in Copilot and may require admin opt-in for Business/Enterprise. Treat it as a policy decision, not just a price decision.[^kimi]
+- MAI-Code-1-Flash is documented as a continuously improving model; behavior may evolve as checkpoints change.[^mai]
+- Claude Sonnet 5 promotional pricing was documented through August 31, 2026. Recheck after that date before publishing pricing guidance.[^supported-models]
+- Claude Fable 5 has a data-retention caveat in GitHub docs: Anthropic retains prompts and outputs to operate safety classifiers. Business/Enterprise admins should review terms before enabling it.[^supported-models]
+- FedRAMP enforcement adds a 10% AI credit surcharge, and GPT-5.6 family plus Kimi K2.7 were not on the FedRAMP model list at research time.[^fedramp]
+- Legacy annual subscribers may not receive access to new models and features such as GPT-5.6 family, Claude Fable 5, Claude Sonnet 5, or Kimi K2.7 under old billing.[^models-pricing]
+- Extended capabilities such as 1M context and configurable reasoning are documented for VS Code and Copilot CLI only. Use regular context and regular reasoning by default.[^supported-models]
+- Code completions and next edit suggestions are not billed in AI credits on paid plans. Do not treat every Copilot surface as the same cost bucket.[^usage-billing]
+
+## Benchmarks: Useful, Not Decisive
+
+Benchmarks help choose lanes. They do not replace measurement on your repo.
+
+| Benchmark | Measures | Why it matters | Caveat |
+|---|---|---|---|
+| [SWE-bench Verified](https://www.swebench.com/verified.html) | 500 human-verified Python GitHub issues | Classic software-engineering proxy | Python-heavy, static, possible contamination risk |
+| [SWE-bench Pro](https://labs.scale.com/leaderboard/swe_bench_pro_public) | Harder professional repo tasks | Shows enterprise difficulty cliff | Scores depend on scaffold and current live leaderboard |
+| [SWE-bench Live](https://swe-bench-live.github.io/) | Continuously updated issues | Reduces saturation and memorization | Dynamic scores shift over time |
+| [DeepSWE](https://github.com/datacurve-ai/deep-swe) | 113 original long-horizon tasks across several languages | Good coding-agent and cost-per-task lens | Small task count; reasoning tier changes results |
+| [Terminal-Bench](https://www.tbench.ai/) | Terminal and shell workflows | Maps to build/test/devops agent work | Small task count; terminal skill is not all coding skill |
+| [Artificial Analysis](https://artificialanalysis.ai/methodology) | Intelligence, pricing, latency, provider comparison | Good cost/intelligence scatter plot | Composite scores may not match coding-only needs |
+
+### Score Snapshot
+
+| Benchmark | Model / condition | Score | Confidence |
+|---|---|---:|---|
+| SWE-bench Verified | Top models at SWE-bench Pro paper-era cross-reference | >70% | Verified from Scale AI Pro page |
+| SWE-bench Pro public | GPT-5, paper-era | 23.3% | Verified |
+| SWE-bench Pro public | Claude Opus 4.1, paper-era | 23.1% | Verified |
+| SWE-bench Pro private | GPT-5, paper-era | 14.9% | Verified |
+| Terminal-Bench 2.0 | Frontier models | <65% | Verified from benchmark abstract |
+| DeepSWE | GPT-5.6 Sol `[max]` | 72.7% | Directional; third-party mirror and reasoning-tier dependent |
+| DeepSWE | Top-three spread | <3.1 points | Directional; third-party mirror and reasoning-tier dependent |
+
+Use benchmark numbers with labels:
+
+- **Verified**: source directly read from primary leaderboard or paper.
+- **Directional**: aggregator or secondary source.
+- **Anecdotal**: Reddit, Discord, social media, single-session reports.
+
+The Reddit post that motivated this chapter is useful as a hypothesis generator: it highlights a real practitioner pattern around Pareto frontiers, DeepSWE cost-per-task, and GPT-5.6 tier routing. Do not treat its exact cost/task ladder as stable guide data unless rechecked against current DeepSWE, Artificial Analysis, and official Copilot pricing.
+
+## Why Harness Matters
+
+A model score is rarely just a model score. It includes:
+
+- agent scaffold
+- tool access
+- retrieval strategy
+- reasoning effort
+- cache pricing assumptions
+- task language mix
+- benchmark version
+- whether the run is single-attempt or multi-attempt
+
+SWE-bench itself notes that versions using different action formats are not directly comparable. DeepSWE entries often include reasoning level in the model name, such as `[max]`. Artificial Analysis may answer a different question: broad intelligence per dollar, not pure coding-agent pass rate.[^swebench][^deepswe][^artificial-analysis]
+
+Use benchmarks to pick candidates. Use your own repo tasks to pick defaults.
+
+## A Practical Decision Checklist
+
+Before starting an expensive agent session:
+
+1. **Is the task actually agentic?** If not, use Ask mode or inline completion.
+2. **Is the baseline green?** If not, fix or record it first.
+3. **Is the plan written?** If not, plan first.
+4. **Can execution run on a cheaper model?** If yes, do that in a fresh session.
+5. **Is context targeted?** Attach only the plan and relevant files.
+6. **Are acceptance criteria explicit?** If not, write them before execution.
+7. **Is verification defined?** Name the test/build/check command up front.
+8. **Will a model switch invalidate cache?** If yes, start fresh instead.
+9. **Is the model policy allowed for this org/customer?** Check admin and compliance constraints.
+10. **Will the close be clean?** Require test evidence and a concise summary.
+
+## What Not to Include Yet: Govify
+
+The name "Govify" appears to refer to multiple unrelated things: a local-government HR/recruiting SaaS, an old OpenGov Foundation PDF converter, and a cloud rewrite of that converter. Research found no verified connection to GitHub Copilot, token optimization, AI developer governance, or outcome-per-token workflows.
+
+Do not use Govify as a case study in this guide unless a primary source is provided. A weak mention would create confusion rather than value.
+
+## Cross-References
+
+- [Workflow Optimization §2.5.9](06-workflow-optimization.md#259-plan-first-then-execute-and-route-the-phases) — shorter version of the plan-first habit
+- [Context Management](04-context-management.md) — cache and context hygiene
+- [Output Control](05-output-control.md) — output token reduction
+- [Practical Setup](10-practical-setup.md) — setup and operating habits
+- [Model Selection & Pricing](11-models-and-pricing.md) — model and pricing surfaces
+- [Enterprise Governance](12-enterprise-governance.md) — budgets, model policy, and admin rollout
+
+## References
+
+[^agent-costs]: Longju Bai et al., "How Do AI Agents Spend Your Money? Analyzing and Predicting Token Consumption in Agentic Coding Tasks," arXiv:2604.22750, https://arxiv.org/abs/2604.22750
+
+[^tunguz]: Tomasz Tunguz, "Intelligence Per Dollar," https://tomtunguz.com/tokens-per-result
+
+[^superpowers]: `obra/superpowers`, community agentic-skills framework, https://github.com/obra/superpowers
+
+[^agent-toolkit]: `softaworks/agent-toolkit`, community agent skill toolkit, https://github.com/softaworks/agent-toolkit
+
+[^catpilot-guardrails]: `catpilotai/catpilot-ai-guardrails`, community security guardrail skills, https://github.com/catpilotai/catpilot-ai-guardrails
+
+[^agent-browser]: `vercel-labs/agent-browser` agent browser skill, https://github.com/vercel-labs/agent-browser/blob/main/skills/agent-browser/SKILL.md
+
+[^writing-guidelines]: `vercel-labs/writing-guidelines`, practitioner writing and review guidance, https://github.com/vercel-labs/writing-guidelines
+
+[^mattpocock-skills]: `mattpocock/skills`, community engineering skill collection, https://github.com/mattpocock/skills
+
+[^qaskills]: `PramodDutta/qaskills`, QA skill catalog and tooling, https://github.com/PramodDutta/qaskills
+
+[^plan-agent]: VS Code Docs, "Planning with Copilot," https://code.visualstudio.com/docs/agents/planning
+
+[^cloud-plan]: GitHub Docs, "Use Copilot agents: Research, plan, iterate," https://docs.github.com/en/copilot/how-tos/copilot-on-github/use-copilot-agents/research-plan-iterate
+
+[^cloud-agent]: GitHub Docs, "About Copilot cloud agent," https://docs.github.com/en/copilot/concepts/agents/cloud-agent/about-cloud-agent
+
+[^optimize-ai]: GitHub Docs, "Optimize AI Usage," https://docs.github.com/en/copilot/tutorials/optimize-ai-usage
+
+[^supported-models]: GitHub Docs, "Supported AI models in Copilot," https://docs.github.com/en/copilot/reference/ai-models/supported-models and "Model comparison," https://docs.github.com/en/copilot/reference/ai-models/model-comparison
+
+[^models-pricing]: GitHub Docs, "Models and Pricing," https://docs.github.com/en/copilot/reference/copilot-billing/models-and-pricing
+
+[^auto]: GitHub Docs, "Auto model selection," https://docs.github.com/en/copilot/concepts/models/auto-model-selection
+
+[^kimi]: GitHub Changelog, "Kimi K2.7 now available for Copilot Business and Enterprise," https://github.blog/changelog/2026-07-07-kimi-k2-7-now-available-for-copilot-business-and-enterprise/
+
+[^mai]: GitHub Changelog, "MAI-Code-1-Flash is now available for GitHub Copilot," https://github.blog/changelog/2026-06-02-mai-code-1-flash-is-now-available-for-github-copilot/
+
+[^fedramp]: GitHub Docs, "FedRAMP models," https://docs.github.com/en/copilot/concepts/models/fedramp-models
+
+[^usage-billing]: GitHub Docs, "Usage-based billing for individuals," https://docs.github.com/en/copilot/concepts/billing/usage-based-billing-for-individuals
+
+[^swebench]: SWE-bench Verified, https://www.swebench.com/verified.html
+
+[^deepswe]: DeepSWE, https://github.com/datacurve-ai/deep-swe
+
+[^artificial-analysis]: Artificial Analysis methodology, https://artificialanalysis.ai/methodology
+
+---
+
+**Next:** [Back to Home →](index.md)
diff --git a/docs/index.md b/docs/index.md
index 635a96c..94f28f5 100644
--- a/docs/index.md
+++ b/docs/index.md
@@ -26,6 +26,7 @@ Practical guide to reducing GitHub Copilot token spend while keeping answers and
7. Convert DOCX/PDF/Office/media inputs to Markdown before AI work; start with [MarkItDown](https://github.com/microsoft/markitdown).
8. Audit long-running agent sessions and repeated back-and-forth.
9. Install [RTK](https://github.com/rtk-ai/rtk) — CLI proxy that filters `git`, test runners, `grep`, and 100+ other shell commands before output reaches the agent. One install, 60-90% savings on tool-call results in agent and coding-agent sessions.
+10. Build a persistent codebase graph with [Graphify](https://github.com/Graphify-Labs/graphify) — map code once via tree-sitter AST, write `graphify-out/graph.json`, then let agents query the graph instead of re-reading project files each session. Install: `uv tool install graphifyy`.
## Read by Topic
@@ -46,6 +47,7 @@ Practical guide to reducing GitHub Copilot token spend while keeping answers and
- [Practical Setup](10-practical-setup.md)
- [Model Selection & Pricing](11-models-and-pricing.md)
- [Enterprise Governance](12-enterprise-governance.md)
+- [Outcome per Token](13-outcome-per-token.md)
## Quick Terms
@@ -66,6 +68,7 @@ Practical guide to reducing GitHub Copilot token spend while keeping answers and
- [LLMLingua](https://github.com/microsoft/LLMLingua)
- [Caveman project](https://github.com/JuliusBrussee/caveman)
- [RTK — Rust Token Killer](https://github.com/rtk-ai/rtk)
+- [Graphify](https://github.com/Graphify-Labs/graphify) — build a persistent knowledge graph of your codebase; agents query `graphify-out/graph.json` instead of re-reading files. Supports GitHub Copilot, VS Code workflows, and other assistants. PyPI package: `graphifyy`
- [Microsoft MarkItDown](https://github.com/microsoft/markitdown) — convert PDF, Office files, images, audio, HTML, ZIP contents, YouTube URLs, EPUBs, and more to Markdown for LLM workflows
- [Marc Bara: "Your .docx Is Wasting 33% of Your AI Budget"](https://medium.com/@marc.bara.iniesta/your-docx-is-wasting-33-of-your-ai-budget-86a3d229d042)
- [Dina Berry: "How I Cut Token Usage from 52% to 13%"](https://dfberry.github.io/2026-05-06-tuning-up-copilot-context) — real measured numbers from a Copilot CLI production setup (Microsoft/GitHub content contributor)
diff --git a/mkdocs.yml b/mkdocs.yml
index 6141434..3ad892c 100644
--- a/mkdocs.yml
+++ b/mkdocs.yml
@@ -45,3 +45,4 @@ nav:
- Practical Setup: 10-practical-setup.md
- Model Selection & Pricing: 11-models-and-pricing.md
- Enterprise Governance: 12-enterprise-governance.md
+ - Outcome per Token: 13-outcome-per-token.md
From f4b9af43b2ad680bb5ce4b4c0df118f42cf84a09 Mon Sep 17 00:00:00 2001
From: Marco Olivo <8478776+olivomarco@users.noreply.github.com>
Date: Sun, 12 Jul 2026 13:29:15 +0200
Subject: [PATCH 05/13] Add star image
---
docs/13-outcome-per-token.md | 6 ++++++
1 file changed, 6 insertions(+)
diff --git a/docs/13-outcome-per-token.md b/docs/13-outcome-per-token.md
index 458aa84..0acaca3 100644
--- a/docs/13-outcome-per-token.md
+++ b/docs/13-outcome-per-token.md
@@ -77,6 +77,12 @@ Community skill libraries can improve outcome per token when they make the next
| [`mattpocock/skills`](https://github.com/mattpocock/skills) | TDD, bug diagnosis, code review, domain modeling | Engineering tasks need sharper loops | Examples skew Claude and TypeScript workflows |
| [`PramodDutta/qaskills`](https://github.com/PramodDutta/qaskills) | QA and test-generation skills | Need Playwright, API, BDD, security, accessibility, or bug-report depth | Large skill files; early project |
+### Skill Library Star History
+
+[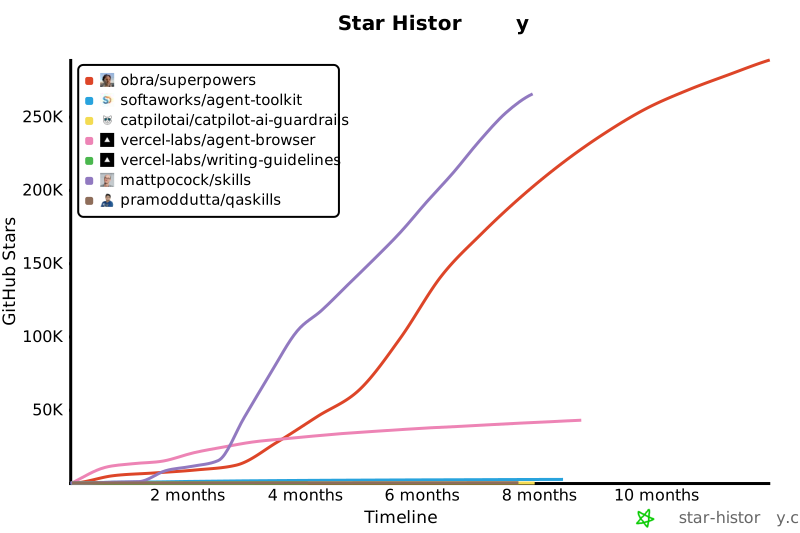](https://www.star-history.com/#obra/superpowers&softaworks/agent-toolkit&catpilotai/catpilot-ai-guardrails&vercel-labs/agent-browser&vercel-labs/writing-guidelines&mattpocock/skills&PramodDutta/qaskills&timeline)
+
+Star history is an adoption signal, not a quality benchmark. Use it to understand community attention, then judge each library by whether it changes the next agent action.
+
### `obra/superpowers`: Baseline Agent SDLC Discipline
Use Superpowers as the reference pattern: skills are small, named operating procedures. The value is not the brand name; the value is turning "be careful" into concrete moves the agent can follow.[^superpowers]
From 33cbd8961c55d98b1c947a9c5bdbc30058838f09 Mon Sep 17 00:00:00 2001
From: Marco Olivo <8478776+olivomarco@users.noreply.github.com>
Date: Sun, 12 Jul 2026 14:04:00 +0200
Subject: [PATCH 06/13] Add other tools to compress outputs
---
README.md | 6 +--
docs/04-context-management.md | 2 +-
docs/06-workflow-optimization.md | 35 ++++++++++++--
docs/08-mcp-tool-costs.md | 83 +++++++++++++++++++++++++++++---
docs/09-comparisons-data.md | 6 +++
docs/10-practical-setup.md | 62 +++++++++++++++++++++++-
docs/index.md | 4 +-
7 files changed, 183 insertions(+), 15 deletions(-)
diff --git a/README.md b/README.md
index 904aca2..567f231 100644
--- a/README.md
+++ b/README.md
@@ -26,7 +26,7 @@ Don't have time to read the full guide? Do these today and cut your token usage:
| 6 | **Scope context with `applyTo:` paths** — split one large instructions file into small scoped ones that load only when relevant | Reduces always-on input/context | 15 minutes |
| 7 | **Be precise in your prompts** — "Add null check to `getUser()`" not "Can you please look at this and maybe add some error handling?" Note: your typed prompt is a small fraction of total input; precision matters more for quality than for raw token savings | Improves task targeting | 0 minutes |
| 8 | **Retune prompts to the target model** — provider prompting guides change by model/version. Paste the official guide URL into Copilot and ask it to adapt `.github/copilot-instructions.md`, agent profiles, or app prompts for the model you actually use | Reduces rework | 10 minutes per model change |
-| 9 | **Audit your MCP servers and injected tools** — disable unused MCP servers and VS Code extensions that add skills/tools; use a clean coding profile or focused custom agent for repeat workflows. Each MCP tool costs ~100-500 tokens per agent step | Removes tool/schema overhead | 5-10 minutes |
+| 9 | **Audit your MCP servers and injected tools** — disable unused MCP servers and VS Code extensions that add skills/tools; use a clean coding profile or focused custom agent for repeat workflows. Each MCP tool costs ~100-500 tokens per agent step. If shell output is still large after that, evaluate one output filter such as [RTK](https://github.com/rtk-ai/rtk) or [`snip`](https://github.com/edouard-claude/snip) | Removes tool/schema overhead and noisy command output | 5-10 minutes |
| 10 | **Convert rich files to Markdown before AI work** — `.docx`, `.pdf`, `.pptx`, `.xlsx`, HTML, images, audio, video, and ZIPs carry format tax. [Marc Bara's writeup](https://medium.com/@marc.bara.iniesta/your-docx-is-wasting-33-of-your-ai-budget-86a3d229d042) shows the cost; use [Microsoft MarkItDown](https://github.com/microsoft/markitdown) before chat, agent, or RAG ingestion | Reduces noisy input context | 5 minutes |
| 11 | **Run `/chronicle cost tips` and `/chronicle improve` weekly** (**Copilot CLI only**, experimental) — these slash commands work in interactive Copilot CLI sessions (not VS Code), not as a general Copilot Chat feature. `cost tips` analyzes your token spend and suggests reductions; `improve` finds recurring confusion in your CLI session history and generates custom-instruction fixes so the same misread intent stops costing tokens forever | Cuts recurring rework and direct token spend | 2 minutes per run |
| 12 | **Try CodeAct for long tool chains** (**Copilot CLI only**, optional external plugin) — [`copilot-codeact-plugin`](https://github.com/jsturtevant/copilot-codeact-plugin) collapses multi-step tool chains into one sandboxed execution, which can reduce repeated replay of system prompt, prior messages, and tool definitions | Reduces tool-loop replay | 10-15 minutes |
@@ -37,7 +37,7 @@ Don't have time to read the full guide? Do these today and cut your token usage:
*Figures above are scoped to the mechanism named in each row, are not additive, and do not equal total bill reduction.*
-Output control (#1, #2) pays off immediately and compounds — set it once, save on every call. Structural input control (#3, #6) compounds across every interaction. Model routing (#4, #5) reduces cost at the billing tier. Model-specific prompt tuning (#8) cuts waste by improving first-pass quality. MCP audit (#9) eliminates thousands of hidden tokens per agent task. Markdown conversion (#10) removes DOCX/PDF/HTML layout noise before the model ever sees it. Graph-based navigation (#14) front-loads codebase orientation once, then reuses it across agent sessions.
+Output control (#1, #2) pays off immediately and compounds — set it once, save on every call. Structural input control (#3, #6) compounds across every interaction. Model routing (#4, #5) reduces cost at the billing tier. Model-specific prompt tuning (#8) cuts waste by improving first-pass quality. MCP audit (#9) eliminates thousands of hidden tokens per agent task; RTK/snip-style output filters address the separate cost of verbose shell results. Markdown conversion (#10) removes DOCX/PDF/HTML layout noise before the model ever sees it. Graph-based navigation (#14) front-loads codebase orientation once, then reuses it across agent sessions.
---
@@ -79,7 +79,7 @@ Research on LLM-generated context files suggests they often hurt agent correctne
#### [2.7 MCP & Tool Costs](docs/08-mcp-tool-costs.md)
-The hidden token tax: each MCP tool costs 100-500 tokens per agent step. 15 servers × 15 steps = 265K tokens of overhead. Audit guide included.
+The hidden token tax: each MCP tool costs 100-500 tokens per agent step. 15 servers × 15 steps = 265K tokens of overhead. Covers MCP audit, Copilot harness baseline, RTK, snip, minimal-context-tools, and adjacent output/context-compression tools.
---
diff --git a/docs/04-context-management.md b/docs/04-context-management.md
index 82207c9..a1387d3 100644
--- a/docs/04-context-management.md
+++ b/docs/04-context-management.md
@@ -292,7 +292,7 @@ graphify-out/
- Code extraction is local and deterministic for the AST pass; optional semantic/deep extraction over docs, PDFs, images, or media may use a configured AI backend.
- The graph can go stale after large refactors. Rebuild it or use Graphify's update/watch/hook flows where appropriate.
- `GRAPH_REPORT.md` is generated output. Treat it as a map, not the source of truth.
-- Graphify complements RTK. Graphify reduces repeated codebase-navigation input; RTK compresses verbose shell/tool output.
+- Graphify complements RTK or snip. Graphify reduces repeated codebase-navigation input; shell-output filters compress verbose command results.
---
diff --git a/docs/06-workflow-optimization.md b/docs/06-workflow-optimization.md
index 7c58120..e66b0fb 100644
--- a/docs/06-workflow-optimization.md
+++ b/docs/06-workflow-optimization.md
@@ -95,11 +95,11 @@ When not to use it:
Keep the claim bounded: this guide is **not** benchmarking CodeAct itself. The plugin README reports lower token use on its own benchmark prompts, including MCP-loaded cases, but that is plugin-reported task data, not a universal savings baseline.
-### Complementary: RTK for tool output compression
+### Complementary: RTK or snip for tool output compression
-CodeAct reduces the *number* of tool calls. [**RTK (Rust Token Killer)**](https://github.com/rtk-ai/rtk) reduces the *size* of each tool call's result. They address different sides of the same problem and can be used together.
+CodeAct reduces the *number* of tool calls. [**RTK (Rust Token Killer)**](https://github.com/rtk-ai/rtk) and [`snip`](https://github.com/edouard-claude/snip) reduce the *size* of each shell tool result. They address different sides of the same problem and can be used together.
-RTK is a CLI proxy that intercepts `git`, `cargo test`, `grep`, `ls`, and 100+ other dev commands and compresses their output before it reaches the agent — 60–90% savings per command. Unlike CodeAct, RTK is not limited to Copilot CLI; it can help across Copilot surfaces when the shell hook is reliable. Treat Windows setups as a pilot, not a default rollout. See [MCP & Tool Costs §2.7.7](08-mcp-tool-costs.md#277-compress-tool-output-at-the-source-rtk) for setup and the full command list.
+These tools intercept `git`, test runners, `grep`, `ls`, and other dev commands and compress their output before it reaches the agent — often 60–90% savings on verbose command output. Unlike CodeAct, this is not about Copilot CLI only; it can help anywhere the shell hook is reliable. Treat Windows and preview hook paths as pilots, not default rollouts. See [MCP & Tool Costs §2.7.7](08-mcp-tool-costs.md#277-compress-tool-output-at-the-source-rtk) and [§2.7.8](08-mcp-tool-costs.md#278-rtk-alternative-snip) for setup.
## 2.5.4 Default to Auto Model Selection
@@ -304,6 +304,35 @@ The most expensive tokens are the ones spent reaching a *wrong* outcome: an agen
For the fuller outcome-per-token frame, skill taxonomy, benchmark caveats, and current model routing matrix, see [Outcome per Token](13-outcome-per-token.md).
+## 2.5.10 Layer Tooling on Top of the Copilot Harness
+
+Copilot CLI and VS Code Copilot already optimize parts of the agent loop. Treat that as the baseline before adding external tools:
+
+- **Prompt/cache layer:** keep `{model, active MCP set, active agent/profile}` stable so cached prefixes stay reusable.
+- **Tool-schema layer:** prefer built-in tools and scoped MCPs; Copilot can defer or route some tool definitions, but extra servers and extensions still add surface area.
+- **Transport/session layer:** WebSocket reuse and automatic compaction help long agent runs, but compaction summarizes what the agent already saw.
+- **Terminal-output layer:** built-in truncation is a safety net, not a semantic filter.
+
+Add third-party tools only for the layer they actually improve:
+
+| Layer | Tooling | What it reduces |
+|-------|---------|-----------------|
+| Workflow turns | CodeAct | Repeated replay from many small tool calls in Copilot CLI |
+| Command output | RTK or snip | Verbose `git`, test, grep, build, and infra command output |
+| Command choice | minimal-context-tools | Broad file reads and iterative searching by steering toward `rg`, `fd`, `jq`, `ast-grep` |
+| Codebase orientation | Graphify | Repeated structural file reads across sessions |
+| Visibility/audit | Tokalator, token-optimizer | Waste you would otherwise miss; not compression by itself |
+
+**Rule:** one tool per layer. Combining CodeAct with RTK or snip can make sense because one reduces turn count and the other reduces output size. Running RTK and snip on the same command path usually does not — it can double-truncate output and make failures harder to inspect.
+
+Use this order when tuning a session:
+
+1. Pick the Copilot lane once: model, mode, active MCP/tool set, and agent/profile.
+2. Disable unused MCP servers and extension-provided tools.
+3. Use skills or focused agent instructions to make tool calls precise.
+4. Add one shell-output filter if command output is still large.
+5. Start a fresh session when changing lanes instead of mutating a long thread.
+
---
**Next:** [The AGENTS.md Problem →](07-agents-md-problem.md)
diff --git a/docs/08-mcp-tool-costs.md b/docs/08-mcp-tool-costs.md
index dc21af8..031c8e7 100644
--- a/docs/08-mcp-tool-costs.md
+++ b/docs/08-mcp-tool-costs.md
@@ -165,12 +165,15 @@ Don't enable every MCP server globally. Use workspace-level configuration:
6. **Use skills instead of MCPs for occasional capabilities** — MCP tool schemas load on every step whether used or not. Skills load only title and description upfront; the full content pulls on demand. If a capability is used in fewer than half your sessions, a skill is cheaper. See [Practical Setup §4.2](10-practical-setup.md#mcps-vs-skills-eager-vs-lazy-context-loading) for the full comparison
7. **Optional, Copilot CLI only: try CodeAct for long tool chains** — external plugin [`copilot-codeact-plugin`](https://github.com/jsturtevant/copilot-codeact-plugin) collapses many small tool hops into one sandboxed execution. That does not shrink any one server's schema, but it can reduce how often the full tool catalog gets replayed on CLI-heavy tasks
8. **Use a focused custom agent for repeat coding workflows** — a custom agent can carry a narrow tool list and stable instructions, so the same coding workflow starts with the same active surface instead of whatever the default chat currently exposes. Where your Copilot surface supports model selection in agent/profile files, pin the intended model there too
-9. **Compress tool output at the source with RTK** — [RTK (Rust Token Killer)](https://github.com/rtk-ai/rtk) is a CLI proxy that filters the *results* of shell commands before they reach the agent. Confirmed to work well in VS Code Copilot on macOS/Linux with repo-by-repo setup. Treat Windows as experimental and validate before rolling it out broadly. Reductions are real but vary by command and project output volume. See §2.7.7
+9. **Compress tool output at the source with RTK or snip** — [RTK (Rust Token Killer)](https://github.com/rtk-ai/rtk) and [`snip`](https://github.com/edouard-claude/snip) are CLI proxies that filter the *results* of shell commands before they reach the agent. Reductions are real but vary by command, project output volume, and hook reliability. See §2.7.7 and §2.7.8
+10. **Use minimal-context skills before adding more tools** — [`minimal-context-tools`](https://github.com/SebastienDegodez/copilot-instructions/tree/main/plugins/minimal-context-tools) packages skills for `rg`, `fd`, `jq`, `yq`, `ast-grep`, and related CLIs. The pattern is cheap because it steers the agent toward precise one-shot commands before any large output exists. Pair it with RTK/snip when shell output is still noisy.
## 2.7.7 Compress Tool Output at the Source: RTK
MCP schema overhead is the cost *before* any work. Separately, every shell command the agent runs produces output that becomes input tokens on the next step. A failing `cargo test` or `git diff` on a large PR can return 10,000–25,000 tokens of raw text — passing test lines, unchanged diff context, build noise — that the agent reads in full.
+Copilot already has harness-level savings: prompt caching, deferred tool schemas, WebSocket transport, context compaction, and large-output caps. Those features do not replace output filters. VS Code's terminal tool uses a hard head/tail-style output limit; Copilot CLI also warns the model to limit output and filter with `head`, `tail`, `grep`, or `awk`. That is useful safety net behavior, not semantic parsing. RTK and snip act earlier: they turn verbose command output into a smaller domain-specific summary before the harness has to truncate it.
+
[**RTK (Rust Token Killer)**](https://github.com/rtk-ai/rtk) is a CLI proxy that sits between the shell and the agent. It runs the original command, captures the output, applies per-command filters (noise removal, keeping only failing tests, deduplicating log lines, grouping file listings), and returns the compressed result. The agent sees smaller output; its behavior is otherwise unchanged.
**How it works, step by step:**
@@ -205,17 +208,19 @@ curl -fsSL https://raw.githubusercontent.com/rtk-ai/rtk/refs/heads/master/instal
**Windows caveat:** RTK is strongest today on Unix-like shell paths. On Windows, shell-hook behavior and path handling can be brittle, especially across PowerShell, Git Bash, WSL, and VS Code agent execution. Treat it as a pilot, not a default recommendation: test it on the exact repo and shell your team uses, and skip it if the setup causes command failures or noisy behavior.
-**Setting up for VS Code Copilot — per-repo:**
+**Setting up for Copilot:**
-For VS Code Copilot, RTK installs a PreToolUse hook scoped to the current repository. Run this once inside each repo where you want RTK active:
+For Copilot, RTK installs a PreToolUse hook and awareness instructions. Project-scoped setup writes into `.github/`; newer RTK builds also document a global Copilot install under `~/.copilot/` / `$COPILOT_HOME`. Validate on your Copilot surface before rolling it out because hook contracts move faster than static docs.
```bash
cd your-repo
rtk init --copilot
-# Restart VS Code
+
+# Optional global Copilot setup where supported by your RTK version:
+rtk init -g --copilot
```
-This is a per-repo setup — there is no single global install that covers all VS Code workspaces. Once enabled in a repo, the hook is transparent: your terminal commands are unchanged; only the agent's Bash tool calls are intercepted.
+Once enabled, the hook is transparent: your terminal commands are unchanged; only the agent's Bash tool calls are intercepted. If your environment does not support the global Copilot hook path reliably, keep the per-repo setup and document it for each team workspace.
**Other AI tools (global install available):**
@@ -230,7 +235,73 @@ rtk init --agent cline # Cline / Roo Code (project-level)
**Pairs with MCP reduction:** Schema audit (§2.7.4–2.7.6) cuts the definition cost that reloads every step. RTK cuts what each tool call *returns*. Both address different parts of the token budget and work together.
-## 2.7.8 Case Study: Scoping a Large Plugin — Azure MCP
+## 2.7.8 RTK Alternative: snip
+
+[`snip`](https://github.com/edouard-claude/snip) solves the same class of problem as RTK: shell commands still run normally, but the agent receives a filtered result instead of raw noisy output. The main difference is extensibility. RTK ships a compiled Rust command registry; snip uses declarative YAML filters that users and teams can add without touching Go code.
+
+**When snip is most attractive:**
+
+- you want custom filters for project-specific tools
+- you want local savings stats via `snip gain`
+- you prefer YAML filter contribution over compiled command rules
+- you need Copilot CLI hook support and can validate the hook path in your environment
+
+**Install:**
+
+```bash
+brew install edouard-claude/tap/snip
+# or
+go install github.com/edouard-claude/snip/cmd/snip@latest
+```
+
+**Copilot setup:**
+
+```bash
+snip init --agent copilot
+```
+
+At the time of writing, snip's Copilot path writes a `preToolUse` hook for Copilot CLI. VS Code Copilot agent hooks are still a moving surface, so treat VS Code setup as a pilot unless your team has validated the exact version and workspace configuration.
+
+**Filter model:**
+
+```yaml
+name: "git-log"
+match:
+ command: "git"
+ subcommand: "log"
+pipeline:
+ - action: "head"
+ n: 20
+```
+
+Snip supports pipeline actions such as keeping or removing matching lines, head/tail truncation, ANSI stripping, JSON extraction, regex extraction, grouping, deduplication, aggregation, and templates. Project-local filters require trust approval, which is the right default for teams: output filters influence what the model sees, so they should be reviewed like tool configuration.
+
+**RTK vs. snip:**
+
+| Choice | Pick when |
+|--------|-----------|
+| RTK | You want a single Rust binary, broad agent support, and compiled defaults |
+| snip | You want YAML filters, local stats, and easier project/team customization |
+
+Do not stack RTK and snip on the same command path by default. Pick one output-filter layer per agent surface, then measure. Stacking can double-truncate output and make debugging harder.
+
+## 2.7.9 Adjacent Ecosystem: What Else Belongs in the Mental Model
+
+Not every token tool is a direct RTK/snip alternative. Keep these categories separate:
+
+| Tool | Category | Use it for | Caveat |
+|------|----------|------------|--------|
+| [`snip-ai/snip`](https://github.com/snip-ai/snip) | Claude Code-focused output filter | Read/Bash/Grep/Glob optimization with AST-aware code handling | Different project from `edouard-claude/snip`; no Copilot path verified |
+| [Redcon / ContextBudget](https://github.com/natiixnt/ContextBudget) | Context packing + command compression | Team workflows that want command compressors plus CI quality gates | License and product boundary should be reviewed before rollout |
+| [Headroom](https://github.com/headroomlabs-ai/headroom) | Full-stack compression wrapper | Broader file, command, memory, and MCP compression experiments | Validate `headroom wrap copilot` before documenting as standard setup |
+| [Tokalator](https://github.com/vfaraji89/tokalator) | VS Code token visibility | Budget dashboards, model/context-window awareness, instruction-file scans | Monitoring only; does not compress |
+| [token-optimizer](https://github.com/alexgreensh/token-optimizer) | Context audit/status tooling | Auditing stale memory, configs, compaction loss, and model routing | PolyForm Noncommercial license |
+| [Caveman](https://github.com/JuliusBrussee/caveman) | Model-output compression | Shorter assistant responses and terse style packs | Does not reduce shell-command input; prompt overhead matters |
+| [ACON](https://github.com/microsoft/acon) | Research framework | Academic grounding for long-horizon context compression | Not a drop-in developer tool |
+
+The practical stack is: keep Copilot's harness stable, reduce always-loaded MCP/schema overhead, steer the agent toward precise commands, then use one semantic output filter where command output is still large.
+
+## 2.7.10 Case Study: Scoping a Large Plugin — Azure MCP
A single plugin can dominate your `System/Tools` budget. Dina Berry (Microsoft/GitHub content contributor) audited her Copilot CLI setup with `/context` and found the Azure MCP plugin loading **~27K tokens per message** by default — more than all her other MCP servers combined.
diff --git a/docs/09-comparisons-data.md b/docs/09-comparisons-data.md
index 149f322..37f9631 100644
--- a/docs/09-comparisons-data.md
+++ b/docs/09-comparisons-data.md
@@ -107,11 +107,15 @@ The complete comparison of every technique covered in this guide:
| J2 | Per-workspace MCP config | Variable | — | None | Medium | Multi-project setups |
| J3 | Minimize tool calls (instructions) | 10-30% | — | Neutral | Low | Agent mode |
| J4 | Compress tool output with [RTK](https://github.com/rtk-ai/rtk) | 60-90% of shell cmd output | — | None | Low | Agent / Coding Agent — any AI tool |
+| J5 | Compress tool output with [snip](https://github.com/edouard-claude/snip) | 60-90% of shell cmd output; command-specific examples report higher | — | None | Low | Copilot CLI / agent shells where hook path is validated |
+| J6 | Use minimal-context skills before more tools | 70-95% on targeted search/query patterns (tool-reported) | — | Improves targeting | Medium | Agent workflows that repeatedly search/read too broadly |
+| J7 | Evaluate broad compression wrappers (Redcon / Headroom) | Tool-reported; varies by command/context pack | — | Depends | Medium | Teams willing to validate external wrappers and licenses |
| **Agent Mode Configuration** |
| K1 | Precise prompts + acceptance criteria | 30-60% | — | Improves | Low | Agent tasks |
| K2 | Plan files for complex tasks | 15-40% | — | Improves | Medium | Multi-step agent tasks |
| K3 | Cap agent maxRequests | Variable | — | Risk truncation | Low | All agent tasks |
| K4 | Mode selection (Ask/Edit/Agent) | 60-90% | — | Good | Low | Every interaction |
+| K5 | CodeAct for long Copilot CLI tool chains | 49-69% input tokens in plugin benchmarks | — | Depends | Medium | Copilot CLI exploration/audit sessions |
> †A1/A2 output savings require system-level terse output instructions (see B5). Writing terse prompts alone saves input tokens; output tokens are only reduced if the model is instructed to respond tersely.
@@ -119,6 +123,8 @@ The complete comparison of every technique covered in this guide:
> C6 source: [Graphify benchmarks](https://github.com/Graphify-Labs/graphify/blob/main/BENCHMARKS.md) and project documentation. Treat the high-end 71.5× number as structural-navigation best case on large codebases, not a universal savings guarantee.
+> J5-J7/K5 sources are external project-reported numbers, not independent guide benchmarks. Treat them as candidates to pilot, not universal bill-reduction guarantees. Do not stack multiple shell-output filters on the same command path without measuring for lost detail.
+
### The Big Winners
If you do nothing else, do these eight. Ranked by impact-to-effort ratio:
diff --git a/docs/10-practical-setup.md b/docs/10-practical-setup.md
index 7f68c13..fe3748d 100644
--- a/docs/10-practical-setup.md
+++ b/docs/10-practical-setup.md
@@ -254,6 +254,12 @@ Skills behave differently: only the **title and description** load upfront. The
**Rule:** Use MCPs for capabilities needed on most interactions. Use skills for occasional capabilities — you pay the full schema cost per turn with MCPs, but only per invocation with skills. If a tool is used in 1 in 10 conversations, a skill is roughly 10× cheaper in context overhead.
+### Optional: minimal-context-tools
+
+[`minimal-context-tools`](https://github.com/SebastienDegodez/copilot-instructions/tree/main/plugins/minimal-context-tools) packages this idea as skills for common low-token CLI patterns: `fd` for file discovery, `rg` for targeted text search, `jq`/`yq` for structured data, `ast-grep` for syntax-aware code queries, and `tokei` for code statistics.
+
+Use it as a behavior layer, not as another always-on MCP server. The point is to make the agent ask narrower questions before any output filter runs. It pairs well with RTK or snip: skills reduce how much the agent requests; RTK/snip reduce how much comes back.
+
## 4.3 GitHub Coding Agent Considerations
The Coding Agent runs autonomous sessions that can last minutes to hours. Token savings compound over those long sessions.
@@ -333,7 +339,7 @@ rtk init --copilot
# Restart VS Code
```
-RTK installs a PreToolUse hook into the current repository. Repeat per repo — there is no global VS Code Copilot install. Once active, the hook is transparent: your terminal is unchanged; only the agent's Bash tool calls are intercepted.
+RTK installs a PreToolUse hook into the current repository. Newer RTK builds also document a global Copilot hook path; validate that path on your Copilot surface before making it a team default. Once active, the hook is transparent: your terminal is unchanged; only the agent's Bash tool calls are intercepted.
On Windows, validate RTK before recommending it to a team. The hook path can be more fragile across PowerShell, Git Bash, WSL, and VS Code agent execution. If RTK adds setup friction or command failures, skip it and focus first on clean profiles, fewer MCP servers, precise prompts, and shorter command output.
@@ -379,6 +385,60 @@ The graph lives in `graphify-out/graph.json`. The human-readable map is `graphif
Note: code parsing is local for the AST pass. Optional semantic/deep extraction over docs, PDFs, images, or media may use a configured AI backend. Review that boundary before enabling extras on proprietary codebases.
+### 4.3.8 Compress Shell Command Output with snip
+
+[`snip`](https://github.com/edouard-claude/snip) is the closest practical alternative to RTK for Copilot-oriented shell-output compression. It runs commands normally, filters the output through declarative YAML pipelines, and can track local savings with `snip gain`.
+
+Install:
+
+```bash
+brew install edouard-claude/tap/snip
+# or:
+go install github.com/edouard-claude/snip/cmd/snip@latest
+```
+
+Set up Copilot CLI:
+
+```bash
+snip init --agent copilot
+```
+
+Use snip when you want project-specific or team-maintained filters without recompiling a tool. A filter can match a command/subcommand and apply actions like `head`, `tail`, `keep_lines`, `remove_lines`, `json_extract`, `regex_extract`, `group_by`, `dedup`, or `aggregate`.
+
+Example filter shape:
+
+```yaml
+name: "my-test-summary"
+match:
+ command: "my-test-runner"
+pipeline:
+ - action: "keep_lines"
+ pattern: "FAIL|ERROR|expected|actual"
+ - action: "head"
+ n: 80
+```
+
+**Team rollout:** start with one repo and one shell surface. Validate that failed tests, diffs, and build errors still preserve enough detail for the agent to fix the problem. Do not enable RTK and snip on the same command path by default; choose one filter layer and measure.
+
+### 4.3.9 Use a Session Harness Checklist
+
+A "harness" is not a separate install here. It is the stable set of controls around an agent session:
+
+```text
+model + mode + agent/profile + active MCP/tools + output filter + repo instructions
+```
+
+Before a long agent run, set those once and keep them stable. Changing them mid-session can invalidate cached prefixes and make the agent carry stale context under a new tool set.
+
+Use this checklist:
+
+1. Pick the mode: Ask/Edit/Agent/Coding Agent.
+2. Pick the model lane or Auto.
+3. Disable unused MCP servers and extension-provided tools.
+4. Pick one command-output filter if needed: RTK or snip.
+5. Use Graphify if repeated codebase orientation dominates.
+6. Start a fresh session if you need to change the lane.
+
## 4.4 Building the Habit
### Start Small
diff --git a/docs/index.md b/docs/index.md
index 94f28f5..d8e1c4e 100644
--- a/docs/index.md
+++ b/docs/index.md
@@ -25,7 +25,7 @@ Practical guide to reducing GitHub Copilot token spend while keeping answers and
6. Disable MCP servers you are not using.
7. Convert DOCX/PDF/Office/media inputs to Markdown before AI work; start with [MarkItDown](https://github.com/microsoft/markitdown).
8. Audit long-running agent sessions and repeated back-and-forth.
-9. Install [RTK](https://github.com/rtk-ai/rtk) — CLI proxy that filters `git`, test runners, `grep`, and 100+ other shell commands before output reaches the agent. One install, 60-90% savings on tool-call results in agent and coding-agent sessions.
+9. Install one shell-output filter: [RTK](https://github.com/rtk-ai/rtk) or [`snip`](https://github.com/edouard-claude/snip). These CLI proxies filter `git`, test runners, `grep`, build tools, and other command output before it reaches the agent. Use one filter layer per command path; do not stack them by default.
10. Build a persistent codebase graph with [Graphify](https://github.com/Graphify-Labs/graphify) — map code once via tree-sitter AST, write `graphify-out/graph.json`, then let agents query the graph instead of re-reading project files each session. Install: `uv tool install graphifyy`.
## Read by Topic
@@ -68,6 +68,8 @@ Practical guide to reducing GitHub Copilot token spend while keeping answers and
- [LLMLingua](https://github.com/microsoft/LLMLingua)
- [Caveman project](https://github.com/JuliusBrussee/caveman)
- [RTK — Rust Token Killer](https://github.com/rtk-ai/rtk)
+- [snip](https://github.com/edouard-claude/snip) — YAML-extensible shell-output filter for Copilot CLI and other agent shells
+- [minimal-context-tools](https://github.com/SebastienDegodez/copilot-instructions/tree/main/plugins/minimal-context-tools) — skill pack for lower-context CLI search/query patterns
- [Graphify](https://github.com/Graphify-Labs/graphify) — build a persistent knowledge graph of your codebase; agents query `graphify-out/graph.json` instead of re-reading files. Supports GitHub Copilot, VS Code workflows, and other assistants. PyPI package: `graphifyy`
- [Microsoft MarkItDown](https://github.com/microsoft/markitdown) — convert PDF, Office files, images, audio, HTML, ZIP contents, YouTube URLs, EPUBs, and more to Markdown for LLM workflows
- [Marc Bara: "Your .docx Is Wasting 33% of Your AI Budget"](https://medium.com/@marc.bara.iniesta/your-docx-is-wasting-33-of-your-ai-budget-86a3d229d042)
From fb588fb85c9e6bf946aa1b101d951af334b01d91 Mon Sep 17 00:00:00 2001
From: Marco Olivo <8478776+olivomarco@users.noreply.github.com>
Date: Sun, 12 Jul 2026 14:16:23 +0200
Subject: [PATCH 07/13] Add diagrams
---
README.md | 4 +
docs/01-why-tokens-matter.md | 18 +-
docs/02-prompt-compression.md | 2 +
docs/04-context-management.md | 8 +
docs/06-workflow-optimization.md | 6 +
docs/08-mcp-tool-costs.md | 2 +
docs/10-practical-setup.md | 38 +-
docs/12-enterprise-governance.md | 2 +
docs/13-outcome-per-token.md | 15 +-
docs/assets/diagrams/agent-cost-loop.png | Bin 0 -> 74361 bytes
docs/assets/diagrams/agent-cost-loop.svg | 49 +
docs/assets/diagrams/cache-stability.png | Bin 0 -> 76689 bytes
docs/assets/diagrams/cache-stability.svg | 51 +
.../diagrams/context-loading-boundaries.png | Bin 0 -> 77103 bytes
.../diagrams/context-loading-boundaries.svg | 39 +
.../enterprise-governance-control-plane.png | Bin 0 -> 113187 bytes
.../enterprise-governance-control-plane.svg | 63 ++
docs/assets/diagrams/format-tax-pipeline.png | Bin 0 -> 78597 bytes
docs/assets/diagrams/format-tax-pipeline.svg | 55 +
docs/assets/diagrams/graphify-navigation.png | Bin 0 -> 71920 bytes
docs/assets/diagrams/graphify-navigation.svg | 46 +
docs/assets/diagrams/mcp-tooling-stack.png | Bin 0 -> 77321 bytes
docs/assets/diagrams/mcp-tooling-stack.svg | 54 +
docs/assets/diagrams/mode-decision-tree.png | Bin 0 -> 88860 bytes
docs/assets/diagrams/mode-decision-tree.svg | 59 ++
.../diagrams/outcome-per-token-loop.png | Bin 0 -> 65287 bytes
.../diagrams/outcome-per-token-loop.svg | 47 +
docs/assets/diagrams/plan-execute-cheaply.png | Bin 0 -> 83870 bytes
docs/assets/diagrams/plan-execute-cheaply.svg | 52 +
.../diagrams/prompt-compression-ladder.png | Bin 0 -> 76213 bytes
.../diagrams/prompt-compression-ladder.svg | 58 +
docs/assets/diagrams/token-cost-anatomy.png | Bin 0 -> 92859 bytes
docs/assets/diagrams/token-cost-anatomy.svg | 47 +
docs/diagrams/agent-cost-loop.excalidraw | 665 ++++++++++++
docs/diagrams/cache-stability.excalidraw | 824 +++++++++++++++
.../context-loading-boundaries.excalidraw | 467 ++++++++
...rprise-governance-control-plane.excalidraw | 875 +++++++++++++++
docs/diagrams/format-tax-pipeline.excalidraw | 725 +++++++++++++
docs/diagrams/graphify-navigation.excalidraw | 721 +++++++++++++
docs/diagrams/mcp-tooling-stack.excalidraw | 884 ++++++++++++++++
docs/diagrams/mode-decision-tree.excalidraw | 998 ++++++++++++++++++
.../outcome-per-token-loop.excalidraw | 792 ++++++++++++++
docs/diagrams/plan-execute-cheaply.excalidraw | 863 +++++++++++++++
.../prompt-compression-ladder.excalidraw | 934 ++++++++++++++++
docs/diagrams/token-cost-anatomy.excalidraw | 877 +++++++++++++++
45 files changed, 10275 insertions(+), 65 deletions(-)
create mode 100644 docs/assets/diagrams/agent-cost-loop.png
create mode 100644 docs/assets/diagrams/agent-cost-loop.svg
create mode 100644 docs/assets/diagrams/cache-stability.png
create mode 100644 docs/assets/diagrams/cache-stability.svg
create mode 100644 docs/assets/diagrams/context-loading-boundaries.png
create mode 100644 docs/assets/diagrams/context-loading-boundaries.svg
create mode 100644 docs/assets/diagrams/enterprise-governance-control-plane.png
create mode 100644 docs/assets/diagrams/enterprise-governance-control-plane.svg
create mode 100644 docs/assets/diagrams/format-tax-pipeline.png
create mode 100644 docs/assets/diagrams/format-tax-pipeline.svg
create mode 100644 docs/assets/diagrams/graphify-navigation.png
create mode 100644 docs/assets/diagrams/graphify-navigation.svg
create mode 100644 docs/assets/diagrams/mcp-tooling-stack.png
create mode 100644 docs/assets/diagrams/mcp-tooling-stack.svg
create mode 100644 docs/assets/diagrams/mode-decision-tree.png
create mode 100644 docs/assets/diagrams/mode-decision-tree.svg
create mode 100644 docs/assets/diagrams/outcome-per-token-loop.png
create mode 100644 docs/assets/diagrams/outcome-per-token-loop.svg
create mode 100644 docs/assets/diagrams/plan-execute-cheaply.png
create mode 100644 docs/assets/diagrams/plan-execute-cheaply.svg
create mode 100644 docs/assets/diagrams/prompt-compression-ladder.png
create mode 100644 docs/assets/diagrams/prompt-compression-ladder.svg
create mode 100644 docs/assets/diagrams/token-cost-anatomy.png
create mode 100644 docs/assets/diagrams/token-cost-anatomy.svg
create mode 100644 docs/diagrams/agent-cost-loop.excalidraw
create mode 100644 docs/diagrams/cache-stability.excalidraw
create mode 100644 docs/diagrams/context-loading-boundaries.excalidraw
create mode 100644 docs/diagrams/enterprise-governance-control-plane.excalidraw
create mode 100644 docs/diagrams/format-tax-pipeline.excalidraw
create mode 100644 docs/diagrams/graphify-navigation.excalidraw
create mode 100644 docs/diagrams/mcp-tooling-stack.excalidraw
create mode 100644 docs/diagrams/mode-decision-tree.excalidraw
create mode 100644 docs/diagrams/outcome-per-token-loop.excalidraw
create mode 100644 docs/diagrams/plan-execute-cheaply.excalidraw
create mode 100644 docs/diagrams/prompt-compression-ladder.excalidraw
create mode 100644 docs/diagrams/token-cost-anatomy.excalidraw
diff --git a/README.md b/README.md
index 567f231..f89aac7 100644
--- a/README.md
+++ b/README.md
@@ -14,6 +14,8 @@
> **Output tokens cost much more than input tokens.** That's the most important pricing fact in this guide. Anthropic's public pricing makes the asymmetry concrete ($1/$5 Haiku, $3/$15 Sonnet, $5/$25 Opus per MTok input/output). Copilot's exact per-model UBB pricing table is not public yet, but UBB still makes verbose output disproportionately expensive. Most input tokens come from file context, history, and tool schemas — not from what you type. Your typed prompt is a tiny fraction of total input. Start with output control, then tackle structural input wins.
+
+
Don't have time to read the full guide? Do these today and cut your token usage:
| # | Action | Primary Effect | Time to Set Up |
@@ -39,6 +41,8 @@ Don't have time to read the full guide? Do these today and cut your token usage:
Output control (#1, #2) pays off immediately and compounds — set it once, save on every call. Structural input control (#3, #6) compounds across every interaction. Model routing (#4, #5) reduces cost at the billing tier. Model-specific prompt tuning (#8) cuts waste by improving first-pass quality. MCP audit (#9) eliminates thousands of hidden tokens per agent task; RTK/snip-style output filters address the separate cost of verbose shell results. Markdown conversion (#10) removes DOCX/PDF/HTML layout noise before the model ever sees it. Graph-based navigation (#14) front-loads codebase orientation once, then reuses it across agent sessions.
+
+
---
## Guide Contents
diff --git a/docs/01-why-tokens-matter.md b/docs/01-why-tokens-matter.md
index 79825b2..4da9c12 100644
--- a/docs/01-why-tokens-matter.md
+++ b/docs/01-why-tokens-matter.md
@@ -49,23 +49,7 @@ Every token you send or receive has a cost. Here's how:
Understanding what Copilot does behind the scenes helps you optimize:
-```text
-┌─────────────────────────────────────────────────┐
-│ Context Window │
-│ │
-│ ┌──────────────────┐ ┌─────────────────────┐ │
-│ │ INPUT TOKENS │ │ OUTPUT TOKENS │ │
-│ │ │ │ │ │
-│ │ System prompt │ │ The response │ │
-│ │ + copilot- │ │ you receive │ │
-│ │ instructions │ │ │ │
-│ │ + file context │ │ │ │
-│ │ + conversation │ │ │ │
-│ │ history │ │ │ │
-│ │ + YOUR prompt │ │ │ │
-│ └──────────────────┘ └─────────────────────┘ │
-└─────────────────────────────────────────────────┘
-```
+
- **System prompt:** Copilot's own instructions (you can't control this)
- **`copilot-instructions.md`:** Your project-level instructions — loaded on **every** interaction
diff --git a/docs/02-prompt-compression.md b/docs/02-prompt-compression.md
index dc3de6b..a8c5b1e 100644
--- a/docs/02-prompt-compression.md
+++ b/docs/02-prompt-compression.md
@@ -8,6 +8,8 @@
The single most effective token optimization technique. Drop the linguistic scaffolding that adds tokens without adding information.
+
+
**What to drop:**
- Articles: a, an, the
diff --git a/docs/04-context-management.md b/docs/04-context-management.md
index a1387d3..004acca 100644
--- a/docs/04-context-management.md
+++ b/docs/04-context-management.md
@@ -101,6 +101,8 @@ Every file that enters context costs tokens. Be intentional about what's open an
When the source is a Word file, PDF, PowerPoint, spreadsheet, image, audio file, or exported HTML, do not paste the rich format directly into an AI workflow if you can avoid it. Convert it to clean Markdown first, then send the Markdown.
+
+
Marc Bara calls this the **format tax** in [Your .docx Is Wasting 33% of Your AI Budget](https://medium.com/@marc.bara.iniesta/your-docx-is-wasting-33-of-your-ai-budget-86a3d229d042): Word, PDF, and HTML carry font data, XML, page-positioning metadata, layout artifacts, embedded objects, and tag soup that models must process but rarely need. The article cites a concrete example where a 10-page report extracted from PDF used roughly 12,400 tokens, while the same content as clean Markdown used about 8,350 tokens — a 33% reduction with the same information. HTML exports can be even worse because semantic content gets wrapped in long tags, classes, IDs, and layout scaffolding.
The rule: use Markdown as the **working format** for AI interaction, and treat Word/PDF/PowerPoint as delivery formats. Draft, review, summarize, chunk, and retrieve from Markdown. Generate `.docx` or `.pdf` at the end only when a client, regulator, or internal process needs that artifact.
@@ -130,6 +132,8 @@ Most context files are loaded on **every** interaction. That's a tax you pay eve
The fix: prefer **conditional context** over always-on context.
+
+
### Use `applyTo:` paths in custom instructions
Custom instruction files in `.github/instructions/*.instructions.md` accept an `applyTo` frontmatter field that scopes the file to matching paths. Copilot only loads it when the conversation involves files matching the glob.
@@ -172,6 +176,8 @@ In long sessions, this is often the biggest single cost lever. When most of your
You can lean into this. Two practical patterns:
+
+
**1. Stable instructions at the top, volatile work at the bottom.** Cached context only works if the prefix of your conversation is stable. Don't reshuffle your `copilot-instructions.md` or rotate which files are open between every prompt — keep the stable layer stable, and let only the most recent message change.
**2. Reuse named context via slash commands and saved snippets.** When you frequently ask about the same domain, define it once and reference it. For example: keep a short customers-schema note or slash-command snippet, load it once for the session, then keep follow-up prompts anchored to that shared summary instead of re-pasting the schema every time.
@@ -257,6 +263,8 @@ The per-session codebase-read pattern is a hidden input cost: every new agent se
[Graphify](https://github.com/Graphify-Labs/graphify) attacks that cost differently from prompt compression. It parses the repo once with tree-sitter AST, writes a persistent `graphify-out/graph.json`, and lets agents query that graph instead of repeatedly reading source files for structure.
+
+
```bash
uv tool install graphifyy
diff --git a/docs/06-workflow-optimization.md b/docs/06-workflow-optimization.md
index e66b0fb..bebccb2 100644
--- a/docs/06-workflow-optimization.md
+++ b/docs/06-workflow-optimization.md
@@ -61,6 +61,8 @@ This is one of the higher-leverage savings opportunities in the guide.
**Ask Mode** is a single call. One question, one answer.
+
+
| Task | Right Mode | Why |
|------|-----------|-----|
| "What does this function do?" | Ask | Single-shot answer. No tool use needed |
@@ -291,6 +293,8 @@ The most expensive tokens are the ones spent reaching a *wrong* outcome: an agen
**The two-phase pattern:**
+
+
1. **Plan in plan mode (or Ask mode) first.** Use Copilot CLI's plan mode (or VS Code Ask mode) to think through the approach *before* any code is written — files to touch, order of changes, edge cases, acceptance criteria. Planning is cheap: it's mostly reasoning, no large diffs, no repeated tool loops. This is where a stronger model earns its cost, because a good plan prevents expensive rework downstream.
2. **Save the plan, then execute it.** Write the agreed plan to a file (e.g. `plan.md`) or a tracked issue, then start a **fresh session** and prompt the execution against that saved plan. A clean session keeps the cacheable prefix stable (see [Caching §2.3.5](04-context-management.md#235-caching-store-and-reuse-context-within-prompts)) and avoids dragging the whole planning conversation forward as input tokens on every execution turn.
@@ -308,6 +312,8 @@ For the fuller outcome-per-token frame, skill taxonomy, benchmark caveats, and c
Copilot CLI and VS Code Copilot already optimize parts of the agent loop. Treat that as the baseline before adding external tools:
+
+
- **Prompt/cache layer:** keep `{model, active MCP set, active agent/profile}` stable so cached prefixes stay reusable.
- **Tool-schema layer:** prefer built-in tools and scoped MCPs; Copilot can defer or route some tool definitions, but extra servers and extensions still add surface area.
- **Transport/session layer:** WebSocket reuse and automatic compaction help long agent runs, but compaction summarizes what the agent already saw.
diff --git a/docs/08-mcp-tool-costs.md b/docs/08-mcp-tool-costs.md
index 031c8e7..8acacbd 100644
--- a/docs/08-mcp-tool-costs.md
+++ b/docs/08-mcp-tool-costs.md
@@ -8,6 +8,8 @@
Most context waste hides in things you never examine. Before tuning MCP servers or instruction files, check what's actually in your context window.
+
+
**Copilot CLI:** run `/context` mid-session to get a real breakdown:
```text
diff --git a/docs/10-practical-setup.md b/docs/10-practical-setup.md
index fe3748d..702e622 100644
--- a/docs/10-practical-setup.md
+++ b/docs/10-practical-setup.md
@@ -489,28 +489,7 @@ Each mode has a fundamentally different token cost profile:
Understanding the loop helps you minimize steps:
-```text
-Step 1: Load context
- ├── System prompt (~500 tokens)
- ├── copilot-instructions.md (~50-1500 tokens)
- ├── Tool definitions (~2,000-20,000 tokens)
- ├── Conversation history (growing)
- └── YOUR prompt
- → Send to LLM → Get response
-
-Step 2: LLM decides to call a tool
- ├── Tool call (function + params) → output tokens
- ├── Tool result → input tokens (next step)
- └── Reasoning about result → output tokens
-
-Step 3: Another tool call (or generate response)
- ├── ALL of Step 1's context reloaded
- ├── + Step 2's tool call and result
- └── + growing conversation
- → Send to LLM again
-
-... repeat 5-25 times
-```
+
**Key insight:** Context grows with every step. Step 15 carries all the context from steps 1-14 plus the original prompt. This is why long agent sessions get expensive fast.
@@ -597,20 +576,7 @@ These directives reduce unnecessary tool calls. Each skipped tool call saves 100
### 4.5.6 Decision Framework: When to Use Each Mode
-```text
-Question about code/syntax/concept?
- → Ask Mode (1 call, ~500-2,000 tokens)
-
-Change to a single file?
- → Edit Mode (1-2 calls, ~1,000-4,000 tokens)
-
-Multi-file change with clear scope?
- → Agent Mode with precise prompt (~5-10 steps, ~15,000-50,000 tokens)
-
-Vague "fix this" or "improve that"?
- → DON'T use Agent Mode yet. Clarify scope first in Ask Mode.
- → Then switch to Agent with precise prompt.
-```
+
**A costly pattern:** Using Agent Mode for a vague prompt, watching it explore for 20 steps, then realizing it misunderstood and starting over. That can double token use without improving the result.
diff --git a/docs/12-enterprise-governance.md b/docs/12-enterprise-governance.md
index a12ef8d..c7e10bf 100644
--- a/docs/12-enterprise-governance.md
+++ b/docs/12-enterprise-governance.md
@@ -16,6 +16,8 @@ Three levers matter most:
Prompt compression still matters, but it is a usage-efficiency lever. It is not an admin billing control.
+
+
One timing rule matters: June 1, 2026 is the cutoff. After that, Business and Enterprise governance shifts to AI-credit usage under usage-based billing. Treat premium requests as legacy transition context, not as the main planning model.
## 1. Set Budgets First
diff --git a/docs/13-outcome-per-token.md b/docs/13-outcome-per-token.md
index 0acaca3..690ca6b 100644
--- a/docs/13-outcome-per-token.md
+++ b/docs/13-outcome-per-token.md
@@ -38,6 +38,8 @@ The implication is simple: optimize the loop, not the sentence.
High outcome per token comes from six habits:
+
+
1. pick the right task shape
2. plan before implementation
3. route the right model to the right phase
@@ -244,18 +246,7 @@ Stale sessions accumulate decisions, tool output, file reads, and abandoned appr
The strongest pattern is two separate phases:
-```text
-Phase 1: Plan
- model: strong reasoning model
- mode: Plan / Ask / cloud-agent research
- output: saved plan with steps and acceptance criteria
-
-Phase 2: Execute
- model: cheaper or mid-tier model
- mode: fresh agent session
- input: saved plan + targeted files only
- output: verified implementation
-```
+
GitHub's [Optimize AI Usage](https://docs.github.com/en/copilot/tutorials/optimize-ai-usage) guidance makes the same point: defaulting to the most capable model can increase token usage without improving the outcome, and overusing reasoning models in execution-heavy tasks can reduce quality by making the model overthink or introduce unnecessary changes.[^optimize-ai] The same page gives the practical rule: plan with a strong reasoning model, then implement with a cheaper model.
diff --git a/docs/assets/diagrams/agent-cost-loop.png b/docs/assets/diagrams/agent-cost-loop.png
new file mode 100644
index 0000000000000000000000000000000000000000..6229cef15dcd5d10a972992f16139f7c73ee5b03
GIT binary patch
literal 74361
zcmd?R=U-Dx)HaNVqbR7TH0cKs5D<{wK|uil>Ai~d8tI+rp{YobDj-Gaz1IK{kd^?U
zh0qbH0TQH!BqY2W&vSox|A6Pqb4z|dwwdfbGi%mbbFFKx@Lo?x{RTA)H3bF5jprIq
z4Jarsms3zsN?iR5cn3M~uPpHE$}27PrxfQGKlz;{DHIg{P&|M7#3<;??qZ-7{Q&X%
zep_S#ZYld8fs>`sy{uAxUeWjH;(;>*$!C)ly!c}2`1hSmyO#@Q1i$^m`1d86P8%Yr
zZbN}q=BCWwqX^QB^h>C0ac&_4|nl<|_Jy21lK+xza)9wPkwoz^RV8s5ZI=#QQy
zr({E2i5#RmeCn}Eit<(Qi(du#A3U^ZaYdc#Q^rdd8I>^#SwmlqOivDN`W#YsC@yA8
z#^059``-GAvZ`_onZ?zlU1r4u@kQmT#wO;r`y7XOd3ELFR6%0hD>n2yA%S<5osv=t
zRHFr1GItNPC-6|lnnjKl5k*C<0^}(^1h+d)9*X6QiM@yL33#J;t0Lg}$U1-Lgl`Lh>i%rq?6mtM5_uzND~D`9@bIf7l|%LK=m9
z$j@)x?z8%Boz-x(WMiG_G$_~)JLU#ktIL^d5$hUHPM$E{X~85Y`y9FaLhj542VV{d
zXs-4eeUTmIj~?^ceRqkA>r%hv14Dsxn~s2E0;VKobQ5?^NNB%A;+IEWgSAgO9mF!<
z6RX|Jono8X8!a#itt9yXPMOzRYwI5?cNaS94T@4yRA0Wa)o$R;k#A(1g2pDcs7LQi
z*AE;V(4f3#x;#SF$57f}qO6iVPxf<9GW8a&ta?_R}#<4v-bZ_)Mp>hk~}jh<38AiVOEhlEoe<)D{aVYQP0`!5fNqFZ$X64r#sS#
zO2lUJltRXYxJZ$+uw`fP932jdhpjR+S0dfO;1=f6~Eao=jP<(upQD+`$t2_ibpmmX`{jNI?$Dk-n&a?l-nkW#40}@u7to)7bWzXGk1dEOS`DQjJ
znflsM=+C9`E9;Jqu(C-fkGYeYeF_Pd5x`egY1y)ItLj3QPnkPHdC_OqDYm5^R-f4+
zwAx`?MY)UftjkZ?*{7*pC9=>UaM#Q6ECF{IY{b!s$YBX}MKxwPXWlKZ>>e(5NH^?z
z7=KsKT|&3>ckUAolakWXwRLG_Awz+Z1?ABo`HRFeT)iJp^2VMOMXKv;XSB-5pJ0%)
z{c55Pk7-FhO%@Fv$YN?%{W7F3RHCAOA@;tc(CS{Fd&Ng*f@Pj*&?l>vzTd!@ox^^=
zNb}^q&&!&LQft2-it9Z$p4G9I@h5mVw$To$+maRV`zQf;xQ5c%FTO}(VAL(d`EsnW
zP29GFgH6ua%z2Ts)wqaJxsh(?QP;kxHyxtzObTS4hC%h&RgGoujfnE#^uNyGW-4{T
zrM30(@!y=d7CD-hy?rHL{ah<6g!ypFi93a-Bz^Yy6>zb^e%4xr5bejQd!OjW-q?05
z(7Vc|c4H6Xur4GW^U#8WI5ib2;NpNL6!6`-K^^(;8ApzSlET9Wf;)5n_PHmrNmuGE
zZD2wfg{@0$Ulr&nkOzNI@g`iSK7bF6*h0NGfnf{|ji8KAj}b+yYA4d`{WmhTrD{Pf
z(^cPUtl{R(ZuT}2U&#=vn|ZB4qSh>FKgWkwfr0Qxoh~D2q&*TQYffMdh9SqT>m2F%
zkIx09t$Bc)Kh8}c28HgvSH1)O`I&4P{j3iN%2Az!0`()@f!}fy@%z_;YXpD58Kpdz
z#b3P!Sr5&{%fp?+vYtjM_?*uGd)z|Dzmlv0K)6|-F9Nwk+-Zb_&(7w4an|YLiKl`8
ze0e@Zrydjiw@qhA`2L4@^#s0hB+F{3X-TZ{@+g@0jEwS$Q~~CauZ!v?L8vYh$|bX=
zw3s0{j-^KAZuN&>mn*$^&n|<-N^iV&YSznU1qP2D_FwMaQkoEz0}myD9;b`&Ehua)fpE4x_tHBUhlni6+eJ0*u3$sX3-!CZ$vExcXW)O{AU4VSxSBi`
z(5%|mQxb8O6cYH!MoDQM+ilM&_~7A0jqh)>e^bd);U2_
zS`M8$wE9uOxX>^#7WsX^_Ux73D-Z~`)3S%dAkCq_SB6%rZQx}06*p235E4lDm_X%`
zto;s1c3fj+ZS&0=*RJ2V#bH!<(%`Asb(zGHz8{o4rEffRkfK`C`bsP<=wj=%>1rSF6{6(61
zX%oMTO?(Ewkr&1+SDMj7*s%G?vJ^OeaD%{*UbA#`QlYy|JNx={hCfoRqjLcg=xW+k
zYq=@a?kWPChn$x_d9PL!aS$B{M-9UT$G~MqWeIFryW_~$aRiQ5=hP?9gGyHzj3S7@~P$Jg^rTt6EFXXNyA~bMJjUQYsx@K1*iD5ZsB@uQ&
zBu=Q{W7ERI737=aL?8GC`l6SLtnu^4e%nX2OZ8tVV_1Fsz1y98UK>tJY9&U;QZX+G
z9rrCPZ<0X~W@ay+y66R&=}q!}t+JHz=a=JwW}z24TE!)Z%Mnx-SH
zd06l}Vtxb&gC9fVOZhr4^J^;NQX-z?ze*s>v*`#EvU9CkzeCgFgZI=;i*s(Pt3b3Hhu
zHA6&Vzo)gjt-bwj>I3?ix4~@?=G420snosav6h^wWBlMkpF>b#JB-tWiU_;u-nX81
z*S
zNKFS!M>f_6GX<}*1P1;+r}BxFe)ix$aa>WYxjC#0m0%tuXs%XP7@9vei|!xeAVfaV
z_z&5{vhBWtqwuKR^3-8)CDtHdIYRl^6_OczB76R&v
zh6sq)ktPU48%gbqC^2cwmGRx^_~Zm{@m>D$DG!lr)9}xpgOXD26&~kNlZC?}{up)G
z0I|Q_#wMm^_mEpbuT170%HD*`w1oPyq|5GIKl&Nq2^{l>2Qq=aik#_Y}p{?N#_mTwY$Fxw?=
zQ)FUlK;kvrp8A-!@O%1tQ}ISlz&ubn!SdH8iayd^dwwO_qAH+Qt+(tQ#IK{y3*VcS
z>5uuol5!<_RyO#&pHu42u%~>bwLFX01L>NVE6M)FmG0>r;{T)!si^#Q~hTS0Rqui%OCZHKMXT4Gr_i2#WLl0DY=BI!Q`+v3u
z?Elch>vT=4X$$drXJ?gpQUR9Vlf5@O4*pxM$V3;sBVIIqTktPZ_;sf^4Mgj~?3d;E
z%H*Wa3Yc~CJcOi4i4+?=UL}NlRwOr<&U~4Q(B#7Cs&`6|w@ph;-Of1sz4L8yD8_L9
zCK;skQrWf!*dnj&b>Xon0z$+^B1?Li)ZW-QtnsJ?Q%fKQw}2*l@?USnE@RJH{v8kS
z^*P)OQ?|uTJXGY3GHdm-#)}&IWvNSxKHwKL+=h0LHnYtG7OXl=zs}~7lY)1~%55WX
zo6&KuSCE9GU55_#i%D)EWjG?9E2IE}_Ry2D+r1?pIuA3Mt#w7ERY+5bjkz_&nf~aK
z!EmA13ur%vqT_Xsb~qJ$>d#Bnd3D*C@9gHK`D6BqSaov6&fH%IPv(J7y9aDhB6tEs
zIR#-8bkx1?X(`#z(qdSKMAd8p$eB|nxi)}w0ucxl$5<
zhosbj)FFG@Yzc1nkpfvD!Z#cv=_87^;+35^}6L_9I;{kw@
zqaG9+N$|fxePrk^fkvC}QzcZ*H^Sk)m^MDX9k;Bafu*3m9qA=vyKbTmklR1HaxmOx
z+}+r|p86Ll=z*k={r6J!ivrot!OYHXd@ddW)ROLc
zCF-bv7X<>j?iU#FF}o`pIx!k9bvISw{ngAvG^?74ccB0HxqI8KSNpK|_M?HQebsZb
zTG-FG8HY?0PT_>ei1${)sJoq+U|`sEdo0Z^=nzs*Q=R;DKlYZ&%-q~v==k?txh9aS
z9>A}h173!Lf^qz24LBB~;mf;g_8cX5&CzIDf~ApwKqx;f4e$Ih60?
z>ERyoN@o4k6ud#1SZC3_(A+y$qCOCdWhD;$%Rsn@!`10U))uT(SG9SFwq|SPa-%z`
zm{m7;&_Rrq^;xw1gOs6|8y$`oMIo}wz%H_}tw;$V<|YeYOvq@)@|nIldvwz=1f*d9
zpYu7Pu5v`^S4hH5K~fJo+@~I|y2o?co2@M1wc0=ZQ(0BnMf@eS=M(9;?asn*@|$w?
z1~nYfb%5VRud11_4SS9P0Lnrl?%}z@vjQOAHzEjX&?Rf_%Dq*L=w3dVgJ&W1Sn1bV-
z(%EYYmf~C)kH^C8<59tTRj%ute^^dE6w4EW{U(-l1u;Rxg=JA3Jhd4Aw6e~*XWQ{>
zgYz4APh`eO9v!>+e$}pGd$Z*ck?ABLh8ES@D#My;W@#RdTc5WLKMP6AP%~J!S(H1f
zf)9{4!wy2;%edXfqF)yx`2PX#bn23-9n1`>>{@w6~`6yz{jT3d7o^}2K0
zV5J?PoowayD)N02JyHYbZ&p|dpZ|(91%Elz0Z{vX)|^jS%N))OKl`uX+Rv9bf|jB4
z*|OpKa(Tw#$itEk<}Cbsk(mf(+?qpM$GWxxs2i5{{ehIS2B16uTv>v
zfMQ=m<8hkcl4MAJx9_crX|M3}DrZl6YP2H&AYW8~ZCV``KQvj=A-=#7B1b1aiLM;}
zxS1#1u_tLm4z8}5S3E<4+l^bRp0CC(DLVZI3eEs>=n
zWRzGQZt>cy-?%I7lb>cRX%GRVSb*sPt&Md7Mcq6{;Lov7DXtj}!03=}O&PJ-B_*M8
zTkn)Q<&M$%PeO{)6$4yQ6RX#pZ?Y=|pH0oC`j%yg*8}zH2QAIYHIth+10s}c^gr2k
zwl{H#HYUbG+@po2P=H(gp(>K#>ow4`nZd8&WQ#^Auf4BuW^C_wjC<0wg^{nvt3B*7sa{wIe9z(tn?vYoDCtl(VR6&aW-452QNYA(KqSL7=C9
zhVWehyKoenwg5|YdrMXlQI=m{y2ib&bnj229v{%C4rkN{*t!OP)3dMKCCP@uHi)5-
zp&_`)13$moK<@zRYd2jM>s^6*3)suRiG07q^Ia8aVbpn`?9))
zH+)o4dDPMeRoYFbPAfW5skDl0w5SW1OqjtyYOE3CiES|PLRhD8P5&n&Jb%S*nD~Kr
zX?LbQOnR-`{#xEJX+5o^#Lo={OBHusCkWA`S7nP6{cSl#tRqD_NOc9Bq+RJ;@q>7y
z*#y+a(<*aQz=MD4On#o=1Sq>qbJJt3N`~oNte2<7QwXGecft4Z`9QeZMp|Ji4fmDf
zPu0OwZpT!%q}0!;6BX{UcBBwS1}4xF!}*E2?{fHY=DV?%ixyBJGe-KKxWUd^{upZ
z4U@Rx
zEa;gdsLZXC)O9q_v~<0vj@|WxwLkedvmB~wZJO-n1EHkV%~b|=W}AkT0Zm~rwr=Pg
zx3pqaTahRLrt`H}2Ln2N`=r*y-n0vsYDBwfyMYc~yOI
zz09X(MV)4WiwGzfBic07&5VrVEfNJiYhlfBibvx~CGU
z6t?rM&1$K^Jr-FvKQSRrNf}nu60ocIAZiO3_>m7_=cvgc5yfM@jFYOOm>xXr13Wa#TmBMp4?BH|4nq5w~@Q_;5V5DWVn=t-)g%h)Ef8AcgvsJyHRQB<4R>
z=6d=%2^_bjVT~`J@np_4<>&;R{ftm7O#c1zjV%)gXpP|}*`
zqU1b~&LU2I_nTW!uN7Pg4Q?HBs2BLNnonI_XJbK~|6HbHSv$uELcwIH@)8m13LM*A
z<_!|4S3C0K^{x)znQMAIjUN0c+8=@&9(j{}dSJ@lmi;9RmKQj{m)KK*9j4T!Y7
z4pOqjkuIVdlNY*5$-g0hND{!!ef;$KlwYvs|G#jaQqF5h$kzW^IlAQlm%BXEqW_}>
zpga7PLc4tqIfvTzhqnjbQrVpeeH>DTbPL2N-n~PAi-rE5wB5PT!FhN=cm<_%iH={DY>@8G53igA_)$tl6SpQXR1V
zl5^z@r|>Tjvw2=#!lT5SoZ@vVX}g$R5i3n-5dY#20&jqZZRgETzE^ZkHOj)I{AJbi34x>ji-=*)0q+^Rrh@@iwC!uL`BL
z-#2Ixry~ggiHnRlGShNNv2BD8>^^Bq6>|fFQkCAVD}h)hLGy$!?3{)1zj3du`%;<_
z-n$f=X}B(3_;&s*-iS!o)Nc)dv^VnV_U**pWfa6cR*IpEf$b+JBir2;+*s#o4BVmK
z@HxL}wGH@nkBfD5fZJdc3;Jfo-|Z
zyNmG@kLP$rw;Ja1>$Cl}62uopqWY)9r6&T(7=T%wKi*=j%R>FJZMV(md
zDihW_^uJFj12b&LXUFwhtjJ5_-dY3{@L`ql2ub^W5(_9x-qsEi11
zxzkO0U}HfXN)g*@=mx$!Da`|Y(${D*Wl3eQ;;2V;szxp3m8n!{0n5?XS?T-nZ8KH&
z^ZKfU);2jyOY=P47sOz)LA(u^S^2^`Tv2IhD~{P|9dm|J>B{+%JA#qMPmvkljHC3s
z`zps%5IL>RlW%82+ly6GP_GBmu$CJ>%V7&KW0)kVYnzN-L;;cYRan2|ISaK`UD5^9)xRI&<;J
zrntyC{d}^~+i7{M8H|hln*ja&gHl@1c2uI&a9zKmvPOGZWYsO;vHR#;zlPmGc2$i1?Cl#ai0
zV6n&GDG*Tt2sSiF>Djk?%jYJ5^2D@eT}FQCOC{_`*Bqle#S$n9SO&`$@48F7YV{>&
zuE~QDyk%x}*8S^O@=^=X3&b+^+ppwkLFv1dX*t=>9p;(Z(>2bUKMGU9=~a_%O~y+2
zS0HD>MXxH`nKtW+jU%+a=3em3_IRkz4jbv2X!7r?PE@MX8nh@UqF7*szqIizD&hZ
z!^X(w;^^2E(i@Ow;OOkUvxB+K%pn(|0ac_*ARho?7^cadNJ>OeF=(*~g&Ob$s)Gp&
zW0OZZMFz_IF!`Lh=Ib;!{d|4fA{3n`6BGlQnW@!4TUwoA!(#{H@6Oblr{4NiN5y+T
z4M7B}>xVL+FMAtSZ5t-bM`mzdWnh3ofGYE`j1
zRV=&mnKmr?hUKcy!2u~eEH`wQ%#l+eZ3C=>gx%DwOl`&%+|Tip_Z(O+AXR^KWt2Qz
z1zj&U4w(9gOKY3jeKY;@p|P1IA_!k*TxS`$Cx3uD@RyRJ26OI_JKLvtuZK&@1W$-K
zlTL6SieL2be(c(Bj4OyF`6lW{Y_5W!=iw_yu8Bs|mG3QU#GL35Np5B4_a(`5W!TNp
zA2*osF%o*~ncOKuHoQFGbE!ReGO$=#dw+ww7LKPx!N3PBH7Vi8N;wJjBUW?m`(ryOmu3Aupo@qVg-KlN4Z1Lu_jfkg8?
zr{AZaTq=)h@Wrt!jdvQ#SAS!@oxlP#Q9LdYRXp<{=0JkbuPpleJ_`gvW
z>TJCXR8%je@H{+BzSRtA{BbbN9eKw5+rEuW{&h{X$G;n!Hd^jcd{_Bx%R-UwEvPSm
z%8~2h7q!E+tsO0VA>5>@Wt;X17PmcrJ1*4U;)UuF$?xjDM3HaepqWj|rKUb_(xVPnRQBb(O10=Tj`hXk_0jaBKi2G2OF?w?1
zd9SB{l9IHzXwA;HEiaevZRp-48y(FgCZ3oppBIEqR;x&Z?RibE6pRP9%^u#Sq>xa$
zQ0T^M+nJ*qd1y@XWCS`rm|5h$s^f%5zA>1X9J8~$d@I)AYtp}GSr-T@GvJT9>gQ`I
zu|DL&2_+=ZP`ugZ0z|?t+SN=9Is{B?uPamZttBsEL?RoqD!74gle#v{)c3Hd$x$CaA6?7*>fp7jI)jQr&RV>!+?9>vZJS?
z@i!x-_MeGUyF35ga_?e{Y#V#a-0`?^o_6#Rq~CG~FLJ$~!}UxTt=qKNAnJf
z0gg*d*=TjlWy`pin;0)r8C_dnpUOK(s2`B{
zC>Czf-B}PUj=uG3=o2N1nr26yje?^5F(Aht8}rmw;E#IU4Dfd!EtTI~S*yk_M%@yK
zce3uOBP3j=cq5PmNVFyVAP62Bt~s?R!OF^Qc}5E9zNo06w)U%BCTz+E%XL7{moIw0
zA_OhGuPCj4^)@@b5%6|vv^MV!@>}$+d*rYWngwNhfVB8g%*AA$Xu(I)8UI>Pym(s7
zJ<7A_TRZ~meLJX&|5JSY;~`@Qnp%aI`9dMUK;CfC@;SS%goqa8{YAkd@u#yFWhPoQ
z)7Q@~NhmZ^M>pz~8z2K8Qc&Dg{eMbl{zn{6@#eC?u!vmv?r_tvyDX|c`j$<^k|?{y
z>EA)9;*p786Mf1eNRiB=AAd*3t3dCI$b*q*$o7nB>YdQsFJ{^C+w#DzWOk~;^|$s!
z;$@<-`*G!wAZvzKa=QGH+j56z!#vv?ezD1VlM%@H+r=vZp0lFG5vxGj+EBT$rmtKe
z;S2>DQS`m{ykL4O1E_IxRYMhsqvFEYQAzi<#zH^x!es&vnTt%>e>5rb-nv~MnvfG&
z6+Fq=-fu70Sc*lG)8OXqNcJ3d_jGdU3yR{_EN@424ZO%vM7c&_lGC3Z_`<*=CXR?p
z6yLwpPc+;~%#|7hj`{$_bM>)zjq+KsW|0`Gd79k0^pb9ey!5iV9~j=lYk^=Ow?-_H
zZ79`n?sM&BCKaT>!zCfXX3ceHI)mn_IVG2~#|<7lD|$WnLK-{$uM==p?^ux%8!0V#
z;6o5NZwRr(CnW98YJCww6b%=y_eNG0BBw~iimUS7Y_6|Q)(p9h6;2tF5?Q|2snDhT
z^#o1ZW>r1z5_M~bu`)Dd!_Z(Q3yNayu>9Jwd$vkUbS`#GPb;%pwEku(9q+ZidX{5RtE}KV;~JTcZx2lUs;yiTI-HFs3c<7+!yzZVirKjI8gmna@^LqiuL3v>?;PDm%k@;>#?G-DK>JyCTZVve
z$3*|h_{6e_2E6&CIkNvmTC0H@%PuTbXTOb}4(t`6Oi6|Ur`0+~q
z@BDdA1esmB{05u!&phyEjZ)niPDmL+Kx2+*%={E6O?B~4}&
z-qwxLWoZWwT;fO7y3TG4*k%i~l=s_OZ9jP9f4=bL!RE0@aUkc^3k&R6!{TY|0Bk)?
z%}jmY%yRiId;ikX=ybP^UBPdflS7)5otcsXbT}Yh(|$@=)zR0hd;uvI7N+YfN?Tf>
z$=AFYAm%J@p476?Z(*`rmw$V(E&cFhDll1xS4*UXyv!ZhPy5K8$i2rZ>fA4_@(xI@
zo%#pMLR?pj1dwf$n?>v2YagTkvY7~f9mr4OiqeqFT&OpMA3A$YUB9}ILZ-skt*QK8
zyfFW^Txn6IBkQkYAuRkbVg;Mw4@jC@y`7)hMd%ay{8n2`w*Z>L|Mna3yYty7`m!Hz
zgdw2A-0Cmu^xXeDnySyw#hVNN?bfT~f1BLNHk))m*%$81i1F6XzY!j<%FddxZWT{s
zbn_LHfZg#l7lrP;$!hRUnw1?~_^Yat;h3G;i)Ml|y|Pdna_lmjunHqNr!vo`=>W*F
zy>jiI!1s1j!M=AoQZFd+_n!5Mi8yvCtydkzWfW>(`2D@%38
zV!EN2>b?BidZSP|oy?<}gEM_&8%F33MZ+h{Yk99L2CJons2+r68)e;yz5LS@;s_HS
zJF6=?%ER;pKRbIt@kqHz?Y@lxkBtGTv8&bBu+P_icV7L#lyc!7&;CMo;^<&kvQU)X
z1NxeX6Q3G8#gQ(CP%6l!0wQ_?!Y<|Q;)wVxBQpgDL
zI9>GX&hy2jXI&9wkzl>cG6wQnrf$Km@3<0lkopt}!Z+KqOvS6GLKP<1hJ4e*gAZQz
zd{R_L@L9K}CZ~r;8CRLma7~MRz$h2nR_F-5NTg$|d|(O*)JK!od3Y|LRZ|Y@7BDgo
zZGT+*)r#-4^JE}#G|;&AIo3P=YPHBO^5)4C5`+nL>~j`2bXFQieREA}s(~yZKXrS(
zwa|BOYKxwWW8Svshlytxu~f|js>$LF*9S+NK}$PZ+u!L#Z>hXnB_==*r-&0%yWYs@|*^O$4+s
zM_21b8$Fx%s%vVe3n&O4U)BAY}f@!;pcb5GhGg-4YSqNpoi^iXWEENn^
zh2;Aickgm{YD1F9TloV;>uV{_&%uwcdI!Bg7w^Tz9eSNrH~1!BZZbN32D1*U+Ref1
zQk61PsnM^y)|8YRCRT_g8(YN7fS=;$#bG9q9xE~U(r&5{h&oW}C=>${rn$h}p!04fUimf|Ag%8I
znw>frxta6m6oLaMc|`}|&^XTE^_8*GTVIjIB{oVd;8*YiAr2)DacF3Tg}kx)rRz}V
znJ+ESPt%0oMY_D&ofR)KOjLN~12=kL%ccKn(I|Q=|b~F8kR`rHXX1
zhU~%TzZbJl*p>sW+AldwH_ifrX8I3I%3(Gk0Zzk|1=Au6|BRUU${rsKh=2u<-rj+u
z@KI@(fYZ+26OZ@GXM4A~etca7lvNQ+`6?}Mtt%kv{`B9+AXEdOMWzc7^sTY=0>&P0
zPCF~$XYul=zADSsuV;)5%~I9`e<^+$v(j%?7~4sj2|8nytIoQ?=X|@|a{G{*rK-Y9
z2R5{`Ev&AP&2d5m@q6y(J2T<7V?X57R}xod*a=ZSCGZHey^J`CBmB@rpSX!&&U
zTPXHW-MWmSr`}xwOInvVZ|*}zeFjqnt|T=7Epn#!kK*A3vIunR||(A`)Xfse{JpF3<6U3bi!=v(AzH=g7bx(Ac~W>9t$E9b|B{+83}
z3D*(g&Wg@c3UE44pqzkE4xHdKWC33~~1EMdDpb-(?3sh!#!
zZ7LP=yt6@4xtxyDCgw?V4DM+^9j2=cS5bq95>iap#wAx=|wicvvl
zW^9CeTv6V60Fo%7d?~Agc{nf8qE~h2W_A5Qgpc>(YG4izz%X7*?@#MctkJtV&Ohh0
z5jhID5utw71Sjtk7l2zC=SiclWeO^3G3*ITL
zT@SP_7>Lx4w+VQ=(ct(@LUrfLUk59zD^;Z@UB0}I<>qU4Ckh->gm;3?u*P3SC#vn?MtCOJT67b9{9aAG$nR1V
zo8nsO5EC_)1ZfQ^c4E#HTf?BPFCp3J!~>tW#x^EnK9O=i9%}cM9WTc{13$=Lf9v_8
zXaEl6Z>?HqyE2IZ&+`Ec=F3H1YsjUYDakXiRx0>lYc=6r8DBvQ-C>bVuw6AVD7J1b
zc$&4EUZ?Xm=CLqSV!U7K(9`Fc0a$_RdC<7nRJ#TKpCV1G_HR04TJI=aYB_9vTPD^h
z6CB`#Lcz>qb}jp&he!@H{d*(caI=!fs{gdy3FiQUE2`cILfT9Q7@?+TgaYsRfXat8
z8iG-GQ7NHyZ(_a$zw=MLYsvLv`*dRWuYS|^=e%^Jd6P#>S191G<-}K0gz6T%&T0ox
zoSjS%Ub4yulZvXne3q0+NE**&3$CZc@i61RZbVN^e~bSgEdaRD-$9y{>qp&-qGxSk
zC6Zo+$}BCIfmFc$q2`+|gNgyY#wfhImK-1$eJenx{&xa^U|5n)xILq9u{3Ec4DGe|$JYUU
z0N_*Qoyl!#_k{anNfNaBL2a;_4Yz5|hY$#pwDaPWsOHMbLufAIh3K0iyzfB)kLG&+
zj}&(u4#9_lY1AS%(38b#&t=Tq26{`T)-`UtYVIh`&1*8K__%Xql+*Yc*S{757u%D>
zeey_UPRH71Q%SxS{`tgT8z4@?Pn&eLt1GO}L$11*If&h!?Nhtzz5iLWpnA_m
zkH$($`c*~)$jV5x>F+TL$!ke8T$*WfTBcK9yUx-X+MdlRmcRno4Es4Gj{Eg9wLAP1
z?KMhATBvqpTKk`yTktxf98{b(zjGFh>CN!dt7bK^O;i?H6v!rpM6B-@ROqk`4Z_ow
zgaicRUMMhU2OX?4#1WoKu}?g7GK(`=(iuHw_b0(e+JQ_yk_h0f$W=OFCY4fHqb%Aj
z@nr-`(gg5^x_^^d&tJ&R9xmS>``IeLeEM>O-c@x+{&R?*qHV)Yl-SA3S*)QWY+HNf
z6%W&%;!l}s$RgI)|E`VdAwdmAL~K7O`oEg3>m4$!FAUT&(&VQV3r8j=blcfmG&3XXtDqI`
z;p)~PO&ZYk#GbI0$CPVZ5vzgL`d!lnU6D`XKapL2_%YovaZr8}Gtf`y-$NO!=g9oD
zoije3E^uVMDUewFKyqE~`;d)^o=2r+<=U(1NFDojZ*^75COhw4Q_yHyy7F1L2?Xo8
zBmXU%#m6J?VVm|e??0_C9{;YOjL8{=y;JnRCnd@Sc=}PbMZtS$(j73@dVCY0mLc^w
zdWcv16CZ$<2?>M%!wRo3K^Q*xri8-uIqANB+TwfY&ciFqH2|^nysL64qS0esbbX}(
zcCaUPt(Il3+bKwW-mt9PG(xzv^0r{x>B|q3rNV1U6g2dhRVK_T&MNOMQ$r0%L#FHC
z$2f@zf!>Ig&B@$uKXhXoUX46y6io5pNedNSdvlOLg7VXUrO#lbnx_#SGXfwi;
z;_=AEU-OuXvfxfAejv?e^3-
z2Oc-orHAjg8lFqV%j5Qk1oJ$to2;*{{K9s;-unwpi_!vHlPA@oSGoS`{R=#M8fkQx
zShGPQEvj%uEogQ*oGSzM%as?vP2qief(Sm_#-;|>BtN|dKI!UyH&(g61t32!ZEvQbXd_wTcR7eYiyj_f{OrEu`__&W%Y$Of>?8a!0
zQlQX|#S@#i<=U97Uw2s;CVVv#?NVYM&?7(Nw{EViZ%LGempsSFuhTPOG?eTg`FpvY
z9CMy8?yo}SKg%&u=xJS?t|0XciWgH#7lLX%=IiP^?)A<~?|M2~X9>jk)iTeF_K%Ow
zkhUY|n2VKnJso`W0K0g2t>){Ir+Ib7$9sw*pPgPS?q*pSEh+c;X+6|
zBvltYU0PVm
ztM``~iMkEto7l&x%m@wxD7(C2;@EU96+~deY41_7@t@qP6!0sdp~RG3xt(kOsh4-%
zQMH6Wwx^fK?%@&g>}kB$Y`{}(cRouwI*OM97nFZFy0~i5ueGvt>e0>$_Ws_YfoN;w
z3k0JS^(5IIy*#~<1EofuFG{`w2@reDPUB#!u5U=-{PF
zBG;m^fbp+!af9dC)iD_h(fDT-8&v?;>w^n`W_cS63~R&ZYJ*l=`RzY?kidKA`CxC3
z|BtJ;4vK4QzCb6C02cy;1PLD8-95qGU4sXAhnXZm2*HB8y9aj$ch}$$bg;pl;ho(3
z{i@!3)KoG5K<%?n@7>*Nt?tGp+j_Ge@58|K_-Fep-tHG30pG48a*I`gWqw*Shoj}W
z=je*C)5x5u10bkR;@TuO0(Y)st+Zp@{2x;MBT=$St=qct!v9^*%5?}qI
zdu3{(!SEIEw=3z(X<_I;l*xpBcqydNT<(4+TSChluVHeu$CIRC#ct0)9$)?*aP_{z
za?F#sYbW!i%DNo4+MH$$)h40AB^k!6Of_^05_`)vCAZ_{nb&{oi=RG1GC^QJG5F5b23_YbASGKR~X!@+8)<3Y)632D6+
z#P*;<-+D!>)B|4L*zv6B9iyLa
zwd|a>lBUe8QB`^x^NlYfeg0*=F+)v&5;$4q74n%0+gJ<}`SbjEm#j5P;Kt-)?t`)w
zb83lG9yZA6&T~$`M9Wb3C1?S*5KnRqTd{Wa8T_8oxrwUIw+s5{Xzu7}UXhTidA#sQ
z@B>>*7$u5aHUTGl^3xlF@D~4vACk<^K4;yJ?`RelHqV@WXEZiujq*DmDfiPM>uHa`
zv%nZ|WRR=Eqs~^1|K-jqj+VV>r%uiXJlO2FAC`8cBeOMoAK6UGNfXhpM|SIe+1WzE
zTNmrz!J@Wq;+992fmJ{2C~h)8U~PY5h5>2xZH_bf6eykBROg;cwtspl
zYnC(8=1$1)kB#P1uGTr@X4!%oV`4&_a@~>9QE@$%PXA0-kRsQh>>vQFm0WA;tW4{Z
zsl^YMs?vj#>p1t0r&W4Y4Rx6l2Vt|Mtif>~VTM7k#CfJ?L|rI@UX>&e#g%IjxFO#`
z#P$t{csuXk!#(rud|JV$w1;|cLEg1z@2*FHa+!zT)Dr?47mWx?sA=zdYEW2(0xU=fyHu2i`yVp}twlaoUw6B%2dQE@yl**%M6
zQyvu3=5xXSv-bY-$ic?481{W)x0Kh?Znj8nM-qfgTpecX#ViVR@I^*yz2M@tEge>bUx9irjR=spw~Gn*sOli~cHz@^^If
zXC2EU79AZ3rL*suEFSUYQd(!WyB?btN}xtBhR^mklSAo>Dc?O_q8CbFswdu@wlDYf#vQcJm9uR3-l8=43gH|HMTG|GephB!$ra9
zauW1qUml{nkZ9%9@Kk?}h(~2+NigRMsagxKcd0#IT#M2SQBoO8nuK_AvCWUnl-(3P
zpUTY574ctG1*x`KKlW==Xt7q77BbC3MjId(Z)aHe44ii*ng}(W{xh<(6F1f=;TI8B
z=H@HQ-7CGlHcOd8Jfv9SN-}`*8Q64$w|tlkQxtZ@4!PI4I^4zjQJ6|4iQIYnna^7S
zLIMK9!c_^-X9WyvA#0)PU2!!Ey`!A>^pxYQx;!dLRNklT&q0ztFY-R@?ZcSYsz*i^
z%bGw0KvN`Y2N*6Tlpn!Olf4aYK~9!
z-VwMsv@rgf5{tnVY3$(h&s|;Om<3|bkxZSPW#wIe=u%GZo{I=CryHdWUqs7NPpWaa
zxSS$otHx!Ho7E^ODGImgC#C9~xaiTwzCaO;i2O0Pr|32fPHP2H7*Rbvd0AP7K0degymRS-UU{D0m;0AJ
zJr-)g@$IFbt17qYHTcK7GG3V`+w&OTq1weGF#N#ujZn)lFjI=H}V^UD|!)vpENWR-x>EoskX9cYEVn-Qr;I1m7ZT
zpYya`paAaqlx(>?OPyAU2&oC7!8}ZHkgia~?)HHC1|Fu7si~>glW5-2?!3e>0k0*-qMeSh@+Ia=~czlEnso~f1hTRB#&u^DY08>{1S^6>!`i4>fA
z3sY}_rcF?T`TXJb%~SdQQCd10wp&LZP4}0x);9y$a|!swddJ`N5JvsBoa0RnD!hEo}Q5Kn#IK4`y+nk5#Xfvk5}`{Zbf
z1;W^2!}5QvX(~)5jcL&6%qnMkxYz`r8JzCz?HwX*_B^U~zxBGiyR%?f5~$e;`PTj%
zL`s?ti6rOd;(GC!bjgcc)IILv=`rfb~F9_uP5vQ`;F5uzYoZG^p
z?>RfI>q&+K=$Fg>{3_NJV=EGcCPdua47$>S4H{FrFNl>`sKg{{L|52VpV1QZn(uBA
zGZY-&byikPnOxk7eG2XUCW|#TjQV+_v~iA1X~T_FTuII>X=^L$7R2ttG{1@pksxLw
zdHf>krC#hl*#*xO@l!(-H{ign6z{F>O$>xZLCiH%*kzt|_y*GMjJTzRg#z2}6!431Po%w-+Iiq!#RZ_Pl;GdpJizwRLq>
zyzJarlb>vgZSJo~Tfs-PAYt$YH6!EV;2;i2`N8kUP=Kzk{z%ekT?X0p@Z_#tQ|ct==9pa#|J^LVAt)(1B`rVGaret*Q06|q3|^}Of1;}k;0XWxs&G4t$M
z#L;*#J#+;56sUcPOgM2hsaeSaoUfx#H6GIpOMOYj(I_svFHrB6)fS!;Mbv{giDXbw
zL7!%uEp6p(RVTQr!+VD(5?KNQE-o6+2}TA-M=}5LNluB;*Hxw0pdX;d{bRYu6oY8=
zsBw>m*k%HoNX+GHW@z8asFp6`_r><9et);ZsO6_;i>HHh1lfne=~BF=vkV{qRg;zm
z7|i9_`#3g1@S#by2(94U#Kh;BKbBy6MCat3r;Eq!o@;uGBvBu29}`$_>?1p9eYg@u
z1dJJAMs5^E*Kcxfr===z9q%)xiBj9NS>slJ%
za!WHaK|=wrs5e#12jWdu+d{+!13;halx%zkzJ5j0Lh^fJjj6@JKrd8ImJ*3i(60Ug
z2Dj5Qa7@mPB?ud~ZY}9#S8Awh6lY9ZDZ03IkNeLCTH4`=7iAQex*zACRO3O=Y5r7&
zTpbdN6i4}m`3m3xrcQGb%XwE8D*0jtJqv|grH-AOo<%h=kqzl{d1^zf4-F`5bkft)
z_0K0e0$luW!NIW+uZv%Te*E}R1QZ{2%G@)bpJ<$&OKECaS>dq>nE)%-(@)ZH;4Q8F
z8g8g|$v80dB~&u!`}YPs&o^l2MZAfnOD!sufv8xqA&Rta9iPEkWN0|L_4pJ)+!eg}
zZs%cP$T_QtYt~hog4>yoe$q;Z@a&zb`Tqq)7kbmPvp}k_l_0vi`Qk&3n`==$nT`%?
zqDi}dgfMplyO^^xcIG(p=ZT+*T-N@Y>5>KpshwG|FJ+a-WbQ{s@rqvKC6+2k0o~1v
zhX;mRRRy*?i+1iDhEVIOs*YC*b%IwE6~l`?-4#cwAo6y{viVaUc60O91uC&2|L*0p
zk`J)u#KBOhDRg<4XPP^kR-D_&2U{M79Br?52=HU#%BE{Q62Xzb#d>Z*3
zUAIgeJLvA}8Xg{w^f~AzsPVVA(0z;^@w01kwUrbex6$$8!h#TQU*Dh0s32iB9q(Z2
zTmgPT>Gr7SpY!szlJ;~_W&Ai9Xy3ih&sQOQ`OS_i5x8Lo@?t*UW54LiA->>KHt+3f!<>>Ou*|n^ox3
z`eE|937AJVo(im;V!NOp^vc#ZB{_wUizjow&N?{XZLJ_5kpUFIl-v1kBY;+5gWGFq
zcQULx;TH}XCSRz6Caf{1$z{*~Y`%$!jd_-(%Ur;_v$ds)C*2y*%1?r2lPTsGimT<~
z?yM^ENHH>e?{*N$Nvxz8E)zk<;rtP*l!~B+h0=s2j;C;~bi9Asxm=o=bg(aL3uwhd
z7f2nY^*U1t%z#3!SLepA5N)U-*yK!*#*DV+Xp%4D*}4xaXE3e;=gUTdF{2+5p&A_P
zY*3O$$0L*}#BJePUj*^?QVC6jbXfQg#Pv;aV92#AKM5X{&gu6d?>pgYeHl%Qi#ES!
zb9377bM^G}KiSz~6U{hnek;%WI&vKbNfNRCmKz%=o-L~=?|Uk|HMDKlCoMg*9tngJ
z(a$l{mDd_?uaWPggne(`g6i#8kC#gF%gZAeWy(H0M4%;#7tm;3qD$W$lp|ffXz_AfA3RrM5S>si{Y=J
z+9(pC^)20Vu^@}=ACSll`kKjwULU|!Nqh_Nxi)@(680+QyWZ8K3gDEO=di`V;~yuU
z?X9%jo3#0+FW;)X6^nOg=j3E&yxy?t`JTNyW~?Zu{0uP0JUp>V>ZM!%jQ8&}Y1Y34
zq6mAR+-wBOSa3wQ`C)ggB3s@Sk@(d4+*u|z%aH9ZHXMlAL^
z5JV9;*(n{^b9-+67My$zh=AX}Ds`E)lM4+EjS!19jiyC|Hy!BdqcnR2oHrEl>9KbW*QZf{l6?eFcy`2dmnnkKpbp3y;!v=ZRf`LHqq3|YOy}R4)h8whzVjKq5V%)O+&iqxgCg|lUKjhn*w&b
zqtvsya<3&|rlC%)z3jtaTrUQl&N*~}phYdSYK{ds*M34|9P-3AV$TsD-bg!n6F7_n
zybDszm5|?cBp3Bm#URIPMkefSI{X6*tCTq4uSJo0S9T+m{rx&Rb_blA5v>Qu$!0th
z^K@NWeFXML?9$X8O*{f467fD|zM!1VAk0V(RU-c@1Ck`;Ay
z<`ddi1q7OA)coV7Fo81|f(6I$e~n8@npOXk{f$I^SI*P`A=Mo4n}gWUb?C86FXt&VO^`
z^3l*ftx>luYckGm;+Jlj)6Q6$u%-W}f#IN=o}53FqESv3_7?Du*5>9)carT^d$m4
z*lc|BGsU`Q;s+jn6#qvuuu-c)qd`*gP+oOmCmVLAuoQmO_%MM{vya``o^9nBujgLk
zZ4T1@MlnWWG0lcd0MGYA9sRW5Wmw<9?}CW$wu`-H0lmqz8n^qrGFdhgUiQI4
zU04FX-+U+4mZ`LrC+3xa`5*r6kZW>Oby!qoe`IxCg?Eun7=ueOdKs;tC$L-4e>aK3EV*}>+kmW_UXmKhw>M@NH45Eg-nxp;H;TbuhMFDnJd
z&Fn$#2(v2v#jP;cn^=6u(eQ|u#aK>MxfN@e?~d9<9@0tWQ5eK9u>#J7lWJukJhHbm
zLt{p5WSL2d2~~78=7IL}n=^bE-cP+o8Y0i}YN&uz+(y(=
zQRWtP^SHTYO_7g_ix(e>JPHOdKDr?GBT!Yo$_J{b6dLoGZm}yuvigvw$p~`CI^Pb)aY@)wzgVRWVeWw1v}YT@fN96HjCCuGN#v`+|!Ml#6cK^
z|E%o6)<_nCJ`RO4b-r^WVujBhq#qif>(INUao7(A{DG4
z`^Bb)E+9(T+72*7dksbo6xB&WyhqD!uJie3?6fwd-S7d8VkYi6T`%4CPRVNK=ttd?
zO9N+z^%@e+KVsgEXWrjgFMlL}e_w%UD?2(|JaJPn>ksr2^}F
z4yux@wx3;8cp?GPtdi?8J?g5{f0$`&Wae3U6Yx2J@4N>$3vQan=I<*r*2Xdl#&?Zc
z!EU|H5$M5`w5;F*AZF0zPgGqgO7Sj!&^V~wml*G{SnsW^`&pOe6p$YZ
z@s+u_IDZyJ$xCFlB}0>
zaLP?&6v*W_^gL8EAvTuyH5nP%DHdq8zemxeaqGmyz`srS;JER1@r8p0uFcZY;?HoD
z$!REtoGs}6@1+KoHvOXCHGMGbCuPz&H*)pl!_gMmDOP%VlG97({o=S<_o;zlf?hgW
z!QTt@XIDSMLtlK(eM-OGz0gzO;*voXin1E@z45rPHEzSZ#<4wPfBf?AdVl(&g`tPs
z*Shj@c<^wzar0VoIS&>xj-&{Gv4soyriJ_d9I_C?CRu26FbI-202jq$fP_Vi063ffZ9v9qp;=8$71@ncZ)rzLG7&N;v+#Ni
zVFbK<5ud9EBX@g6Lw|SsG)-FM&yaDWw=;zVggQCG8&W=1@mq0mL?IEXxq<)p0#)1O
zW##Lu+1WJiuVz!xN=83|xt*=%vvZr8kU;DlyeXVk7Dvb*Ig%@sBQ3NQ?ES^v?OSu(
zSbX+9JE%%hWw>;JMTs&p)?1A!@tRtROhyqyae&E_SrKP65FkTnu~
zd@PV)v*41K{hT{LCX(?R!0z^Hs;>vCKKFkRd2I0pn$-~#{Xj<-@1~5*xQp7KsEDt0
zebU%v?WLo6_BkvtP#>T`+3i0hEf;j#)(eVr
zPvD!3nQE=J!sc)i&KvEHTp5+jXC2*H)-y<@ab)0hIVwIK@9mxRH`e2cYyYH<9?vyV
z*(~V;8^Vo^iGlk0&!0aLLY}clDE`Kg?~BYd%iG!p&T4^h+^zj7+Wx_MJ`;eUZGCgl
zW|=$?36z?|$;o=1Y~lmZ)>dJq5RJOV-#0~jNhJ9KnV3qz6JRpFooW03BDGmv5@wu_n5bM8YJGktODRJ*TlUQ7?T+Gvd->SYF9en^i;x3yUa`fEW2*{WmyEB-
z$XwuKkByBtNNQgqE3l%*-JE~9d3l|GnoR38`{za1_An%27!Nd2p1O8|BT-BMNZF;<
zSn&SwPfu
zG*8!S3rR`*q@>D)W2EgjIXc05=Yp=cXC9oBf!!PSzje=yI_Fq~;&>|}LL)^W2z5il
zR{YeJdZU9cfp=WV5tsBAS=4)maW_$?Lxp$n2i<9$NN7vM!!psEq
z`(z>OY(-X7kdsp-rw@5HJN#-?sIsfet=etRy}7C?y3qO@i&O~B^@SFS#s&`s=M#e@1D*Q=DjBrvG~Qf^77_k6#=$|*#Lo|{?Cd3cCi_fOkVLsfoAEJVW^V3yzNY0YftRIiaIuK7ug|Iq@Pq{gtM6tSfygwz
z&iwwkJ0w#3W@c;!;_K&kdLzthaB!MS2YN-G$!@WiIFlm}KqW6k|DinE=!UAhgybNp
z0g3+hQFOGLrU7Gobl<7@)A8?i1E9$f(>kJCA|w)vNO--a7o(_U?ix-xxY}sALKX6~
zP!+((Kzz03vL1Y%IOn8mz|4v;z5S7cy{5g=?6YgLex3=@GoHrKc8He8(QZ5i5G3L`
zr|g88cE4)`fCBJ3>dS0@nsJqjkMiEU8(jk%Nksl$?j{9w8AIjd<&i+974Ln-Iy)&i
zlSx1qjfUGt*5hew)s{jYTA^;%Y~h4L)dtrUv*^-IyPbhDS4RR_4-$0n=PD{u@ud(B
zF0S&hQk@MA*}x=sUjPojSA!$128|xC=`^{Mi_30OzK#WT=&!v`EYFAO0m<@KX%~UMISSPJMm-<6}nvT+TZOERe5kO&wt^lNFl2IrRD5{xA{bh^q+5`tyB?dh)NmYA-^|L8UsU8hJLHis
zquFc*0x>SzW(Wj0t}J2>>1g@9l&brx=6Nwtl`eFp+JyaW3N)ru*|jrnpsDLv?pkLk
zG6M>L!H_|OOnnxueT4mqp61A@$nJ#o-+FRGR8a7_PwRlWl(9ggqK$X
zaRY0nn3v1w6XM-C0@1(E>mYB$3Dz&EtbCe|g2v#W!eE5%f&s^^3kZbKSVo)d%0H;jg>8!$e-Ag)
zCJx{FuTE`;0drjtkJlH2Zwd#lK7S4o@$=A`r_qv*d4Y^_1)pgWp~q!lC>|Q0DoMeo
z#zkv*Y>M^ew>li)Fqa`DB($=!KzSj`LeE&D%^tVByxiu8^|QXd{_2MbWN#{8!&CdJ
z5?TR9FefpK+`~gP-q1zp+|Np2s)}J(((J0pZJ#}niJbkan|0?$%YLmwxe6fNpsWT1
zOFI$(@)yT^24Ma&FJE5BNl?Ew;`bUH?w=kT)0UCxADrwQocyvcojdsrle~H(Y83Pe
z_lBE>XSQounEu4Z*jN@}drKhX
zIa%>K5775T?jQ*8m3CxGcAji<>j$0Lv#UoVQEx7&GPznIAmK2I)sr`3^=P)^fgIf2gt~)`kQBWh|Yq#i}yk!86CbZu3!bH%LWcwoZYsTmDz*n8S!HyY@6~d=_^eP
zjH)D(&1B%ZLJ2X4sIB3Z{BRy*1Chfhea?wb=^UIi@?kWv+(88pOnR0
zmBTu`O7|&hQNwstL5#R3f@vc%sf(Q|ErvX*fSnX&cSc3+Q3+?Pk{`@Bf(<*FXn>CM
z+ofCu0dCi0BDPc^-GuDF#B5Ajotuh&eb;|(v7QCy`E3gH_wbC^b}
z&#bD5M{-zWU|X}LsOWo{Ux}iCo2IE;QwqgpAezxi)ZEU*?TIR5{LnUeuf~%O_AIeo
zKp-r=8R@;Q|3ik|{9lzuX3Jq~s~DRRWnhh!yJoQk3XnDC>G1=8Xm+{#aXq_DPEO9L
zYpt)p7aA1~zFEi71G}!ZOCVO7)kS2&-<|oPgi*aF?t3HdrbjBc)H1yQgoU$lXH8-CeQe%AwTbLPZUcT}YkC
zDnpq#JUz`Rn>xOmSgdRK_dyG3R-ldNtberR{}hKrrReE-bWaMR*?iY!G;+DnO;AMx
zL9a;5#yel+0kRMtBmmkVr(k$#WMstj?@zVM@Xk?x)FTEc^qWB`K#~KD_Vi*C(UGV+XMx0vi2QOxC6Z&t;-A_8z6!sB&XYc{r1WX=r*E7fVn&Z*JlevY^fg
z*QaLza@&c-^G?xBAdsl&EUUUfxfj3fr&_(Tz|De-<#vje_qA6u5cQ_k#Hst|6q;f^
z>Vu0KPti7Pu}dCguqEkf9Eu=YDb_@dKp#D3{IF23??r=Me0+DZ78WzDPWT>&zuP?w
zOqdiDcvI8U()`bN9L~zVw1bloRMJ>fFzlfYY%a5s7Kt|+Z%W#{t`R*w)V!$MTj^jqmlbjiYHoLI&Xt|1Y=1
zNDGdceU#1Vsio0!J;@#ekoTjY{mw-b;Jsy4hJ_&r%314~y$wc_`q#4oA-UiB<~p3=
zd!go7M+`BtbLn?%bYf1DyCrMmXcQiUL&NvmdmJ(Mdt2)d&}Sw#f|PkEKu#W+%#m1|
z$aZ7(r^xonM=C=9q;&oU<$dNq0Q6SfV|KdIat&W?GeHz@P=&-TOf}b40u8SKt%%Pj
zQ=5&YlEXg)jK>qhH7}yZ-=GI=k$Ei5K|xtc2ijX#-m@imHCAI(7{;rO;Df$PgMI$_
zK6&7Vb_M8u_ni?RbzU0aIKwQbB6Zi@=r@ZMSP|~!X_Ws?#*wEnc
zxH)H%)sB^=qg_0p_A+9J3xTqxVTI!vH=39@cwY30!$3yz9O;W9Efq$JU<*Hhr=-QD
zrN?$#a7Mhu#Ef`JNDjHYK&;%iw)%rUvJY3^WP)d1-cwatBCBwoPJEVp8JMm2xK|!e0(U32pJi6=_xE
z6>-smnem6Grm7z}8$7%&Z8t4zEns96AQIgkyMrGz6tgO-x{Zfj5ITv>*lX%^X}7xS
zGZ*(?d_3C+`-izd9OzIs{8$J7Xb8_`?fHL8h%WDR
zkm;b@97^_$lE?z-J?w*nz!vp1B27gzI-?h9sFZf6`lRT0O0I$zwvpw
zu}pKxyyFMoEw{;h0btpjuSlYq*47Ry#SW!}v3*=({(
zb{)6tY~(vn_*Cek%0$@uX$^tuhk6@WjmvHZL3ZVD<^q$DtF_T&Q(H5@4r)#-+ZvF_
zc6N7#gciq>*y~lI9C^YXE>piF_ba17u@uG!p1(M`^s%C)Wmz_C@wBfbiDx8m8$O02
zXFT8D-CkPIRe8(f4uF%hm<*h>o&$L>0M`Lc6gwP18yw#)nY4wz74S$+qKvf>qz_8LB1Z03#u_te^to`gs~GK3c~Dwg
zDoS#=$3i)~RRzcqPuBmjM%@EpTk4XDR
z9`6n*6O|1Z`FglKH5i(#w*Y*A>spzND`s#5)N%AVBn)hd)u#|pgZowm;aztX;U
z4BcqR93r6fL7ZLQk+$@jae%&q05S-{e6hW%1W`(h?@?0iVh>$sQVNtqg?f6{E2Dtyz0i=&jADuS=Ep^7pCa&61$4
z!;jFd)MO?;dy1-bVTj93)-$tE3z(Cg>~VM3%tZqns=-l0q`EChPf^*;ceH4rtIKIo
z*46MTSbL+^HfSHfP=6BX>g%!URZonqY6I3CB&y+Pg)ero|0Gd~FiU0@6=G^AdVi7q
zjaP}AOg{VVb4;n`K+@K2E0A-3Gj8_bZIIkOa|6gNwund
zU}oG1egk@Wd5IAgR^;AMAAl-@MX2a1SQ5hRc=Pi<3K=fqiv&8TKR&TrJDz|(N%i%_
zz;>Ze)oF$OFF+vFG}^6rF7-s?i>xRiIW#|KdQ+T
z28vn(@g2`hu|~*|5bre1U4lvii1JX73m2$@xT8it@~3LHA^~w=He*%Nh=dUDy{}J<
z!CVC7=mjWPyz1#UbZgb4e=TI-NHDhZ#(H-S|JV`44!MhaW==;#TS$-lgQew(*6VQT
zNmO!MwAo|7(XrQ6R0SJEtq$8JZU9Io(BZ>9TKs*Ih~=LLml!5A9)R?r7!LD$ewxKRbpBgPUtXh~H#iWTK8bA|z&fj;SP
zvp<9x1mX|Rmlmeu3%xCNw_5L2k5#2gA-bIQAD_Cqa!zY@p}ucESRqSE_cyjQYcf%T
zbk8@ZfE8QsZUNMY6{{ZNDu8-H)MI(CzMVzRZ)`p`j$qiiwqfb?exIlfr^JhLsKg(G
zAy+2_QPeX1A(N%mQi{jI!hQ>ozNjcT85j`%)f@o03(qr=W={&f3ed@ABgZ##+m08a
z*t7?VYkm(w_Epuj0|R62=O>ftz+B^2Z_}r2l(kYm908WC1a
ziI(Eddb`OlJ!VkjQ=WyBf5vLrAPvt70HVtH3w*E5=Um7w93OfPo6imab_tXf+(KMu
zKooJcl1BIvC4JP)<7gsdKP@9!il{`!(b7h_-hRpJB+5Z(+_3dE5x%jerp2d^6YcSp
z`vf)RPQ#|i_sF1-+?B!*u{x35JBnwYqq93x$f0ycC*Qp+78Tt1=6$9Mi^$YRHGTfw
z35vWAKvMJ<-AAK%4qD&;q*9ms@>_1YlBY5jXe&$-VE2hIpLYqL*&B-g8Ic+uf`7p?wkXl-u#Q`Vov>)>7~a(K-jM{;=Uhzpa@Ym+F2I#_MY5+Sm&4NzIkX0TYT
zAANmxeQ)>pwAgTF$;5Ka6fF-I^X0Tem~F=!GFe-w61|QcD^ijTQly1ca^Fi+#eh%PZoF%BS)DYCu2%^?^M9E4t6
zyi^J~kGAcl#oZC{Kl%QkAg5eh`4+fFC}#MVn+e{pe0&PH;7_gxfgAz?1{&_bM+ynE
zXqbL)PWV-C>wt`J-Q^vRK@ZeTW{RE_0A4QzOBTZvX~q0*8I$=Y^8s7T%6{}(z)ezF-Jn&qAqk1^{XI*nSjc`_L3`BKl91;hz}+Ag
zAxX8U*N`Gi1GVH419ks*Nc;8(VYDfJOf3=
z5ifG9gt>Le{oCrlCRLOnmp64~c1L&FN|RS+l1rgL$p^Y9gduwFp_eV3Du
zAQful7Xa?g#-6;w&g=yN0g(s6*o+#wD5&QyYjLda0V43&B*NLvC42H6CoM0NP$3|k
zu*bLC$#da5UZpGkIofh%)b7(i(D9C&IgOE!>#X#H6*;y;5yvdmhV&}@|Fi(W9MrAY
zT{eGxZZ9tv4)zIP1zw`eo9H0rD^J_dLVXH6TzppJs+71*k6$%Lb%!lX4f-s%mkcxI$QBYXDl;a<;hqf65yUM
z-ICgpn!v|79w@LNMm7^*E}N5>xA%Rg#P-Gmj+rvs~6*?HaRqYb+~8=`znw{TOy;3PyP=W58u#HP&#C;{6Wa0?CB@i
z04g8~WR`DV-YsS(R4*KM20$BK;GGdI*Uvs4R6vF59Ht+-bu>&a58U8ta!Sd3@KvbK
zH5rIDf(S*G{Prsa^4&_KUu8_gtB_m~hljnt&JX)sijq^S#Gy1{9=^;3mH5|;0FH`#
z2auk-?Xo`W*nfHyFN7SQ|JvWRb#7V)Dp~RzYzs2r>VGex8H=0RPoiG?Tca)4FGL^|
zjP&lFu1Wl6dx?*C^w+St;?4NYkSK%~@4B3-p}4r38b{_h7Z0y%b+_Q@d`|@(ZTAN<08o5k>mmzbk2vJD`zrEn*5Rjsb2C8L5
zR#v`Y?Ja58=-6hPZPn05T|2vBVq&N$%MIgi$@jb#VV&sn|
zp8*hOk&((xD>~&?I=NlHanYsx4ZpIpjV~@vtxJ@9P>Pvc93Kfy)z???Y7r^v--Z^Q
zRwqV%U`_1r?ZbGEB$!SSFAw^xTzFr5p$*p3w$fe>IgMqlVD*((Xy?;q%cW7cMtip2
zL1}C--*-*?1GqRu|35V-H#*2XwEv5#XR`{zzt-tV-k?1Yi@9psZ^RgwVSA<
z_dGVPHtvfI-vd%%Dw!y2`tr|Gxs&$x4tM^OZfEmvX5IT{-@LtXe}t#LeiJLp4%Aub
zBD!DO4i>4f-~!F0{yu7G=kk>Q<{gX0#dk{z44_307f1h$m3o0_Y9o|Fk;$9JlI`
zVC`yDs&7lqcrV0@fG?hdUcP+E%sd+VI(9){{}J`-@%n}V)aY@3)#U`GSooQhWi4(h
zr+4!V`M&tR`oGXCC`A;2FF`eyp06+h
zt?!A^4FoiXR=Fham-k0zWGyo3RK9zpQ+&(i(lrAp^EpMR83p?WCqG}@PzOG7ff
zrT?j&_CGK=RW_(F>ek_Ae?yrjFG4(=-WUA(b#k_}J9?{qyP+b+a>SSAG>QexPLz-^
ziLMVVmYc_B@&?qYm?XcQfJ)23?w{+gQ2m7P{J@Nl8+#U+adFQ<1`WrJ;Kzc%z_#?Z
z@>D-yR2`dWrjBKihYL^hofkzDHt6K^iW-Jpjc-F!S+X6fc~G6$lr$=`Os7mDvj~LK
zos&S%fc=T8$8OZ9frrFw322Ng^)(#zrzkS&MY+WzP(JXlJ>B5~Z-bUbjLn2H`e%J`
zQ`4CSK7KxSO^urt{I=M9G)?5_wq_luYH2bA^kq0?WFP9!y?xK|{imUjOqI4@$NYl7
zH5?+9VfF;YirRyvwh&65_9PYqfYUSY8OWx71S+LCg%6dqwRs6$#S5qH(g-B}J4^vP
zfPdK^Kg&$O{f=G~;^nw@zq|Jj=y#npak{bKO0FW_tnDPwAZYQ$ix)#G3}Q1=W~Hm=
z8vU;B&ivp%6TKLTnIhPcKf-D8Ob5*}?Vhe>Frs#VK8W!_`UE}Zc=Ca-`Oh0`uhs`1^u~CH%3z%@-{Xm
z(>gzD+UZtr$jJX&gVsT~$+~)n-j&nv|5Hi14Lk
zz+}QjBY!Sz*yPGmtofRRMBQiZeS}W#m8Nj?qRAC!fBuJFF1>Hq$26kbnQONe_`Z|L0Braq$!{N&^_(5#>K-tF{y`uG)qYuXVr1q1|C={_Kgs4vS@
z6yVLRp#8l6Rv~U+;J4m^07?i7>-{Gi_`-VCrwRX;$%qO82^x<)l?-OC3_nO?q{~SduE@!zYByt-e+nex|7B9H0+1?yZU5r7Ym!{n9H=5PxQpo`
zpJlb&KR)(cKgl=;lx@9zVZCP6xGxfiX#j`0KqlOJ4V379_%I$Dt3hqXVPXRHIky75
z3ODE7r*b7cKi8&Z?Ch__dV~9^rHJd{gI_1Ve(~8b6bm#Vh3a-p%4bU<%zR7
zdkd3*Z=i4%uRDKs^zGZX;6#wLBa|VV!RO2;eLd|;QoIa%cu`Y{C--M)m3*B%v)8!P
z_tYaVHa0ff|G(|SV+Z0iw|Q9EblsO$RvarTZ8vR#aH(ueOp4aw{~Lw+a+Ge&C@O!Q
z;J-f=@JN~@|64LRHUdt{{3o73bi(0c%>Q)9|L0SLRA_HzWS~U$A7|Fv>1DY_@*7&j
zpzA3SL%~u+fPCS)GQrDb<>vU|5@xH=iwHLPS}ba7c?lc^OTQ(puDu)5xjdJ8aj;Zl
z?w>4L8}7KA5Pp+J9bBQ@xhlYBfYL|6-<*CUEa!dm**=CY`t8+M$5>p51^0LER*WTZ
zA2ojdi2C^!3z8{qayjg0)!o`~`@mEr1t)5r#~4@OSbz&_&cVI(S_kaW@Q((i&p>?>
zic8}((}RVo-xRoR)1VC@IMEJGMG{z9sLpm{`I#%4FXqm);|@W?^kzqGAisadG|POp
z5Fq)e{N$7T&NHcN5L<)z3urznFaF7Rhy&RzTY6%jbqSv=b3p6UJCNt@<=j*_`NZ-t
zZaZP`F9eYW
zBmUAT-2#V}ed$HBTxsYZMH~oq1G{gcpApfcVdbPIPz&yDkkHJiH&l9&p`mm>uuN&J
zfXtoKIc#{L^g&hg4oaU>Cv~in&bMf!1|V`EQSg;?h@=|R>;ATD{OmCS%Gdw>b8(RP
zKm=)bU9@=P!VO5lj6AI5jaE=&nwyyoaMYimPQNvGZsO1-_ykfxmC^flakZ`;oNNnA
z$)fS`#
zTXWL-OxIjq{rR#@t_oP4+S7W`j_JTV5OZpx8JxDxjN6u>64}}=&pGs%u>IP^U5*8g
ziLro`-dGoqnVbs1f^hVaHu^jQ^|QBqnle?NH)}rbioGsYGENyz4RR&>fYXR9$}RQG
z9S>@`1Fnsx_B2y{ASd|9Eyk)*C`v;+WGLk_LOq4mOnboqwybOuzcuu!L=@8fto0=9
zx8B^kL4)^Mh6uqM^1C8#)X2)?=x4u+0@mVcs+NVot;}0ORCPgAdlNXN5_cn7+9qst
zodoscvC~hZqZu(Cu$hpf`w$Cc*QrT9HPuizK!cTpUWD0rD50+wZH$0@2AeR&WLEv
zyFF4HR1$)zQx;oksBkg0{hHT-Xq%6`n1p^lW`C><^)me$BuTftuJ_LXS9`w;=x`L#
z=5|OD#m{jlQb<_f%r6ACmBj1QZ+V~OBYUTq<@;i<`;mlyZYPFtWVvw-y4=0Cy<7lq&qYw&49Dff5pLli+5=mWtLDdH~q%^QlZ0
z0Tq+4Z*e@c;I!3u&Dj$HTuRT8k6@}h_eq%0Zu-tNx!URAm6D+!;|c4Vzsq<`{<&Dn
z3ovjH=JVh5Q+}+}8{4Sxr7<`b9!&JMKAqZUN0~~08w3$QdlE0R6x*=7yNJt+AO_Z6
zue4U|yrmfb!!IO2^kDui2!4;Z0jPib=5*1CCi10fw!CsK)A3VHBerL8
z9MM@>8b=!7ng#dsTXjuM6m&0geb+38oGUCerJSkQP(whVzv6m(|F=RU@d``p%?*I@
zVJ3D7PmD4lWX$tfz2Yd?54pxRR1}HgLwq^q{KvIh<$gG|-t5})-}$sK`+qVQ5Q9_N
z#DZL*p>K6`AU}4HRuexZHh*45rG4&^u|6$pGZm%aW;39WfxQa;S;`{^HuXpF206(|{F#n;G?>Je#%|isti4nHga-3~sN$vGpvc|@b
zBe${q+UM8y*YehDu5?d6i@vyk|IKH2;Eu#mv^V7*u4+EY^Z+`?B|z32;*SN%2qFFL
znrt_{E+CK)4h{~3Zs~O|zxk)!5$4mm2l<6t8;Pf=`SR5sFlUELG+po6P*m8$90R@aj7^Cn01_h&o5jy!YmnhE(>MON42o
z>G0%iX@?(y_)}g-&VA^|wZWitsL$!(*k8|x|A6pp<6@J6-5%sTf3NKCw~nu_7sDt5
z5u=GF)^C=YsQcgaKDYK|t*Br6hQDk{2gn0ZT6M2g$4nIIUN0)EEDT8ziZwO61{nf5
zObw)G=+)pfy>tKMq+mpMLG!D@Stg1m)yH%G9oi25Imy8Pv+e>Vy23a`b_>VJhwox=
zptUJ(G>}TV$fq+ks70aY_Se$aE&f9@KBb||={IFRYoPNkmNmlW;2zHnYWB%aPj%UR
zE-INW>38rVC;{~WSR+f3s$=rP#p$p`35lK_1nkU8|M*=sXYt^70v@?(>f*ooL&@g2)TCm!?j@6n=ix;sjr!m)XBLG_UxT4e)JgG
z^qkk0h;RT|XWQCcI-g*+=lOz=a>Q_#tWf
z^u!b9uD_3lR7j)V2dmaOW=*{AB?aHq#Th(dke?sHq~a>Fh+>t*QNzZH;*00NYQ}KQ
zjJENsqi3LghhS(L{j)<)M@NZP0xDZsyZo!6+swF6DD2|eV;~pcm6jM5@v=^H5DQ~^
zzzE8l$6he^wR5Z+SjBQGG_r_esV40@m!UfFdJaVFdf)>mn0x%$_1o84p|^$FmK|-h
zORCtW>#Q%=m4@X%FR_h}-zW;%B!oTsmo!=BY0FE1Pd3BGm^%WhB!>dqmMKY@1B
z!_){l3v(}WlBZ$!ZsB0e8dRTP64Bp`pH8h;n?7S6X`(u&|!xb5Vy)GIxyCh#py
zmxXQj0R3IUar~x5#1YN4^`(ZKRw($A+fG#SJeZhpV7>JMuG;{v*A4Xa#n;ayC2(&!
z6^!b}T|69TkzFCN1MWI}`OCQwb?wG=FnOp`hwF~JL~GKNI+Wsy7yQg*an9+C)=sf*
z+`MS9*V+nQaozkMe6X3JKevl({nCEu5n?S))oa;)tgy&5cLCnW
zV5m2;ilbL-B6pL#X$Bg3N8btS#rta7YvMcZQ$hHEV$Rv^3KdrrQ}xX*Ig(bt)+p+i
zCWd1#G3sP(?3m#*U!}s^YGLh)rzbyu^$UF
z{wGJYgH1r`&O-ZC|H%_8|4$c;IgU)a(F<8^*eQ@f+sa1+zTUj}
znw(P18~W+fe_uP1kx4DofB_yi(SXIX!bJ%nTMrsVae=G=jD8TCxZzMQAz}4+jcs0_
zs2gie9Q7W6Cz#Dkh62O;S+Os+Hsss^__*-^5Z#Zlh3~lS^Q-^RBf4#=PxlRQ|MO4B
z*O#-t#Cq=TN=TSLBR4VmZ?6pwP&IidJxFw{ym^Cg<}(wAl5PT1Fr4iE1IhkoCIEuE
z5p^8p*$^pg*j5~{DEwV%@UCN4s`f$bm3*8TJghOu3Wg6CTEpSW?K*kxS{CZiL
z9s&Pz#d}=Aw0VL``)CU}Fm=skZ^i|D@wb`(ZRk#srBY%h+WUrTP=lZusMtFiw3x>e
z##_y6R>S`r0(-Q6SgMg%Dp?U}1wj$-V0R&x=176i1sjuMvV4$lm%jEPosnM}!0hfW
zc*_`1T>Z<{_!CTQnyPL!5)wIa4Ab&}57Jl{@V~@W{}w%X0>mPaatfPgEz1re@L@YU
z+=zJroZA8oY$}F8I(e>K($A&Rt2hi_K;U;2txzV?wsoQsEeU5D8spav7ivgdI;gttuO#5)k--kW1wBrJP=GD=
zU_=40vnQGj@OoOp#6e;SQhGPb`5f|rD6WtR8qtABLtaSKeEJAES2m~o&C$5>6&!+0
z&{YKN_uE%%VB6GLt^in6rBgAg=GjZR_99qL^Gk?h#!*oC%%zlytzz4EIbVA^Rybs7
zfak{r#PSJ{6=38MZJDO1vOaoRf#eD*vJ9Y;`rx25jv9D?4U#4>S=u^(fgM|u(BfV#
z<45j0Xo-`j2Tv|wDlH1}wr;9`_9SqKDbs-wlh)4D{~NVuz+h{?5eWT&HQjxBuyZKD
zdQu-m3$7DMB2__ezYwcl+@J}I=~V9
z#CMeZ?}B#fmWuUd9!>U3a@7L>x6D`wUN|DXmP<8)mEzGeU^xe(O8k5r<+C7@1^*5QZFJORe;orKPqib^C
z#L~A;OX63Cb8?BAd$y99qn*n^><|;IswM+F1a$ZfBdBwDwg#E
zaQw5@jsiR-v+OI5C$^Zjk$zL9B|&R^kQ_L4a6MQ4VpmGRP?0fLxkWabq
ze(kvN-E<_j^4E)viF@acmH!pH{L++vQhCKtv*^1(M8@EPC3Pzo#7?|3e`|4xd}W$4
ze2-DzRphC|$@7ArnJzCNeGe{LxdXNn47nO8fuzCqs76v^qmrj;%l<<5uZ96RW(q%Q
zgBo7#VCIRYR*!elauWNuY8T!sQ$>T>2rdywo`;V|Ojy#p!p44OH9Y!E$-5la=~_8$
zTS1>*`T`jY(Z78mGiOB4o?MZ#k`tVL`~JUa$dku`wEeM
zGP6iSzDd5t^&jCLrQ#$c(bGqPCu!+5{q3rs*YP%7dgD3cP;_2cO
z<*&es0%cwaxp)Zl`IY#;(asSq=M>>C@%XVk-`_}Ou>Y0WFK2Wtn|L>Pxy3Yo{R}HU
zm^}+@#BJ)J&$WVe38p51fT?kv9Mvl4
z<;Qa_m+>QDvTCf>B~skhXy>(syTWRjMC<=*0oW7#^8MVNU273N4`QL0yh0Anm(u>d
zA#2{sY2SCRx|<3Quc;GWj9M;=9&6P5ugx0{RWl)tzm7n1&;EY8gcaBb(ZB{Mq|4N>
zu2iYB{N~QY6oj~t?MVY
zct$5O_|$wM8hD^x`(P(2?2Fw*<`n{JWhWQW^EVU0Wn4f`46ka2j1ptr76S9j|E7=2
z#p^hAxuRuKbc4yvI)2>qO(3NaqY>V`^8J$cm5F!yq<+LF@(xK$1;YiohJ5yOuZV^D
zp_wM{Ra5i0pM^G^$CN6{2d-IoKqmnCl$vql(TX3qr2~N{yAiCi>FOgNeRt7|V
zcO_8o#qO>TO4@!wH@$2y1oQ?-P!!+kYS6N&*LpsZD87Ynnn#+}1!VD~fC@`%co;FE
zl53U88ShowE>)thm{?onwII)Oguv6Qi_tB1r*Wg24fiZdM?D!p*N3h{2nL)*&cSjtAZ>T?Pm?nHJP(D8REoY+Y
z{PbeOg5Scy@2NONGbmM10IpB`-|M-C?j3ah3eh_pm&k+^@o#p8c7#;33k+;8c70}n
zzU{$L-UKGyzn5qGBjmWW3u9Fy(aA-ZbLKY5?l!1xvCNzW$u)X(YJ_@VyM(WkhP=uTBQj
zC1d+pF>Wdy}+Q%v;BGo|lH7q
zpB$0IEqO?`z8wfVv3Jjzr_m+7DJItn%_R^Bp?CgGY*lY@Xmd#|F_(0vGArG6u+U^+
zooUm#@HG<7?5jqPx?uew+reg*ZRJ7a;+=g+ZES11f+@dWC8Ni^VJR-+Z?KlcV`drH
zSrDPiBw1xK&ZYmU(o-}UpTI*(STb#=S0i?5IV-mEBE
z>W{?L)h#esR`vh(`mb=Mq2OER*5xC~l5<)Xu{Lo!$teBV2XZXv2}?8Pce7D~3d>43
zOPLJ*YHQDYd^HDgscE{&{G@A;f{H!wx>eoj`cvzViWgJRUG(~@S6%A7$v_)CY4Chm
z?h3;ib4)6}?&)v0V769=Z=TAg>aii3?<*c+&B?EwzrSm4RQb#r^_*}(r>GL9V|C%X
z(gG}~8%w*@nqSJa`p=(=>}yW*{3#H%Hs!Lp)g&4GV0e>M*hDk?P*9+i0eH7!)pAUYS(H~AEY5akE@r6-
zv0V7_stg~p3idZ?z)$7H6}@4z`PI}XuJxlgFYHanvD%)KpJTs@LMS&BtUubVVFG6U
z>AJtAL_CA^UH3P77s+%_dLj*LtB{rOQ{Cze#e?nPOAOqoT+B%oAuL?JpD
zyRg@bbK>TYo3!X3l1m5K5ftlFjdBvdN*dW$*3B!}Zv!;^l-%j6Y6~}Fh$Dd>8RV?(
z56*Xee($C${&IaEYwi~zY%Zg$1SO0N-=U?wB|eDnB(D%vS$x@Z;h*NwFE<PRH|wJYKs5nGe*ML|y@L=$*KpCa_fs8EmXtkzc)VVfY!as$?yXCX{n2K|qO1witFw!3Symoq0|xkC
z>n+g%U?E7_V%-2+oO`aXN50R~KLQN&7V(^2McG7U8|h#3n-SJ#1;(
zV3U;fhA}!j3oCa4fQi?(*hwZVYj6WGSgH4G)#!G)E|^Q*psl0v;fla0n&%j9Z?WbR
z5^$n`rGKLp`UgZX4)>A8#1YaG#)cj|-fK^w--ME!{@w1Ejc);^*gWYCh!uFpl+y{4_3owklg=J~T)
zf_^?O;sDje;;;0t`^UCnL3Xe|yk`^@HEDh4W|nPF9N#ZOD)j+~LiJnW_f02hJ5Krg
z{)(rlRZF+73F6|_zK!Rnjoo&Ee7FWWzFZGH_*y-aQGD%zOMfE|!%W`Qlyq$@d4kh=
zr2KBI4g#B9d2aN)Jg!uhcGIG*KVFeuh9G~^V$R)gW?)7V5+zE*)C;wuD|-F?<5
z=<8s2JP?_B7>9&^RyHU=udvg-yidW^cT?;sFj@Zm^W?H`E^^+a03pJB4eLYvz%`2^
zYXGz#{FP;CnRT91_e=AQdv0Ir?^8TvC#N1XOXGk1<)#7T1_v;v2;I!g+DEiJKzyQg
zqFxCV6dj;30FYd<$gFW#)cO`y+I`^ayes9v
zup#?CWdMuv{2yIp^;G`lqDR8J(<#T+W*U1AR<{*{HaYSDs>1{mC+ZT%$7udKoD7TE6~-yXS3vKkYss0j$c>M@%0zd
z4zhpB))#Qa$!C1gu`=C2dn!4I}m_HGovJZ=_
zju^V!h=h?xc1*($Gdm7wY;Ogw`8zWF0iy9eUNPOIFg9;pu%qH$@+?K3^>F8xsp+wb
zpm7Qn@(+{{Cg9cHsGrJ7WllLrhQke^XA{Ub;>CY1$Mo0^{57Q>A)x!%{pIHj%I%*D
zTmFet*nD+h?_q>Ri{GbP;;Rj9WeXIA{Z!_H=u-l(!!>v^na5XueS(KJgNwohbEF95
zbp<eb!Q$KqKUw=>-7&%QIdBnr9&t^RY>@|{?3o(w_^^Zm83857K_vG89Il`K*2WNtd-Z0}G{E-TI=4{MY#uc9TjaQONoL)
z!X=O9hNC&r%E>0T7hGlfXp~m4+*W+;CsMaUeW;~7$@lIh8yX|YH>!9>t!;A=?L-EN
zwL*}&R1kuRa@d@XcG%OlfAJnp_Tc{gY;W5_Eu~8!E1kl3g7W2WXD|VOuUBZUPhhT7
zV6InajXz~$C&k4)(&04Iti3h+w3Vb?fGw<04F|FceA}1^r?aY_NxOsCFK{>wFYkPL
zze1-%C3}9tE(xhuIMu<#X7F^e3!4~yHV)oMkTe-`bmVKVF5<)9iVIQQ-n}R6i3m%O
z646(8GAbiBOPwWM|NT6fM|Im(=0zZ4Q^;iXUJTDmQZ+588bY}|oF=G_RaW6JVJ_A6QY!(t>s!${Tgbi$Jb#)YDYJy(nXkG5c%O`A=Z095BN&9d-
ztK^k!_OV^WWC}h&qzA;Bwx-RKj!Qa_7{#
zq}S4dfkdTWnX2RhR#D1g2VhU$jwZAeu(5SXHB5>7PuaJ_5F6uMg2>UO~hWM{t{m4JF3sGd!Q1tX4{SH80Zje74s@d1I`o4;}_T2?zqh1W}|
zwCpKZ2}e&i#iMlNGpxv8eyb?HmpesNf-vcJGKH2=&8Q|+=@HE`zHzU&HVJGp{Vru~
z@W@XVWawfN&wjk`aj4D{f9iZoyq6UHz<1wf9c@RU6`1M%tj!;08>d!ht&`=6V~P
zgXBK~!1Nk(ot>SOZuQpN)P#h|?7N2!14p8dHo6>{u@j
zrZkF9%vSv(6vi5yQLeopnq;#+p@0m|rz`o!bY4zlbx1gx>GkVh2cBji9Tut5OaeK7
zvoBL{2A7U?*!jltkHWp_%s#Bzk(5N+?g{2Ct
z&}YCfV?oq|4@6pC4oM-?^|v%?{R<
z(})-%2brNthK7gJZp`B{ctWVT@A^>&mX>8G5>
zj7}3wZKiyq@DiVMq$ii~U98@Zt$eCURfFFIg(b;pgDV|Gf#s`w5mDC&`AKj-ml?lm
zq)bZhU~XzU&(XJK{iY{&-4PcieS!%0tHI16M|RLo7gRj}viD(fHqsszu3
zOqKQF5a2p{ickHhm&j4mKWs2c0m2IsgTI5FpZz&J*-9bV&gPGpgoMi78JOtmPwWN|
zV?b!|kHxYbkdOqw3bQUA00|zESk0neUWY`HQP5Rj4S^{(SWfmBON5OiGU~zyFI!9$
z(Iy-bMlP_;y30CVNIrUyreW?LOM9_U&2^5Hh-KA{_Z@kEV9l!{fn&y
zhgZJ9P6iQdHi%-`sGV(S=!3|G&GO3Pn^&+ZnsWo$msjI9Ga@aOul9aPCSYO<5)#9j*1U{*&0&_C4WNMbdnYL7qcEm4GaWSIHn?j@JQNG#0
z2G9Ql-;fnx)k1I|C|O9?vyUD5
zcqPJGU`BNY5Sfw!Ni0s_zW`_J^pCQO2O^0v^>@OtJ%}uhX5A!gTi&gVKfZojM4(*9
zmPs*Zv{KzPc(s)={k_u5M{8@LO-e6ICey*d%pkp~F8D_4o&w6QDlgC880TzvcCe(W
ztLkkjh-m@48^U}S@E@H?OW>zj?}s8Qx&!MHt>7ILpV`LR2$2Og*5Nwti)LbTzz#_m
z)G6ZZ7fSrsnbY1X;Uc%wP;04W_(rcv9XWW>2!bVrdT-V1Xc^JUzlYjO2Za}9+jU$=
z1JWQruN!w!p8>guLaV!-!r}4esUcoR!s3PYBs&WpPD9eT90q$qqgj_wUGqP_PC$64
zu>m%yBpQTIl?@OooZvB81Z;5Ui*(3EFdCB902hToecrz9VJT^EI;f&ymYp`n*y^1A
zOP4f)(Njl^j$Dq$PPv2qkMxcIEyljHCx5%rHx%qu26p1miN2d;t9?}eL3WY05Yq`9
z8ynLyl8fJs$&-2D65_NPzR&s13F^}tom%4Jaxtslo)iizDJ9D(u2pANdfKU^&zKNI
zG(%Q<6`-!Bol2rsSJ2I&2w)KNOs+(0`35e_t%%VXpJBF?q@<)EXjhGEsL7C2QNcwz
z5RwFY~i+gTy_mKz(3oflLjgtkN~9MKTYcxyG{I61Su}R
zN2bGdAfj}8)9q`P9O4813`fFg<$_}#@>gb&A+f`v0?$@_T14n@otTB$?^bi(Em{7d
z#yq(uT+T%H*VP?3!3p?hZePR9qB#YgHAuDyh@ZJOZUu`-`OjZF#7*0%HJj>aF4^-T
z_}Uxz?V(}aoPqG+EPtv`{pm&AguTbAIFV?i$mH8(aeal(;zvisS-(^`#=UKVi0~6`
zb!MS2nwE0sS5lRtLU8l^RzFJ{`E>~1z}fZZTBqN?uLV&n>V9YP9(xD)O~OF{M-=mS
zEDb9l)i>k$N$E}EzI8|Ql@(0Yn~qF`X#FXgG?~46l-MB6m2Ugfwv)Jb>cip&BtO6c
zbEBnb;gLC%_=UbGYiFB|M}64Oe~#TMtR
zSq-uuyEEQ&o54TZoL1pLkU!!!;UyO@qA^8-!}-gz<%T5@A>oBObPL0cMdMYg1s=_@
zuvG|iWnof=xlu_je=XfFRtL^`&4Tgfw&g>4PrItg#iBI2YhXH1VxWK93CVj$t%+Hu
z>^Y{0Z#oD+1TM(Nc2p`IV&0SMfG`-P7OrF`pm6sY+(g`4Hz4#XrqXg+?7@6`_2$z#
zI!^S|vdz=w%pO@CQE#R!Nl7SXy0aD{N<>hYR~K}iRj#FvhD($Cq4>Lk>8BHxVG7uOF$VN0YjUp&O56lcuKN!bjVH~*Bf
z1`QEwmA7YY>dBMwWZDkhLU$BSH<_#m1
zb}P1byU(;b>)z_5+Uk}(f7$jcU0)T4H>J}yybNt^&bCAQhlJO48PBNsSJJg&izZiK
zqjgkXi)T}5Roi6zYobS?cx!jA=hvkAPVWqr2udt%>75npHjB>f1Q~4?D|ouvHaLS)
z6f@uS#-8iGhILNuQ+SDP+0^~z0r6qI6pXkJhYw>_rdh!i)6irAy7rlve&561jl6OM
z^{d{n+vT`xBMYTow?=|7L7yso&rD_;B=y`j75aa(_i$9y>!VZKIk=rA|@})m0}l`kfSWR=3>@e!Rc7(9kFI^@(ItLgh*b
zxwYy&(@ML9iq{j<<_Yg4RK7stY*P8{7e}W%!dGLoU&`Zcj5IVz?>Qij;1OZZJCd%PUx2v3y#V%nruU1&~%HNGh
zB{p(1FqeskFd+7~sUHv@^E==LM*EXISjqfB&aXW0z-&*Db<
zXI&Pl=#++(-YypVaQN^JnYrciRc{HqBSN6rlrk`zsocG3TfmmRB`ZmFPSw-Vj*r=v
zUrmGtG&f^fTM6U#3?bL@(sK7pF@1!QOMwp24EsivzOVr5zBIw*7RIK)=FN9C9irSW
z^Y-;9y(IRdK-(Zb8$s0O6yB`wyR%twyb`V2#rgF;5_`eYpauJtVvKF?OltO&4&M{q
zJ{vU0WVUbf)-YSG2YtclHW(UH2<1cn8^2L7LTNzfyhKbj9Mr4Ra1bC3PNe7!V`ETA
zMV>Q)NMuP