Repository navigation
Improve Planning Time #13015
Description

Is your feature request related to a problem or challenge?
Follow on to #12950
@askalt added a benchmark for planning a benchmark with several aggregates. You can run it (with flamegraph) like
Some profiling
cargo flamegraph --root --bench sql_planner -- --bench physical_select_aggregates_from_200As can be seen from the flame graphs, a significant amount of the physical planning time is spent on creating ProjectionMapping. However, there are many other interesting places that can probably be made faster too


Describe the solution you'd like
It would be very nice to make this benchmark faster by optimizing these codepaths
Describe alternatives you've considered
Physical Planning could likely be made faster by optimizing EquivalenceProperty calculations. However, since it is a small part of the overall planning time maybe LogicalPlanning / SQLPlanning are better places to start
Additional context
No response
Reacted by Jax Liu and Austin Liu
Reacted by Jonathan Chen and Austin Liu
Activity
goldmedal commentedon Oct 19, 2024
I noticed this case has many aggregations (about 200). When planning an aggregation, the planner wraps a projection for it and creates the corresponding
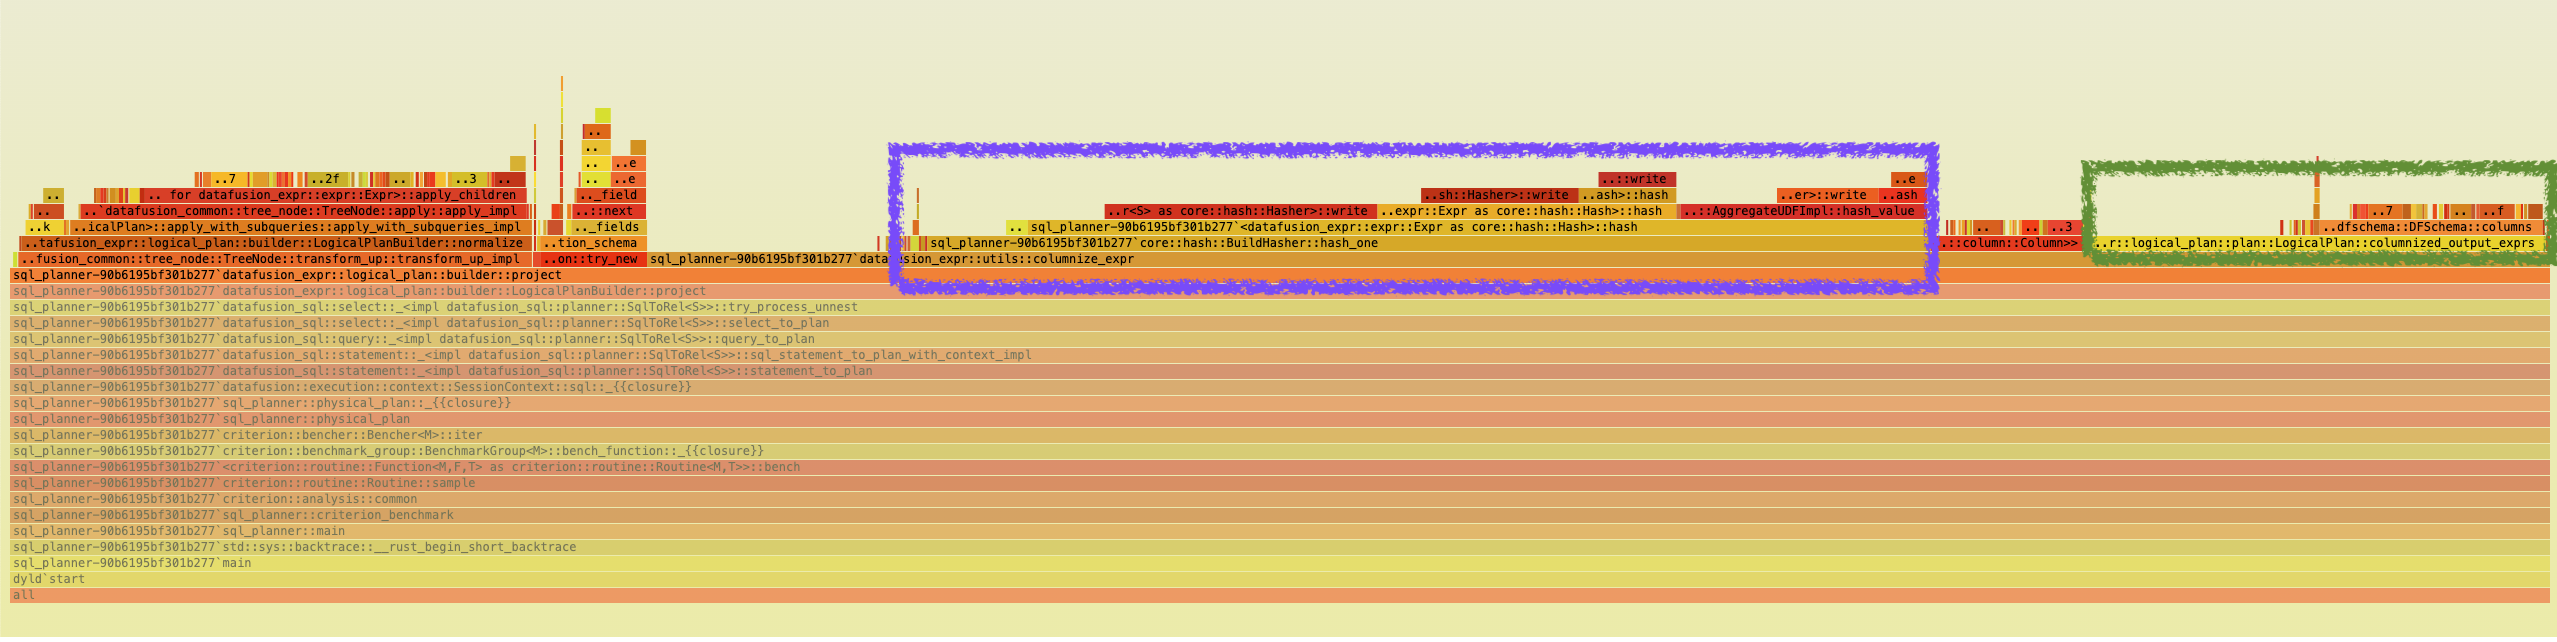
Columnfor the aggregation expressions. I guess it could be a potential bottleneck 🤔See the flamegraph, I highlight two parts:
I did a simple POC #13018 to avoid building the hash map and reduce the clone.
The benchmark result like as below.
all-afteris optimized.all-beforeismainbranch.Most queries don't be affected but we can see the case
physical_select_aggregates_from_200:It reduces about 15% execution time.
I think it could be a point that we can improve 🤔
I am still considering whether it is possible to avoid using
columnzied_output_exprs.alamb commentedon Oct 24, 2024
Thank you @goldmedal -- this is a nice analysis
alamb commentedon Oct 24, 2024
Here is another idea: #13018 (comment)
jonathanc-n commentedon Nov 8, 2024
@goldmedal May I ask how you made this benchmark comparison? Seems really nice to select specific queries to benchmark like this.
goldmedal commentedon Nov 8, 2024
I used critcmp to do it. Save the baseline for each test, then you can compare them.
jonathanc-n commentedon Nov 8, 2024
Thank you! Probably will be using it extensively in the future.
alamb commentedon Jan 13, 2026
I filed a new epic to track improving planning speed:
Let's move our discussion there and refresh any conversations / benchmarks to there