Repository navigation
[EPIC] Improved performance in H2O.ai benchmarks #13548
Description

Is your feature request related to a problem or challenge?
The basic aggregate functions like COUNT and SUM in DataFusion are very fast (see Apache DataFusion is now the fastest single node engine for querying Apache Parquet files)
However, many of the other aggregate functions are not particularly fast, and this shows up specifically on some of the H20 benchmarks
We saw this in the results in the 2024 DataFusion SIGMOD paper
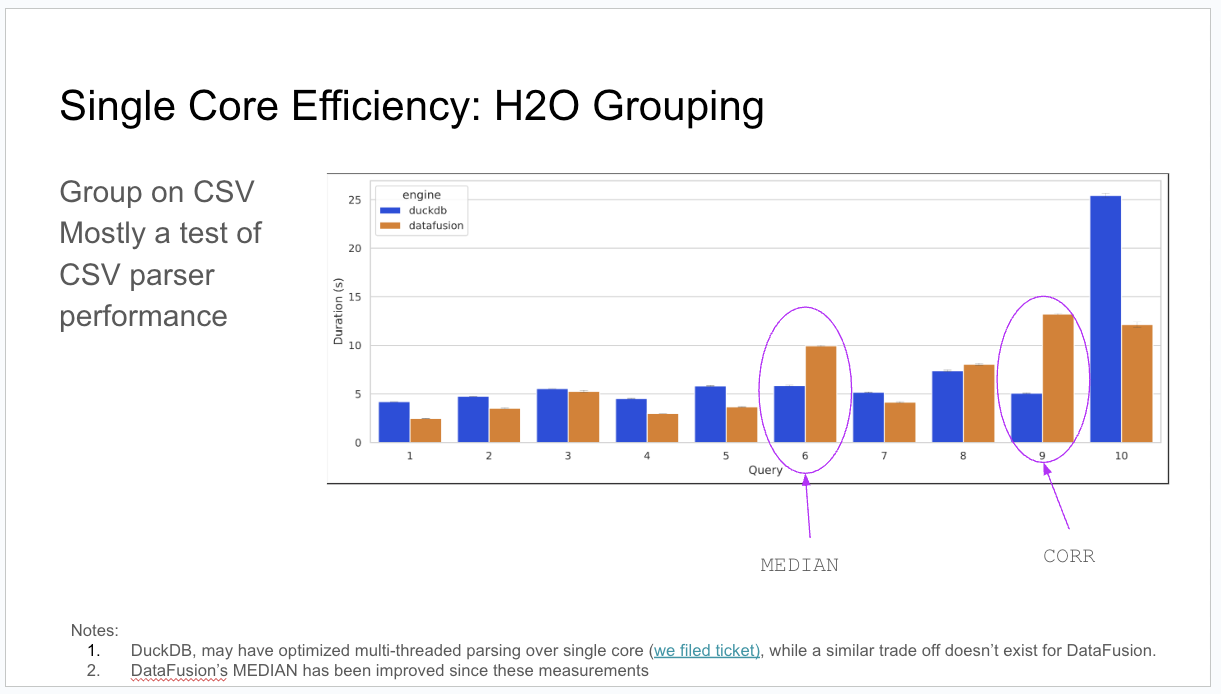
(BTW we have made median faster)
@MrPowers has also observed similar results on discord (link):
DataFusion was added to the h2o benchmarks (which are now maintained by duckdb) and DataFusion performs quite well for most of the "basic" groupby queries. It performs poorly for some of the advanced questions on the 50GB dataset. Here are the results:
https://duckdblabs.github.io/db-benchmark/
See his version of the benchmarks here
https://github.com/MrPowers/mrpowers-benchmarks
Testing
Functions
Other improvements
Describe the solution you'd like
DataFusion has two APIs ways to implement Aggregate functions like SUM and COUNT
- Easy (but slow) way:
Accumulator(api docs) - Fast (but complicated way):
GroupsAccumulator(api docs)
The basic aggregates are implemented using GroupsAccumulator and are part of DataFusions performance
This ticket tracks the effort to improve the performance of these for these "more advanced" aggregate functions, likely by implementing GroupsAccumulator
Describe alternatives you've considered
For each function listed above, ideally we would:
- Add a new benchmark. Either add a specific one for H20 benchmarks or add a query to the ClickBench extended benchmark Documentation Here in one PR
- Implement
GroupsAccumulatorfor the relevant aggregate function in a second PR (along with tests for correctness). We would use the benchmark to verify the performance
Here is a pretty good example of how @eejbyfeldt did this for STDDEV:
Additional context
No response
Activity
alamb commentedon Nov 24, 2024
For posterity, here is a link to the discord chat: https://discord.com/channels/885562378132000778/1309883046886903870/1309887744595595324
MrPowers commentedon Nov 25, 2024
Would like to note that the DataFusion performance really starts to lag when the dataset size grows.
Take a look at this query:
select id2, id4, power(corr(v1, v2), 2) as r2 from x group by id2, id4.When the dataset is 10 million rows, then Polars takes 3 seconds and DataFusion takes 3.6 seconds, so pretty similar.
When the dataset is 100 million rows, then Polars takes 126 seconds and DataFusion takes 2,100 seconds.
alamb commentedon Nov 25, 2024
What version are you working with?
@Rachelint has some ideas of how to improve this:
Dandandan commentedon Nov 25, 2024
Hm this seems something quadratic in nature?
Does it fully explain the dramatic difference? @MrPowers how do you generate the 10M vs 100M rows?
alamb commentedon Nov 25, 2024
I would also expect this to help (but it was merged and depends on when it is merged)
I think the right thing to do is to get the query / dataset and profile it
MrPowers commentedon Nov 26, 2024
@Dandandan - thanks to the great work by @SemyonSinchenko, it's easy to generate these datasets with falsa.
Here's the command to generate the 10 million row dataset:
falsa groupby --path-prefix=~/data --size SMALL --data-format PARQUET. Just useMEDIUMto generate the 100 million row dataset.Rachelint commentedon Nov 26, 2024
Thanks, I will profile and see what happen about the so long time cost in datafusion.
Rachelint commentedon Nov 26, 2024
🤔 I guess it may be caused by the similar reason of what we encountered during benchmarking in #11827
alamb commentedon Nov 26, 2024
Specifically that
powerandcorrneed to supportconvert_to_state?Rachelint commentedon Nov 27, 2024
I am not sure, but I think it maybe really related to
GroupAccumulatorAdapteras #11827?I am running and profiling it to find the answer.
2010YOUY01 commentedon Nov 27, 2024
I rerun the H2O Q9 with
GroupsAccumulatorforcorr(). See #13581h2o dataset is in
parquetformatI didn't reproduce the drastic slowdown in
mainbranch🤔MrPowers commentedon Nov 27, 2024
The h2o benchmarks are run on a Intel(R) Xeon(R) Platinum 8375C CPU @ 2.90GHz machine with 128 cores and 250 GB of RAM.
DataFusion groupby queries perform well on the 100 million row dataset (~5GB of data in a CSV file):
Some don't run with the 1 billion row dataset (~50GB of data in an uncompressed CSV file):
I am using a M3 Macbook with 16 GB of RAM. How much RAM does your machine have? Perhaps DataFusion only struggles with query 9 when the machine doesn't have lots of extra RAM.
Dandandan commentedon Nov 27, 2024
GroupsAccumulatorfor median/corr reduces memory usage (should be by quite a bit).Dandandan commentedon Nov 27, 2024
Looking at the benchmark results, I think query 8 is worth analyzing / optimizing as well:
#13548
2010YOUY01 commentedon Nov 28, 2024
This explains 👍🏼 I ran the benchmark on a macbook with 48G of ram.
It is likely Q9 requires > 16G RAM, and OS memory swapping caused the performance regression.
We should also take a look at how much memory does DataFusion consume for those queries, comparing to other systems. Thanks for the report.
Rachelint commentedon Nov 28, 2024
Yes, I run it today, and my machine has only 16GB memory too... and I found the query very very slow due to swapping, too...
alamb commentedon Dec 2, 2024
I think making DataFusion work better in lower memory situations would certainly be nice
[-][EPIC] Improved aggregate function performance[/-][+][EPIC] Improved aggregate function performance (faster H20.ai benchmarks)[/+]alamb commentedon Dec 13, 2024
Update here is that @2010YOUY01 has made
corrmuch better:I also dug up and connected the task to add the H20.ai queries to bench.sh. Check out
dfbench#7209 (comment)[-][EPIC] Improved aggregate function performance (faster H20.ai benchmarks)[/-][+][EPIC] Improved performance (driven by H20.ai benchmarks)[/+][-][EPIC] Improved performance (driven by H20.ai benchmarks)[/-][+][EPIC] Improved performance in H20.ai benchmarks[/+]MrPowers commentedon May 15, 2025
Just checking in here and noting that I'm seeing some significant gains in DataFusion 46 for queries 6 and 9 🚀 (compared to DataFusion 42). Amazing work team!
Dandandan commentedon May 15, 2025
Very nice! The current slowest contains a window function:
[-][EPIC] Improved performance in H20.ai benchmarks[/-][+][EPIC] Improved performance in H2O.ai benchmarks[/+]orlp commentedon May 16, 2025
@MrPowers Could you use
.collect(engine="streaming")for Polars?