Repository navigation
an example that shows the need for memory backpressure #2602
Description

In my work with large climate datasets, I often concoct calculations that cause my dask workers to run out of memory, start dumping to disk, and eventually grind my computation to a halt. There are many ways to mitigate this by e.g. using more workers, more memory, better disk-spilling settings, simpler jobs, etc. and these have all been tried over the years with some degree of success. But in this issue, I would like to address what I believe is the root of my problems within the dask scheduler algorithms.
The core problem is that the tasks early in my graph generate data faster than it can be consumed downstream, causing data to pile up, eventually overwhelming my workers. Here is a self contained example:
import dask.array as dsa

# create some random data
# assume chunk structure is not under my control, because it originates
# from the way the data is laid out in the underlying files
shape = (500000, 100, 500)
chunks = (100, 100, 500)
data = dsa.random.random(shape, chunks=chunks)

# now rechunk the data to permit me to do some computations along different axes
# this aggregates chunks along axis 0 and dis-aggregates along axis 1
data_rc = data.rechunk((1000, 1, 500))
FACTOR = 15


def my_custom_function(f):
    # a pretend custom function that would do a bunch of stuff along
    # axis 0 and 2 and then reduce the data heavily
    return f.ravel()[::15][None, :]

# apply that function to each chunk
c1 = math.ceil(data_rc.ravel()[::FACTOR].size / c0)
res = data_rc.map_blocks(my_custom_function, dtype=data.dtype,
                         drop_axis=[1, 2], new_axis=[1], chunks=(1, c1))

res.compute()
(Perhaps this could be simplified further, but I have done my best to preserve the basic structure of my real problem.)
When I watch this execute on my dashboard, I see the workers just keep generating data until they reach their memory thresholds, at which point they start writing data to disk, before my_custom_function ever gets called to relieve the memory buildup. Depending on the size of the problem and the speed of the disks where they are spilling, sometimes we can recover and manage to finish after a very long time. Usually the workers just stop working.
This fail case is frustrating, because often I can achieve a reasonable result by just doing the naive thing:
for n in range(500):
    res[n].compute()
and evaluating my computation in serial.
I wish the dask scheduler knew to stop generating new data before the downstream data could be consumed. I am not an expert, but I believe the term for this is backpressure. I see this term has come up in #641, and also in this blog post by @mrocklin regarding streaming data.
I have a hunch that resolving this problem would resolve many of the pervasive but hard-to-diagnose problems we have in the xarray / pangeo sphere. But I also suspect it is not easy and requires major changes to core algorithms.
Dask version 1.1.4
Activity
mrocklin commentedon Mar 18, 2019
Thanks for the writeup and the motivation @rabernat . In general I agree with everything that you've written.
I'll try to lay out the challenge from a scheduling perspective. The worker notices that it is running low on memory. The things that it can do are:
Probably it should run some task, but it doesn't know which tasks generate data, and which tasks allow it to eventually release data. In principle we know that operations like
from_hdf5are probably bad for memory and operations likesumare probably good, but we probably can't pin these names into the worker itself.One option that I ran into recently is that we could slowly try to learn which tasks cause memory to arrive and which tasks cause memory to be released. This learning would happen on the worker. This isn't straightforward because there are many tasks running concurrently and their results on the system will be confused (there is no way to tie a system metric like CPU time or memory use to a particular Python function). Some simple model might give a decent idea over time though.
We do something similar (though simpler) with runtime. We maintain an exponentially weighted moving average of task run time, grouped by task prefix name (like
from-hdf5), and use this for scheduling heuristics.This approach would also be useful for other resource constraints, like network use (it'd be good to have a small number of network-heavy tasks like
from-s3running at once), and the use of accelerators like GPUs (the primary cause of my recent interest).If someone wanted to try out the approach above my suggestion would be to ...
key_split)Worker.memory_monitorand maybe make a new oneself.readyand reprioritize?self.readywe only accept those that we think reduce memory use?There are likely other solutions to this whole problem. But this might be one.
martindurant commentedon Mar 18, 2019
but we do measure the memory usage of the inputs and outputs of functions that have run (not the internal transient memory), and also know whether running of a function ought to free the memory used by its inputs. If measurements were done on the prefix basis mentioned, there could be a reasonable guess at the memory implications of running a given task.
rabernat commentedon Mar 18, 2019
Thanks a lot for your quick response.
One quick clarification question... You say that a central challenge is that the scheduler
In my mental model, this is obvious from the input and output array shapes. If a task has an input which is 1000x1000 and an output which is 10x10, it is a net sink of memory. The initial nodes of the graph are always sources. I assumed that the graph must know about these input and output shapes, and the resulting memory footprint, even if it has no idea how long each task will take. But perhaps I misunderstand how much the scheduler knows about the tasks it is running.
Wouldn't it be easier to expose this information to the scheduler than it would be to rig up an adaptive monitoring solution?
mrocklin commentedon Mar 18, 2019
That's a good point, and it's much easier to measure :)
The scheduler doesn't know about shapes or dtypes of your arrays. It only knows that it is running a Python function, and that that function produces some outputs. You're thinking about Dask array, not Dask.
@martindurant 's suggestion is probably enough for your needs though.
martindurant commentedon Mar 18, 2019
I suppose the client does, at least for arrays, so there could be another route to pass along the expected output memory size of some tasks. In the dataframe case, the client might know enough, and in the general case, there could be a way for users to specify expected output size.
guillaumeeb commentedon Mar 18, 2019
Hi everyone,
This is a subject of interest to me too. But I thought that Dask tried already to minimize memory footprint as explained here. Obviously, this is not what @rabernat is observing, and I've seen the same behavior as him on similar use cases.
Couldn't we just give an overall strategy for the Scheduler to use? Like work on the depth of the graph first?
mrocklin commentedon Mar 18, 2019
The scheduler does indeed run the graph depth first to the extent possible (actually, it's a bit more complex than this, but your depth-first intuition is correct). Things get odd though if
sjperkins commentedon Mar 19, 2019
These issues also impact my use cases.
One thing I've considered is rather than creating a graph purely composed of parallel reductions:
is to define some degree of parallelism (2 in this example) and then create two "linked lists", where the results of a previous operation are aggregated with those of the current.
I haven't tried this out yet, so not sure to what extent it would actually help, but its on my todo list to mock the above up with dummy ops.
In this context it's probably worth re-raising Task Annotations again: dask/dask#3783, which in a complete form would allow annotating a task with an estimate of it's memory output. I started on it in #2180 but haven't found time to push it forward.
abergou commentedon Mar 19, 2019
This also affects my work-flow so I would be curious to see progress on it. On our end, writing out to disk doesn't help since disk is also a finite resource. We have a few workarounds such as adding artificial dependencies into a graph or submitting a large graph in pieces.
rabernat commentedon Mar 22, 2019
Thanks everyone for the helpful discussion. It sounds like @mrocklin and @martindurant have identified a concrete idea to try which could improve the situation. This issue is a pretty high priority for us in Pangeo, so we would be very happy to test any prototype implementation of this idea.
TomAugspurger commentedon Apr 17, 2019
I’ll be on paternity leave for at least the next two weeks (maybe longer, depending on how things are going). If this is still open then I’ll tackle it then.
rabernat commentedon May 22, 2019
Hi folks...I'm just pinging this issue to remind us that it remains a crucial priority for Pangeo.
TomAugspurger commentedon May 22, 2019
👍 it's on my list for tomorrow :)
TomAugspurger commentedon May 23, 2019
https://nbviewer.jupyter.org/gist/TomAugspurger/2df7828c22882d336ad5a0722fbec842 has a few initial thoughts. The first problem is that the rechunking from along just axis 0 to just axis 1 cause a tough, global communication pattern. The output of
my_custom_functionwill need input from every original chunk.So for this specific problem it may be an option to preserve the chunks along axis 0, and only add additional chunks along axis 1. This leads to a better communication pattern.
But, a few issues with that
I'll keep looking into this, assuming that a different chunking pattern isn't feasible.
(FYI @mrocklin the HTML array repr came in handy).
84 remaining items
sjperkins commentedon Jun 30, 2021
Really well done by all involved!
JSKenyon commentedon Jun 30, 2021
This does look like a huge improvement! I look forward to trying it out on my problems.
dcherian commentedon Jun 30, 2021
EXciting!
@gjoseph92 This happens all the time! See dask/dask#3595 (especially dask/dask#3595 (comment)) @mrocklin proposed a solution here: dask/dask#3595 . I use the
map_blocks(np.copy)trick frequentlygjoseph92 commentedon Jun 30, 2021
@dcherian thanks for the xref! dask/dask#3595 (comment) is exactly what I was thinking. (It wouldn't help with user code in
map_blockslike this case specifically, but since that's advanced, maybe that's okay.) I might like to take this on.mrocklin commentedon Jun 30, 2021
mrocklin commentedon Jun 30, 2021
I'm closing this out. If folks have other issues here though then I'm happy to reopen.
@rabernat , thank you for opening this originally. My apologies that it took so long to come to a good solution.
rabernat commentedon Jul 30, 2021
Which dask release do users need to be running to get this feature? My impression is 2021.07.0, correct?
mrocklin commentedon Jul 30, 2021
rabernat commentedon Aug 2, 2021
I am working on a blog post to advertise the exciting progress we have made on this problem. As part of this, I have created an example notebook that can be run in Pangeo Binder (including with Dask Gateway) with two different versions of Dask which attempts to reproduce the issue and its resolution.
New Dask version (2021.07.1): https://binder.pangeo.io/v2/gh/pangeo-gallery/default-binder/39f7202?urlpath=git-pull%3Frepo%3Dhttps%253A%252F%252Fgist.github.com%252Frabernat%252F39d8b6a396e076d168c24167b8871c4b%26urlpath%3Dtree%252F39d8b6a396e076d168c24167b8871c4b%252Fanomaly_std.ipynb%26branch%3Dmaster
Older Dask version (2020.12.1): https://binder.pangeo.io/v2/gh/pangeo-gallery/default-binder/b8d1c53?urlpath=git-pull%3Frepo%3Dhttps%253A%252F%252Fgist.github.com%252Frabernat%252F39d8b6a396e076d168c24167b8871c4b%26urlpath%3Dtree%252F39d8b6a396e076d168c24167b8871c4b%252Fanomaly_std.ipynb%26branch%3Dmaster
The notebook uses the following cluster settings, which is the biggest cluster we can reasonably share publicly on Pangeo Binder:
It includes both the "canonical anomaly-mean example example" with synthetic data from #2602 (comment) (referenced by @gjoseph92 in #2602 (comment)) as well as a similar real-world example that uses cloud data.
I have found that the critical performance issues are largely resolved even in Dask 2020.12.1 when I use
options.environment = {"MALLOC_TRIM_THRESHOLD_": "0"}. For the synthetic data example, the older Dask version (pre #4967) is just a few s slower. For the real-world data example, the new version is significantly faster (2 min vs. 3 min), but nowhere close to the 6x increases reported above. But if I don't setMALLOC_TRIM_THRESHOLD_, both clusters crash. This leads me to conclude that, for these workloads,MALLOC_TRIM_THRESHOLD_is much more important than #4967.My questions for the group are:
MALLOC_TRIM_THRESHOLD_makes the biggest differences for these climatology-anomaly-style workloads, is there an alternative workflow that would better highlight the improvements of Co-assign root-ish tasks #4967 for the blog post?MALLOC_TRIM_THRESHOLD_=0on all of our clusters?(edit below)
I am now trying to run this example, which should presumably reproduce the issue better.
rabernat commentedon Aug 2, 2021
Latest edit:
I ran a slightly modified version of the "dougiesquire's climactic mean example" and added it to the gist. The only real change I made was to also reduce over the
ensembledimension in order to reduce the total size of the final result--otherwise you end up with a 20GB array that can't fit into the notebook memory.climactic mean example code
Using
MALLOC_TRIM_THRESHOLD_=0and comparing Dask 2020.12.0 vs. 2021.07.1, I found 6min 49s vs. 4min 13s. This is definitely an improvement, but very different from @gjoseph92's results ("main + MALLOC_TRIM_THRESHOLD_=0: gave up after 30min and 1.25TiB spilled to disk (!!)")So I can definitely see evidence of an incremental improvement, but I feel like I'm still missing something.
RichardScottOZ commentedon Aug 2, 2021
Thanks Ryan. Have not tested this on anything seriously large, but hopefully will soon.
dcherian commentedon Nov 18, 2021
This thread is a confusing mix of many issues. The
slicevscopyissue is real, but doesn't affect groupby problems since xarray indexes out groups with a list-of-ints (always a copy) [except for resampling which uses slices].This example (from @dougiesquire I think) has chunksize=1 along
init_datewhich is daily frequency. Xarray's groupby construct a nice graph for this case so it executes well (it'll pick out all chunks with january data and applydask.array.mean; this is embarrassingly parallel for different groups). If it doesn't execute well, that's up to dask+distributed to schedule it properly. Note that the writeup in ocean-transport/coiled_collaboration#17 only discusses this example.The earlier example:
ds.salthas chunksize=4 along time with a monthly mean in each timestep so there are 4 months in a blockSo
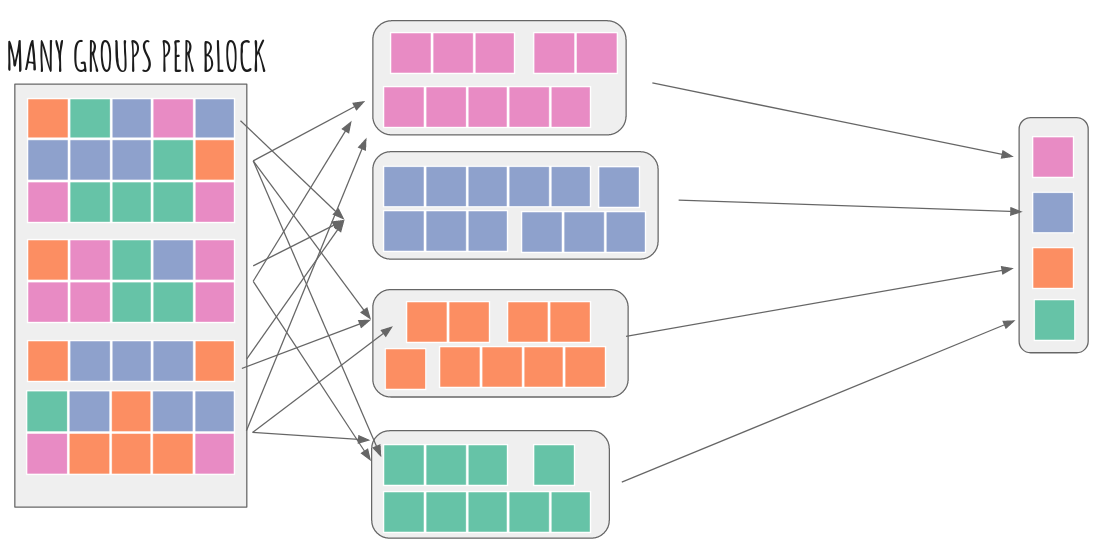
groupby("time.month")splits every block into 4 and we end up with a quadratic-ish shuffling-type workload that tends to work poorly (though I haven't tried this on latest dask)The best way to reduce the GODAS dataset should be this strategy: https://flox.readthedocs.io/en/latest/implementation.html#method-cohorts i.e. we index out months 1-4 which always occur together and map-reduce that. Repeat for all other cohorts (months 5-8, 9-12) and then concatenate for the final result.
One could test this with
flox.xarray.xarray_reduce(ds.salt, ds.time.dt.month, func="mean", method="cohorts")and potentially throw inengine="numba"for extra fun =) Who wants to try it?!gjoseph92 commentedon Oct 12, 2022
Though this issue is closed, I imagine that most of you following it are still interested in memory usage in dask, and might still be having problems with it. It's possible that closing this with #4967 was premature, but I'm hoping that #6614 actually addresses the core problem in this issue.
If you are (or aren't) having problems with workloads running out of memory, please try out the new
worker-saturationconfig option!Information on how to set it is here. And please comment on the discussion to share how it goes:
These are benchmarking results showing significant reductions in peak memory use:
We're especially interested in hearing how the runtime-vs-memory tradeoff feels to people. So please try it out and report back!
Lastly, thank you all for your collaboration and persistence in working on these issues. It's frustrating when you need to get something done, and dask isn't working for you. The examples everyone has shared here have been invaluable in working towards a solution, so thanks to everyone who's taken their time to keep engaging on this.
RichardScottOZ commentedon Jan 8, 2023
Thanks @gjoseph92