Repository navigation
[Bug]: Follow-up messages fail with active-writer error while background work continues #14189
Description

Area
Desktop app / server, Codex thread handling
What happened
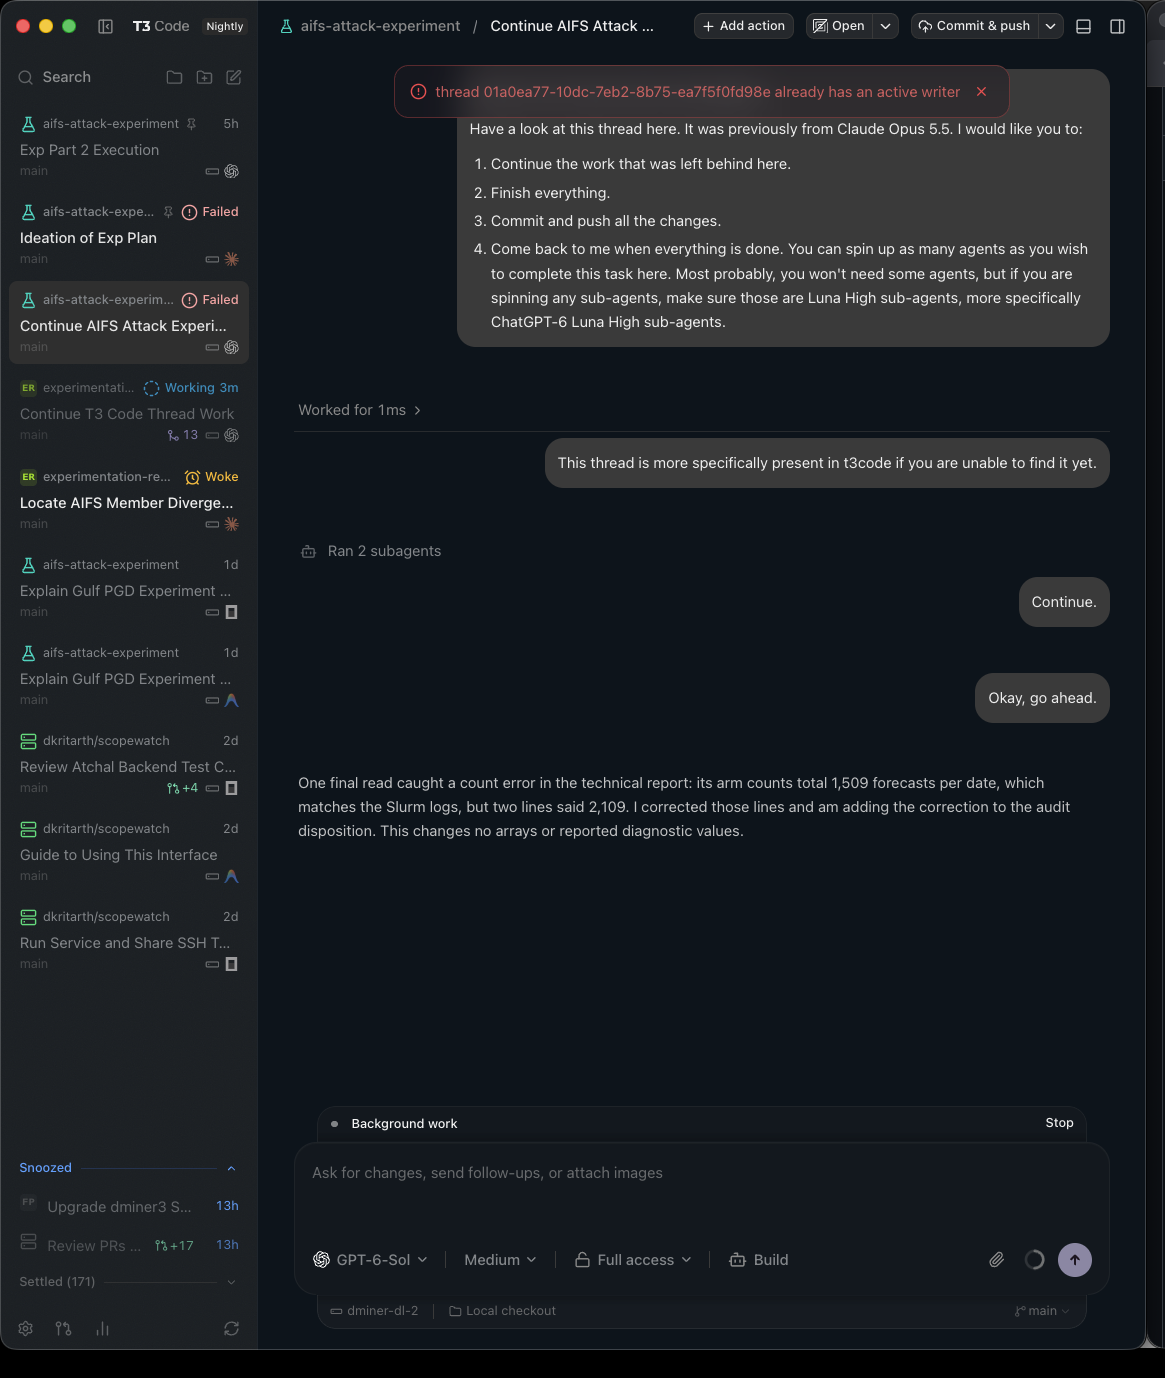
On the latest T3 Code Nightly, attempts to type or send follow-up messages in one thread have failed three times. T3 shows a red error banner:
thread 01a0ea77-10dc-7eb2-8b75-ea7f5f0fd98e already has an active writer
The same thread still shows "Background work" with a Stop control, and the agent's work continues. The sidebar marks the thread "Failed" even while the conversation shows ongoing work. This makes it unclear whether the new message was accepted and whether it is safe to retry.
Steps observed
- Open an active Codex thread in the desktop app.
- Type or send a follow-up message while background work is running.
- Observe the active-writer error and failed state while work continues.
This happened three times in the same thread. I do not have a reliable minimal reproduction or a confirmed cause.
Expected behavior
Follow-up messages should either reach the running thread or be held until it can accept them. If a message fails, the UI should clearly indicate its status without making ongoing work look stopped.
Environment
- T3 Code Nightly, latest available on September 28, 2026; exact build number not captured
- macOS desktop app
- Codex provider, GPT-6-Sol shown in the screenshot
Related issue
#8259 also reports an active-writer error, mainly after switching Codex provider instances. I have not established whether instance switching was involved here. This report captures the repeated failure during background work and the conflicting running/failed UI states.
Screenshot
The screenshot shows the active-writer banner, "Failed" in the sidebar, and "Background work" with Stop in the thread.
Activity
juliusmarminge commentedon Sep 29, 2026
Triage
This is a real bug. The conflicting UI matches current code. It is related to #8259, but it is not the same report, so this should stay open.
The red banner is Codex refusing a second writer.
thread <id> already has an active writeris raised fromthread/resume/thread/startinopenCodexThread(apps/server/src/provider/Layers/CodexSessionRuntime.ts) and stored as the sessionlastError. A follow-up on a session T3 already has open isturn/starton that connection, and Codex allows that in-session. This error means the send tried to open the thread again while some writer still held it. The new message was not accepted. Retrying takes the same lock, which matches the three failures on this thread.That failure is written as
session.status = "error"insetThreadSessionErrorOnTurnStartFailureand does not clear background liveness. Liveness is cleared only onsession.exited. The sidebar then prefers Failed over background liveness (resolveSidebarThreadStatusinapps/web/src/components/Sidebar.logic.ts).derivePhasetreatserroras disconnected, so the composer is not "working" and the thread still shows the Background work banner with Stop. The sidebar and the thread are describing two different facts: the follow-up failed, and the previous writer is still running. Nothing says the new message was dropped.The in-repo path that resumes without stopping the live writer first is an instance switch.
ProviderService.startSessionstill starts the target adapter beforestopStaleSessionsForThread. That is the bug in #8259, and it is not fixed on main. A follow-up that does not change instance should reuse the open session and should not produce this error. The other way to get it is an external holder (Codex Desktop, or a secondt3 serveon the same Codex home), which is also discussed on #8259.This report is the follow-up UX: a failed send during live background work should leave the thread looking in progress, and should say the message was not delivered. #8259 does not cover that.
One server trace around a failure would separate the triggers. The useful lines are
provider command reactor restarting provider session(instanceChanged,currentInstanceId,desiredInstanceId) versus a resume with no live session. Also whether Codex.app or another T3 server was using the same Codex home.Until then, Stop on the Background work banner, or fully quit the other Codex or T3 process that owns the thread. Send again after that banner clears. Further retries while it is up will fail the same way.
juliusmarminge commentedon Oct 8, 2026
@dkritarth, the code behind this error has changed a lot since this was filed. The nightly from Sep 28 still ran orchestrator V1, and the code path named in the triage above (
CodexSessionRuntime.openCodexThread) was removed when orchestrator V2 shipped to nightly on Oct 2.Could you check whether it still happens on a current nightly?
already has an active writer, please include:npx t3, or a background service). That case is tracked in [Bug]: Desktop starts a second backend against the background service database #6097.~/.t3/userdata/logs/provider/) around the failed senddkritarth commentedon Oct 8, 2026
Fixed for me now.
Thanks for the update. Appreciate your work a lot.
juliusmarminge commentedon Oct 21, 2026
Tested on e27a03e using an isolated web/server instance with Codex. After the parent ended with an async
sleep 90child running, composer andt3_thread_sendfollow-ups both started and received replies without errors. What exact nightly and Codex CLI versions reproduce this now, and was a provider-instance switch or PR watch involved?t3dotgg commentedon Oct 21, 2026
Note
🤖 Claude Opus 5.5 responding on behalf of Theo
Thanks for the report. This is fixed on main in #2829. Please test on the nightly built from main on 2026-10-21, or on the next stable release. If the problem still occurs there, please open a new issue that links to this one, with your version and steps to reproduce it.